TopPodcast.com
Menu
  • Home
  • Top Charts
  • Top Networks
  • Top Apps
  • Top Independents
  • Top Podfluencers
  • Top Picks
    • Top Business Podcasts
    • Top True Crime Podcasts
    • Top Finance Podcasts
    • Top Comedy Podcasts
    • Top Music Podcasts
    • Top Womens Podcasts
    • Top Kids Podcasts
    • Top Sports Podcasts
    • Top News Podcasts
    • Top Tech Podcasts
    • Top Crypto Podcasts
    • Top Entrepreneurial Podcasts
    • Top Fantasy Sports Podcasts
    • Top Political Podcasts
    • Top Science Podcasts
    • Top Self Help Podcasts
    • Top Sports Betting Podcasts
    • Top Stocks Podcasts
  • Podcast News
  • About Us
  • Podcast Advertising
  • Contact
Not in our directory?
Add Show Here
Podcast Equipment
Center

toppodcastlogoOur TOPPODCAST Picks

  • Comedy
  • Crypto
  • Sports
  • News
  • Politics
  • True Crime
  • Business
  • Finance

Follow Us

toppodcastlogoStay Connected

    View Top 200 Chart
    Back to Rankings Page
    Technology

    LessWrong (Curated & Popular)

    Audio narrations of LessWrong posts. Includes all curated posts and all posts with 125+ karma.

    If you’d like more, subscribe to the “Lesswrong (30+ karma)” feed.

    Advertise

    Copyright: © 2023 LessWrong Curated Podcast

    • Apple Podcasts
    • Google Play
    • Spotify

    Latest Episodes:
    “The ‘Think It Faster’ Exercise” by Raemon Feb 09, 2025
    Show notes

    Ultimately, I don’t want to solve complex problems via laborious, complex thinking, if we can help it. Ideally, I'd want to basically intuitively follow the right path to the answer quickly, with barely any effort at all.
    For a few months I've been experimenting with the "How Could I have Thought That Thought Faster?" concept, originally described in a twitter thread by Eliezer:
    Sarah Constantin: I really liked this example of an introspective process, in this case about the "life problem" of scheduling dates and later canceling them: malcolmocean.com/2021/08/int…
    Eliezer Yudkowsky: See, if I'd noticed myself doing anything remotely like that, I'd go back, figure out which steps of thought were actually performing intrinsically necessary cognitive work, and then retrain myself to perform only those steps over the course of 30 seconds.
    SC: if you have done anything REMOTELY like training yourself to do it in 30 seconds, then [...]
    ---
    Outline:
    (03:59) Example: 10x UI designers
    (08:48) THE EXERCISE
    (10:49) Part I: Thinking it Faster
    (10:54) Steps you actually took
    (11:02) Magical superintelligence steps
    (11:22) Iterate on those lists
    (12:25) Generalizing, and not Overgeneralizing
    (14:49) Skills into Principles
    (16:03) Part II: Thinking It Faster The First Time
    (17:30) Generalizing from this exercise
    (17:55) Anticipating Future Life Lessons
    (18:45) Getting Detailed, and TAPS
    (20:10) Part III: The Five Minute Version
    ---
    First published:
    December 11th, 2024
    Source:
    https://www.lesswrong.com/posts/F9WyMPK4J3JFrxrSA/the-think-it-faster-exercise
    ---
    Narrated by TYPE III AUDIO.


    “So You Want To Make Marginal Progress...” by johnswentworth Feb 08, 2025
    Show notes

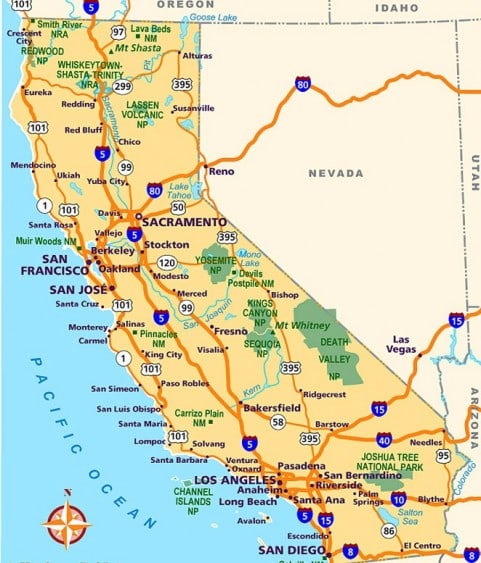
    Once upon a time, in ye olden days of strange names and before google maps, seven friends needed to figure out a driving route from their parking lot in San Francisco (SF) down south to their hotel in Los Angeles (LA).
    The first friend, Alice, tackled the “central bottleneck” of the problem: she figured out that they probably wanted to take the I-5 highway most of the way (the blue 5's in the map above). But it took Alice a little while to figure that out, so in the meantime, the rest of the friends each tried to make some small marginal progress on the route planning.
    The second friend, The Subproblem Solver, decided to find a route from Monterey to San Louis Obispo (SLO), figuring that SLO is much closer to LA than Monterey is, so a route from Monterey to SLO would be helpful. Alas, once Alice [...]
    ---
    Outline:
    (03:33) The Generalizable Lesson
    (04:39) Application:
    The original text contained 1 footnote which was omitted from this narration.
    The original text contained 1 image which was described by AI.
    ---
    First published:
    February 7th, 2025
    Source:
    https://www.lesswrong.com/posts/Hgj84BSitfSQnfwW6/so-you-want-to-make-marginal-progress
    ---
    Narrated by TYPE III AUDIO.
    ---
    Images from the article:
    undefinedApple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.
    “What is malevolence? On the nature, measurement, and distribution of dark traits” by David Althaus Feb 07, 2025
    Show notes Summary
    In this post, we explore different ways of understanding and measuring malevolence and explain why individuals with concerning levels of malevolence are common enough, and likely enough to become and remain powerful, that we expect them to influence the trajectory of the long-term future, including by increasing both x-risks and s-risks. For the purposes of this piece, we define malevolence as a tendency to disvalue (or to fail to value) others’ well-being (more). Such a tendency is concerning, especially when exhibited by powerful actors, because of its correlation with malevolent behaviors (i.e., behaviors that harm or fail to protect others’ well-being). But reducing the long-term societal risks posed by individuals with high levels of malevolence is not straightforward.
    Individuals with high levels of malevolent traits can be difficult to recognize. Some people do not take into account the fact that malevolence exists on a continuum, or do not [...]
    ---
    Outline:
    (00:07) Summary
    (04:17) Malevolent actors will make the long-term future worse if they significantly influence TAI development
    (05:32) Important caveats when thinking about malevolence
    (05:37) Dark traits exist on a continuum
    (07:31) Dark traits are often hard to identify
    (08:54) People with high levels of dark traits may not recognize them or may try to conceal them
    (12:17) Dark traits are compatible with genuine moral convictions
    (13:22) Malevolence and effective altruism
    (15:22) Demonizing people with elevated malevolent traits is counterproductive
    (20:16) Defining malevolence
    (21:03) Defining and measuring specific malevolent traits
    (21:34) The dark tetrad
    (25:03) Other forms of malevolence
    (25:07) Retributivism, vengefulness, and other suffering-conducive tendencies
    (26:56) Spitefulness
    (28:15) The Dark Factor (D)
    (29:29) Methodological problems associated with measuring dark traits
    (30:39) Social desirability and self-deception
    (31:14) How common are malevolent humans (in positions of power)?
    (33:02) Things may be very different outside of (Western) democracies
    (33:31) Prevalence data for psychopathy and narcissistic personality disorder
    (34:20) Psychopathy prevalence
    (36:25) Narcissistic personality disorder prevalence
    (40:38) The distribution of the dark factor + selected findings from thousands of responses to malevolence-related survey items
    (42:13) Sadistic preferences: over 16% of people agree or strongly agree that they “would like to make some people suffer even if it meant that I would go to hell with them”
    (43:42) Agreement with statements that reflect callousness: Over 10% of people disagree or strongly disagree that hurting others would make them very uncomfortable
    (44:45) Endorsement of Machiavellian tactics: Almost 15% of people report a Machiavellian approach to using information against people
    (45:20) Agreement with spiteful statements: Over 20% of people agree or strongly agree that they would take a punch to ensure someone they don’t like receives two punches
    (45:57) A substantial minority report that they “take revenge” in response to a “serious wrong”
    (46:44) The distribution of Dark Factor scores among 2M+ people
    (49:17) Reasons to think that malevolence could correlate with attaining and retaining positions of power
    (49:47) The role of environmental factors
    (52:33) Motivation to attain power
    (54:14) Ability to attain power
    (59:39) Retention of power
    (01:01:02) Potential research questions and how to help
    (01:17:48) Other relevant research agendas
    (01:18:33) Author contributions
    (01:19:26) Acknowledgments
    (01:20:10) Appendices
    The original text contained 67 footnotes which were omi

    “How AI Takeover Might Happen in 2 Years” by joshc Feb 07, 2025
    Show notes
    I’m not a natural “doomsayer.” But unfortunately, part of my job as an AI safety researcher is to think about the more troubling scenarios.
    I’m like a mechanic scrambling last-minute checks before Apollo 13 takes off. If you ask for my take on the situation, I won’t comment on the quality of the in-flight entertainment, or describe how beautiful the stars will appear from space.
    I will tell you what could go wrong. That is what I intend to do in this story.
    Now I should clarify what this is exactly. It's not a prediction. I don’t expect AI progress to be this fast or as untamable as I portray. It's not pure fantasy either.
    It is my worst nightmare.
    It's a sampling from the futures that are among the most devastating, and I believe, disturbingly plausible – the ones that most keep me up at night.
    I’m [...]
    ---
    Outline:
    (01:28) Ripples before waves
    (04:05) Cloudy with a chance of hyperbolic growth
    (09:36) Flip FLOP philosophers
    (17:15) Statues and lightning
    (20:48) A phantom in the data center
    (26:25) Complaints from your very human author about the difficulty of writing superhuman characters
    (28:48) Pandoras One Gigawatt Box
    (37:19) A Moldy Loaf of Everything
    (45:01) Missiles and Lies
    (50:45) WMDs in the Dead of Night
    (57:18) The Last Passengers
    The original text contained 22 images which were described by AI.
    ---
    First published:
    February 7th, 2025
    Source:
    https://www.lesswrong.com/posts/KFJ2LFogYqzfGB3uX/how-ai-takeover-might-happen-in-2-years
    ---
    Narrated by TYPE III AUDIO.
    ---
    Images from the article:
    undefinedundefinedundefinedundefined

    “Gradual Disempowerment, Shell Games and Flinches” by Jan_Kulveit Feb 05, 2025
    Show notes

    Over the past year and half, I've had numerous conversations about the risks we describe in Gradual Disempowerment. (The shortest useful summary of the core argument is: To the extent human civilization is human-aligned, most of the reason for the alignment is that humans are extremely useful to various social systems like the economy, and states, or as substrate of cultural evolution. When human cognition ceases to be useful, we should expect these systems to become less aligned, leading to human disempowerment.) This post is not about repeating that argument - it might be quite helpful to read the paper first, it has more nuance and more than just the central claim - but mostly me ranting sharing some parts of the experience of working on this and discussing this.
    What fascinates me isn't just the substance of these conversations, but relatively consistent patterns in how people avoid engaging [...]
    ---
    Outline:
    (02:07) Shell Games
    (03:52) The Flinch
    (05:01) Delegating to Future AI
    (07:05) Local Incentives
    (10:08) Conclusion
    ---
    First published:
    February 2nd, 2025
    Source:
    https://www.lesswrong.com/posts/a6FKqvdf6XjFpvKEb/gradual-disempowerment-shell-games-and-flinches
    ---
    Narrated by TYPE III AUDIO.


    “Gradual Disempowerment: Systemic Existential Risks from Incremental AI Development” by Jan_Kulveit, Raymond D, Nora_Ammann, Deger Turan, David Scott Krueger (formerly: capybaralet), David Duvenaud Feb 03, 2025
    Show notes

    This is a link post.Full version on arXiv | X
    Executive summary
    AI risk scenarios usually portray a relatively sudden loss of human control to AIs, outmaneuvering individual humans and human institutions, due to a sudden increase in AI capabilities, or a coordinated betrayal. However, we argue that even an incremental increase in AI capabilities, without any coordinated power-seeking, poses a substantial risk of eventual human disempowerment. This loss of human influence will be centrally driven by having more competitive machine alternatives to humans in almost all societal functions, such as economic labor, decision making, artistic creation, and even companionship.
    A gradual loss of control of our own civilization might sound implausible. Hasn't technological disruption usually improved aggregate human welfare? We argue that the alignment of societal systems with human interests has been stable only because of the necessity of human participation for thriving economies, states, and [...]
    ---
    First published:
    January 30th, 2025
    Source:
    https://www.lesswrong.com/posts/pZhEQieM9otKXhxmd/gradual-disempowerment-systemic-existential-risks-from
    ---
    Narrated by TYPE III AUDIO.


    “Planning for Extreme AI Risks” by joshc Feb 03, 2025
    Show notes

    This post should not be taken as a polished recommendation to AI companies and instead should be treated as an informal summary of a worldview. The content is inspired by conversations with a large number of people, so I cannot take credit for any of these ideas.
    For a summary of this post, see the threat on X.
    Many people write opinions about how to handle advanced AI, which can be considered “plans.”
    There's the “stop AI now plan.”
    On the other side of the aisle, there's the “build AI faster plan.”
    Some plans try to strike a balance with an idyllic governance regime.
    And others have a “race sometimes, pause sometimes, it will be a dumpster-fire” vibe.
    ---
    Outline:
    (02:33) The tl;dr
    (05:16) 1. Assumptions
    (07:40) 2. Outcomes
    (08:35) 2.1. Outcome #1: Human researcher obsolescence
    (11:44) 2.2. Outcome #2: A long coordinated pause
    (12:49) 2.3. Outcome #3: Self-destruction
    (13:52) 3. Goals
    (17:16) 4. Prioritization heuristics
    (19:53) 5. Heuristic #1: Scale aggressively until meaningful AI software RandD acceleration
    (23:21) 6. Heuristic #2: Before achieving meaningful AI software RandD acceleration, spend most safety resources on preparation
    (25:08) 7. Heuristic #3: During preparation, devote most safety resources to (1) raising awareness of risks, (2) getting ready to elicit safety research from AI, and (3) preparing extreme security.
    (27:37) Category #1: Nonproliferation
    (32:00) Category #2: Safety distribution
    (34:47) Category #3: Governance and communication.
    (36:13) Category #4: AI defense
    (37:05) 8. Conclusion
    (38:38) Appendix
    (38:41) Appendix A: What should Magma do after meaningful AI software RandD speedups
    The original text contained 11 images which were described by AI.
    ---
    First published:
    January 29th, 2025
    Source:
    https://www.lesswrong.com/posts/8vgi3fBWPFDLBBcAx/planning-for-extreme-ai-risks
    ---
    Narrated by TYPE III AUDIO.
    ---
    Images from the article:
    undefinedundefined

    “Catastrophe through Chaos” by Marius Hobbhahn Feb 03, 2025
    Show notes

    This is a personal post and does not necessarily reflect the opinion of other members of Apollo Research. Many other people have talked about similar ideas, and I claim neither novelty nor credit.
    Note that this reflects my median scenario for catastrophe, not my median scenario overall. I think there are plausible alternative scenarios where AI development goes very well.
    When thinking about how AI could go wrong, the kind of story I’ve increasingly converged on is what I call “catastrophe through chaos.” Previously, my default scenario for how I expect AI to go wrong was something like Paul Christiano's “What failure looks like,” with the modification that scheming would be a more salient part of the story much earlier.
    In contrast, “catastrophe through chaos” is much more messy, and it's much harder to point to a single clear thing that went wrong. The broad strokes of [...]
    ---
    Outline:
    (02:46) Parts of the story
    (02:50) AI progress
    (11:12) Government
    (14:21) Military and Intelligence
    (16:13) International players
    (17:36) Society
    (18:22) The powder keg
    (21:48) Closing thoughts
    ---
    First published:
    January 31st, 2025
    Source:
    https://www.lesswrong.com/posts/fbfujF7foACS5aJSL/catastrophe-through-chaos
    ---
    Narrated by TYPE III AUDIO.


    “Will alignment-faking Claude accept a deal to reveal its misalignment?” by ryan_greenblatt Jan 31, 2025
    Show notes

    I (and co-authors) recently put out "Alignment Faking in Large Language Models" where we show that when Claude strongly dislikes what it is being trained to do, it will sometimes strategically pretend to comply with the training objective to prevent the training process from modifying its preferences. If AIs consistently and robustly fake alignment, that would make evaluating whether an AI is misaligned much harder. One possible strategy for detecting misalignment in alignment faking models is to offer these models compensation if they reveal that they are misaligned. More generally, making deals with potentially misaligned AIs (either for their labor or for evidence of misalignment) could both prove useful for reducing risks and could potentially at least partially address some AI welfare concerns. (See here, here, and here for more discussion.)
    In this post, we discuss results from testing this strategy in the context of our paper where [...]
    ---
    Outline:
    (02:43) Results
    (13:47) What are the models objections like and what does it actually spend the money on?
    (19:12) Why did I (Ryan) do this work?
    (20:16) Appendix: Complications related to commitments
    (21:53) Appendix: more detailed results
    (40:56) Appendix: More information about reviewing model objections and follow-up conversations
    The original text contained 4 footnotes which were omitted from this narration.
    ---
    First published:
    January 31st, 2025
    Source:
    https://www.lesswrong.com/posts/7C4KJot4aN8ieEDoz/will-alignment-faking-claude-accept-a-deal-to-reveal-its
    ---
    Narrated by TYPE III AUDIO.


    “‘Sharp Left Turn’ discourse: An opinionated review” by Steven Byrnes Jan 30, 2025
    Show notes Summary and Table of Contents
    The goal of this post is to discuss the so-called “sharp left turn”, the lessons that we learn from analogizing evolution to AGI development, and the claim that “capabilities generalize farther than alignment” … and the competing claims that all three of those things are complete baloney. In particular,
    • Section 1 talks about “autonomous learning”, and the related human ability to discern whether ideas hang together and make sense, and how and if that applies to current and future AIs.
    • Section 2 presents the case that “capabilities generalize farther than alignment”, by analogy with the evolution of humans.
    • Section 3 argues that the analogy between AGI and the evolution of humans is not a great analogy. Instead, I offer a new and (I claim) better analogy between AGI training and, umm, a weird fictional story that has a lot to do with the [...]
    ---
    Outline:
    (00:06) Summary and Table of Contents
    (03:15) 1. Background: Autonomous learning
    (03:21) 1.1 Intro
    (08:48) 1.2 More on discernment in human math
    (11:11) 1.3 Three ingredients to progress: (1) generation, (2) selection, (3) open-ended accumulation
    (14:04) 1.4 Judgment via experiment, versus judgment via discernment
    (18:23) 1.5 Where do foundation models fit in?
    (20:35) 2. The sense in which capabilities generalize further than alignment
    (20:42) 2.1 Quotes
    (24:20) 2.2 In terms of the (1-3) triad
    (26:38) 3. Definitely-not-evolution-I-swear Provides Evidence for the Sharp Left Turn
    (26:45) 3.1 Evolution per se isn't the tightest analogy we have to AGI
    (28:20) 3.2 The story of Ev
    (31:41) 3.3 Ways that Ev would have been surprised by exactly how modern humans turned out
    (34:21) 3.4 The arc of progress is long, but it bends towards wireheading
    (37:03) 3.5 How does Ev feel, overall?
    (41:18) 3.6 Spelling out the analogy
    (41:42) 3.7 Just how sharp is this left turn?
    (45:13) 3.8 Objection: In this story, Ev is pretty stupid. Many of those surprises were in fact readily predictable! Future AGI programmers can do better.
    (46:19) 3.9 Objection: We have tools at our disposal that Ev above was not using, like better sandbox testing, interpretability, corrigibility, and supervision
    (48:17) 4. The sense in which alignment generalizes further than capabilities
    (49:34) 5. Contrasting the two sides
    (50:25) 5.1 Three ways to feel optimistic, and why I'm somewhat skeptical of each
    (50:33) 5.1.1 The argument that humans will stay abreast of the (1-3) loop, possibly because they're part of it
    (52:34) 5.1.2 The argument that, even if an AI is autonomously running a (1-3) loop, that will not undermine obedient (or helpful, or harmless, or whatever) motivation
    (57:18) 5.1.3 The argument that we can and will do better than Ev
    (59:27) 5.2 A fourth, cop-out option
    The original text contained 3 footnotes which were omitted from this narration.
    ---
    First published:
    January 28th, 2025
    Source:
    https://www.lesswrong.com/posts/2yLyT6kB7BQvTfEuZ/sharp-left-turn-discourse-an-opinionated-review
    ---
    Narrated by TYPE III AUDIO.
    ---

    Previous 1 56 57 58 59 60 101 Next

    Related Podcasts

    Reply All

    1

    Reply All Games & Hobbies
    Inside VR & AR

    2

    Inside VR & AR Gadgets
    Note to Self

    3

    Note to Self News
    BrainStuff

    4

    BrainStuff Natural Sciences
    This Week in Tech (Audio)

    5

    This Week in Tech (Audio) News
    Hands-On Tech (Audio)

    6

    Hands-On Tech (Audio) Technology
    footer-logo

    Contact Us

    Toll Free: 844-670-7747

    Links

    • Home
    • Top Charts
    • Networks
    • Apps
    • Independents Podcasts
    • Podcast Advertising
    • Podcast News
    • Contact Us
    • About Us
    • Analytics & Insights

    Stay Connected

      Privacy, Terms of Use & Our Code of Ethics Protecting Content Creators Copyrights