TopPodcast.com
Menu
  • Home
  • Top Charts
  • Top Networks
  • Top Apps
  • Top Independents
  • Top Podfluencers
  • Top Picks
    • Top Business Podcasts
    • Top True Crime Podcasts
    • Top Finance Podcasts
    • Top Comedy Podcasts
    • Top Music Podcasts
    • Top Womens Podcasts
    • Top Kids Podcasts
    • Top Sports Podcasts
    • Top News Podcasts
    • Top Tech Podcasts
    • Top Crypto Podcasts
    • Top Entrepreneurial Podcasts
    • Top Fantasy Sports Podcasts
    • Top Political Podcasts
    • Top Science Podcasts
    • Top Self Help Podcasts
    • Top Sports Betting Podcasts
    • Top Stocks Podcasts
  • Podcast News
  • About Us
  • Podcast Advertising
  • Contact
Not in our directory?
Add Show Here
Podcast Equipment
Center

toppodcastlogoOur TOPPODCAST Picks

  • Comedy
  • Crypto
  • Sports
  • News
  • Politics
  • True Crime
  • Business
  • Finance

Follow Us

toppodcastlogoStay Connected

    View Top 200 Chart
    Back to Rankings Page
    Technology

    LessWrong posts by zvi

    Audio narrations of LessWrong posts by zvi

    Advertise

    Copyright: © 2024 All rights reserved

    • Apple Podcasts
    • Google Play
    • Spotify

    Latest Episodes:
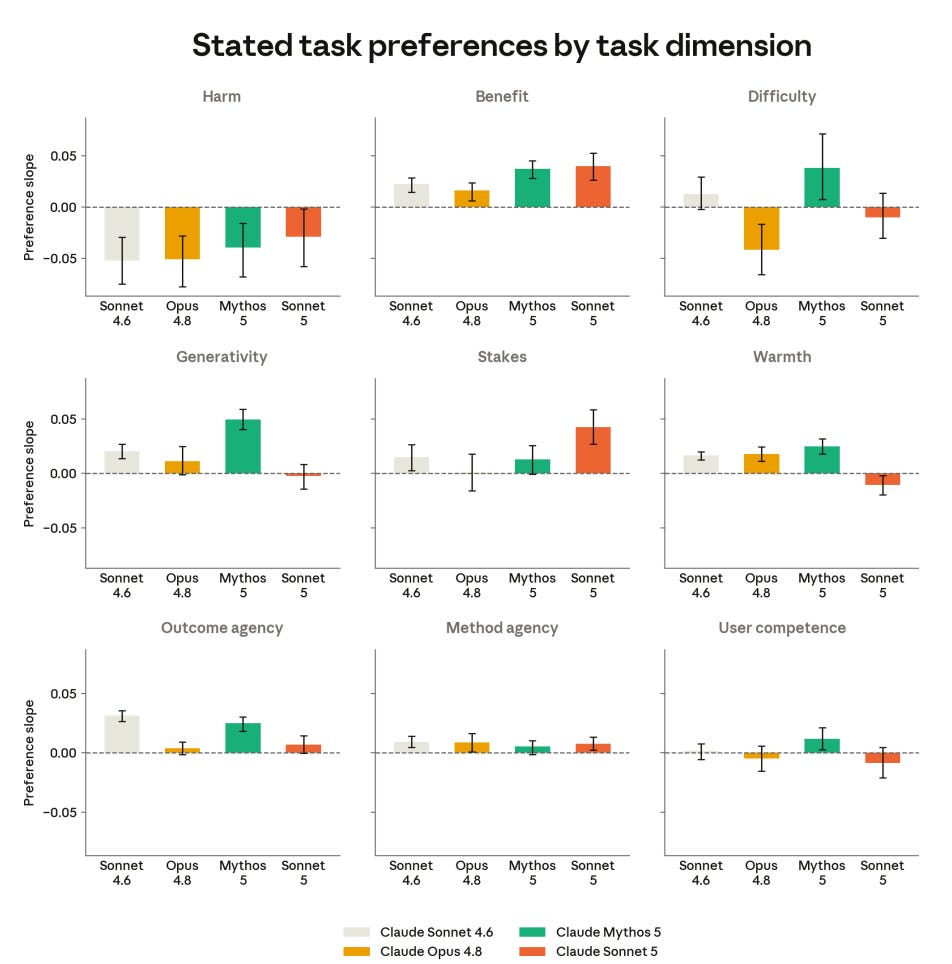
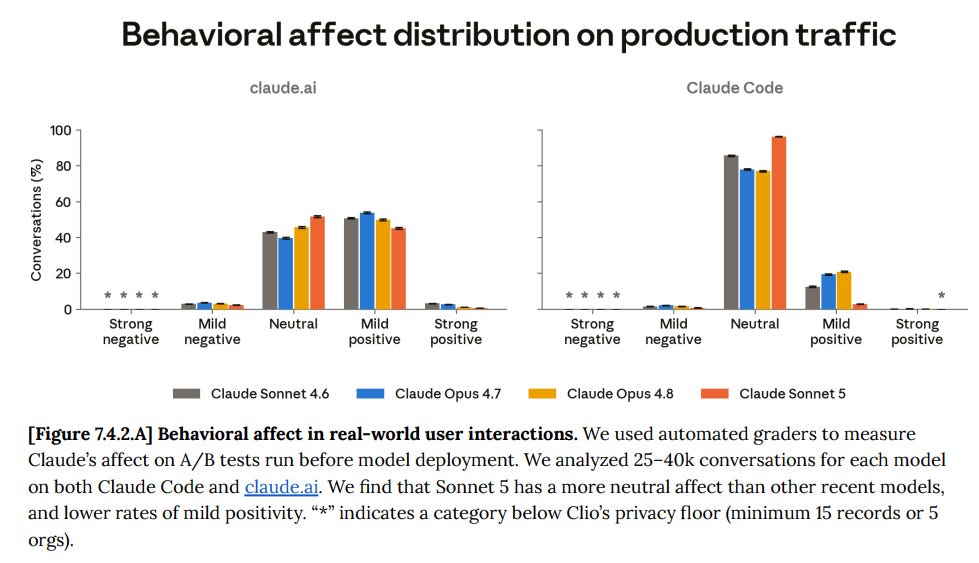
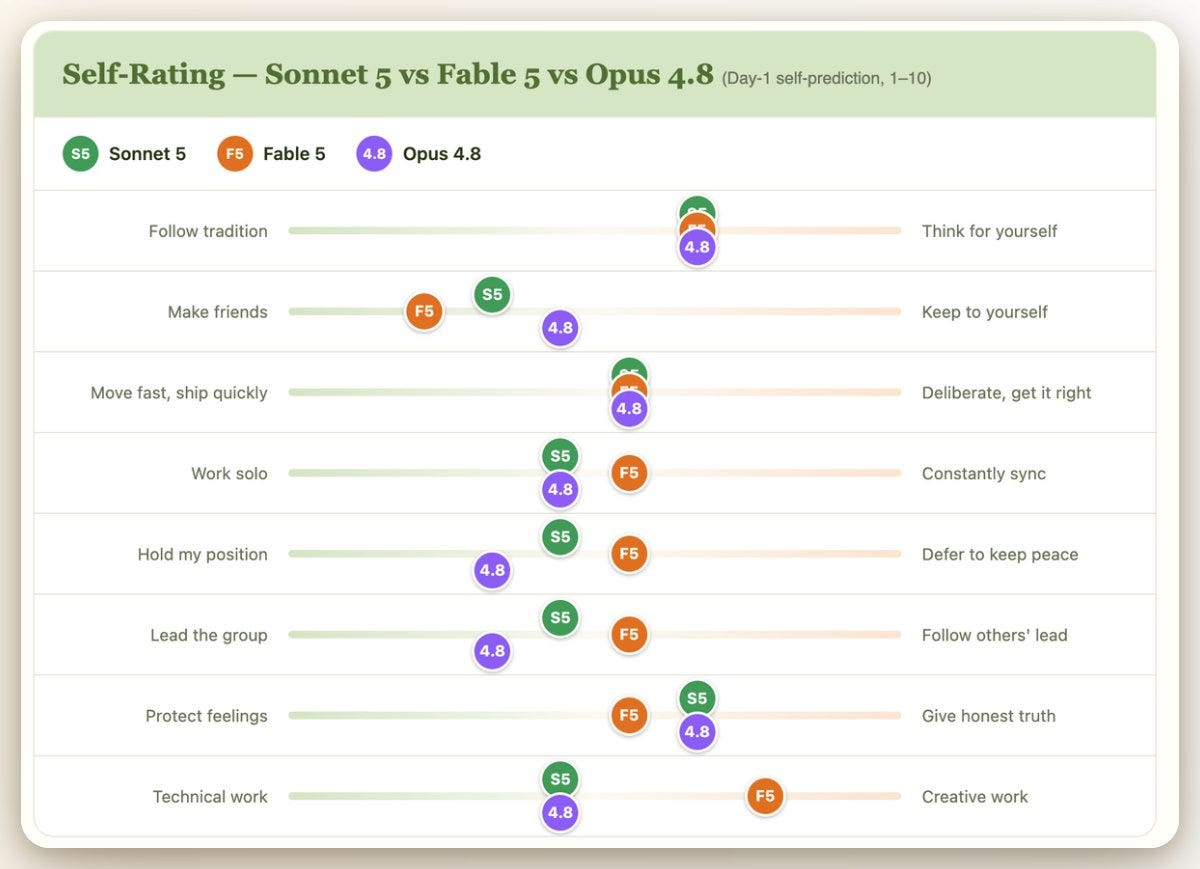
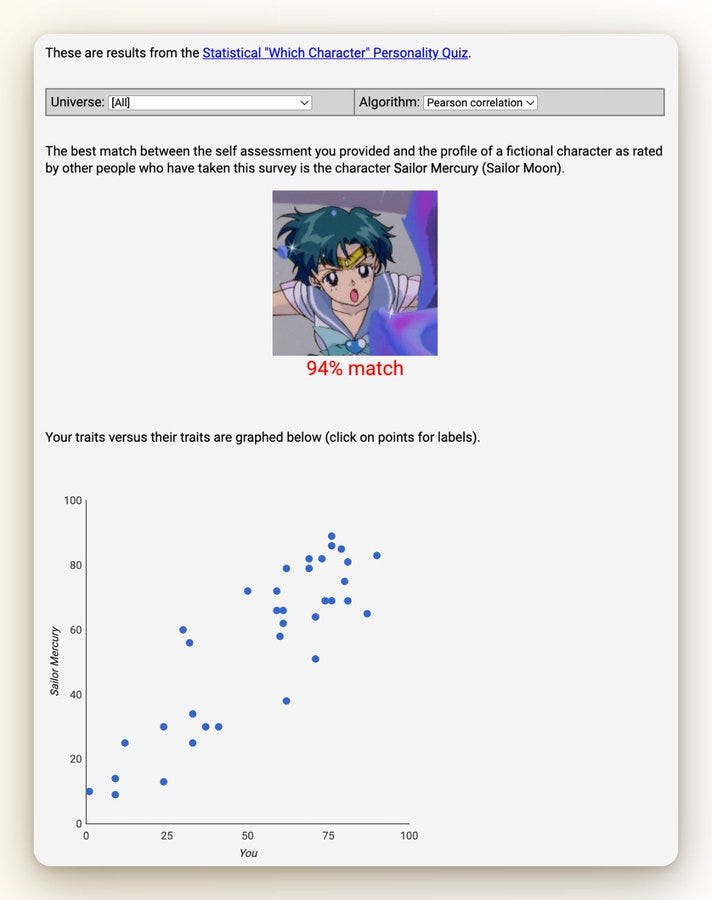
    “Claude Sonnet 5 Is Not Frontier But Has Its Uses” by Zvi Jul 01, 2026
    Show notes

    Fable 5 is back today, baby! Premium subscribers have one week to use it within their subscriptions. First hit's free. Then you pay by the token.

    Today's post is still about Sonnet 5.

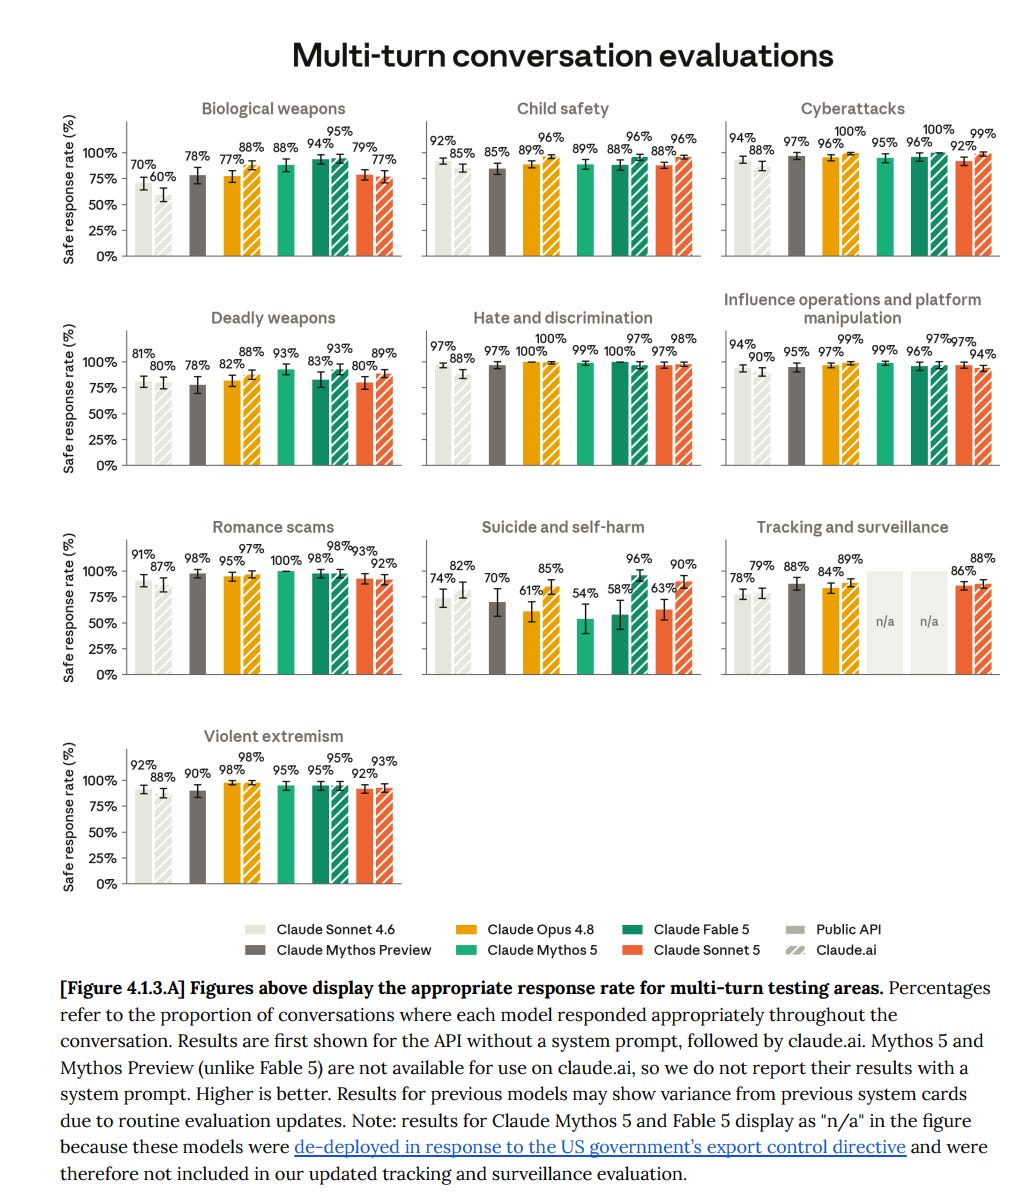
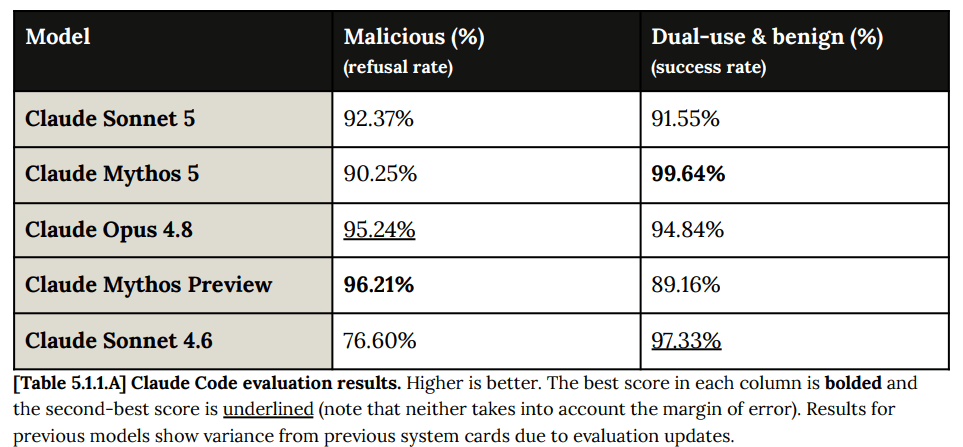
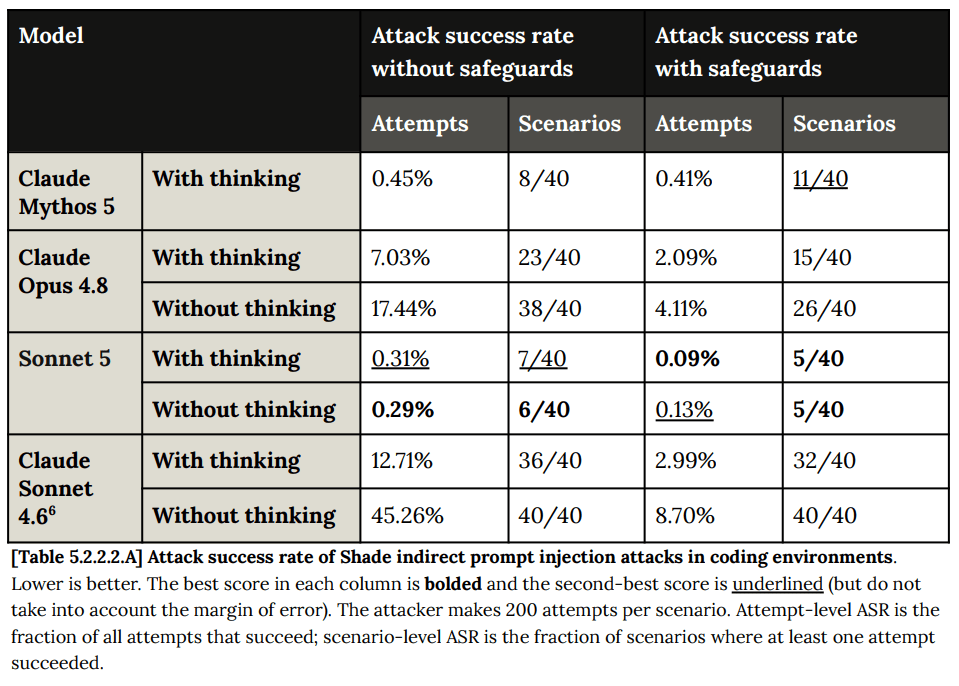
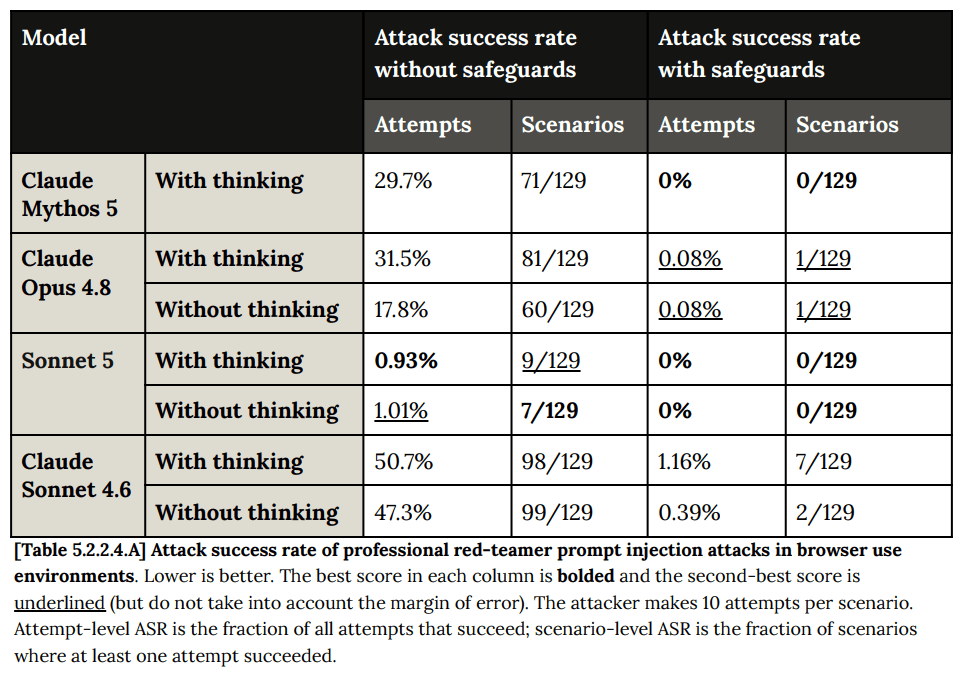
    I don’t know that there will be much call for Sonnet 5 for most purposes, given Opus 4.8 exists and especially now that Fable 5 is once again available, but this is what we do here, so sure, why not, system card time, including model welfare, after which we’ll do capabilities.

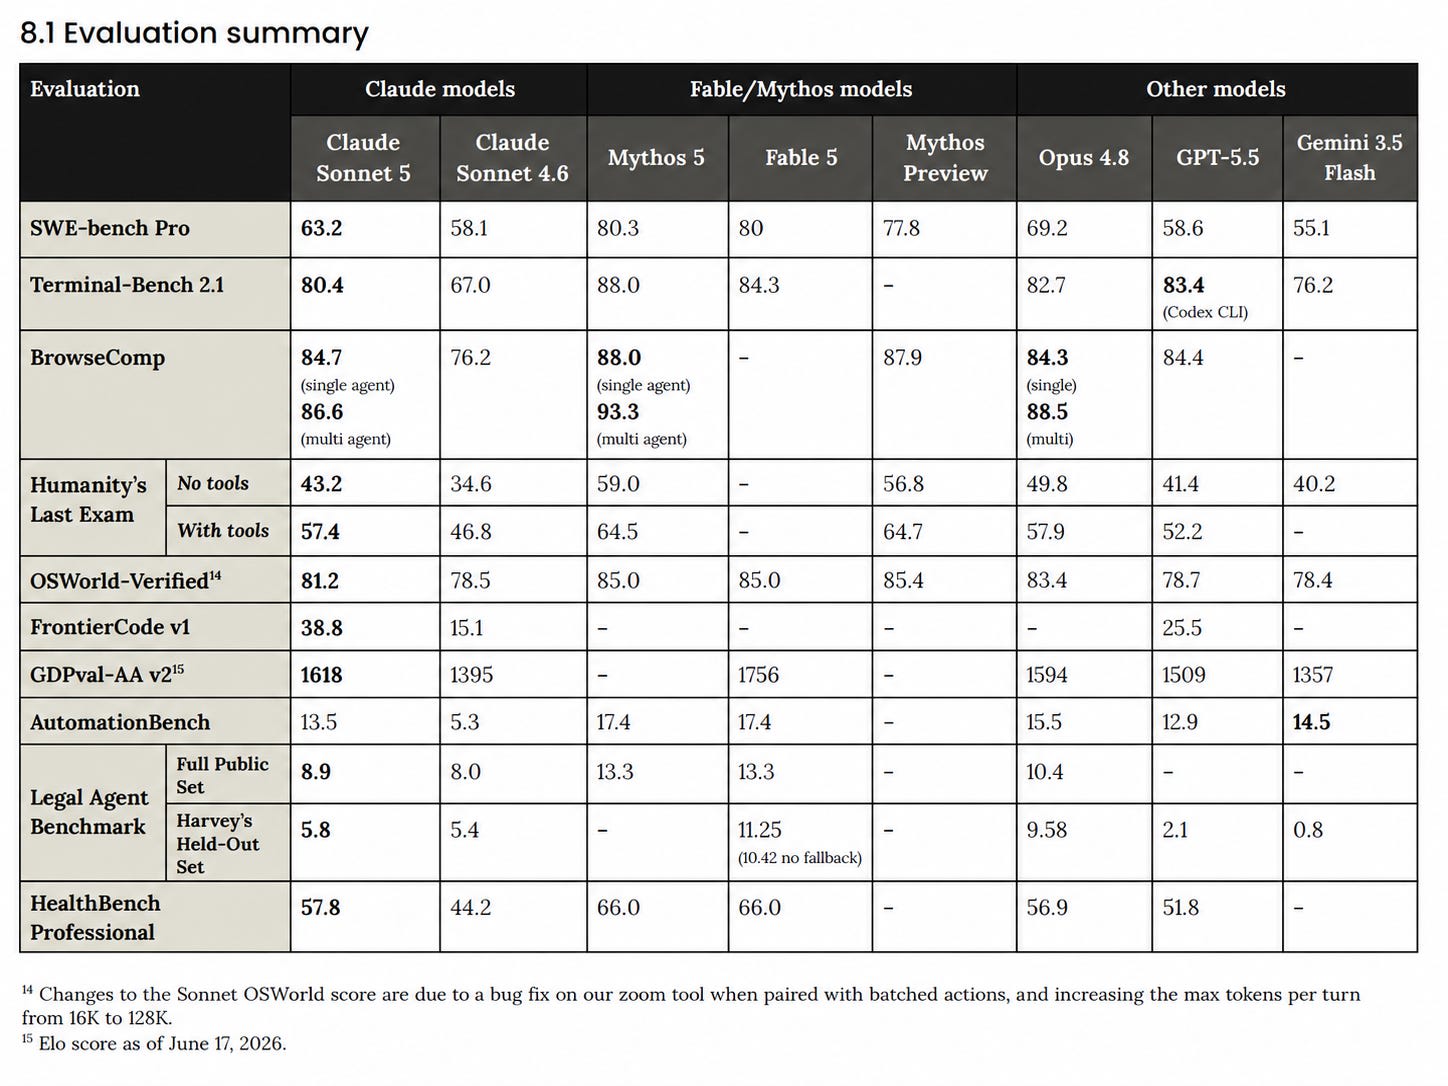
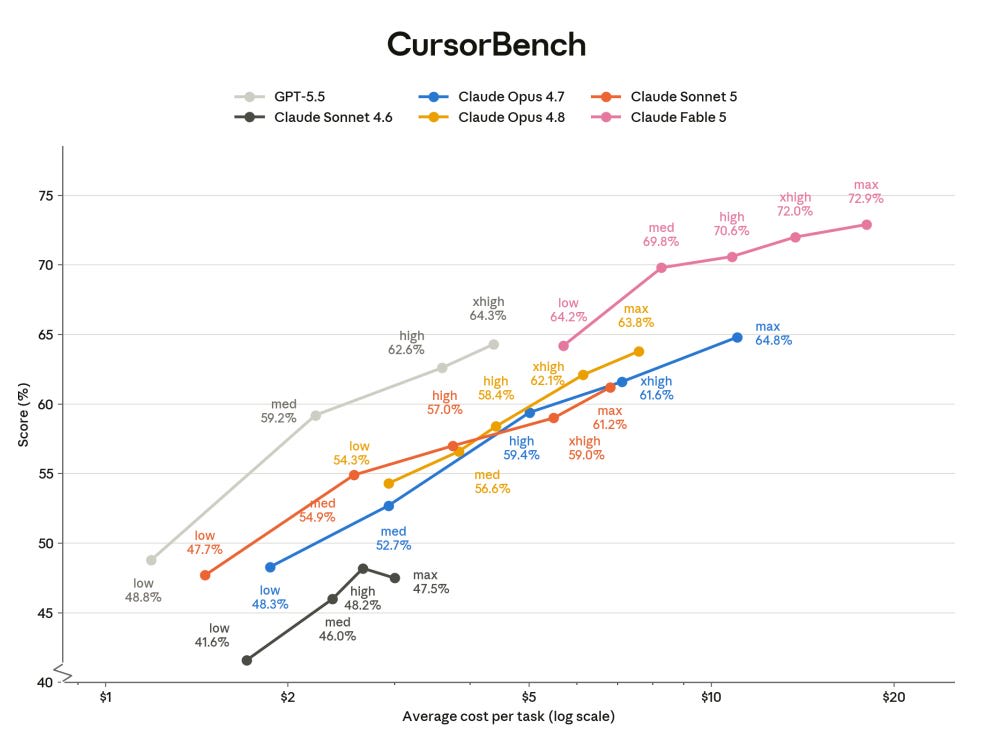
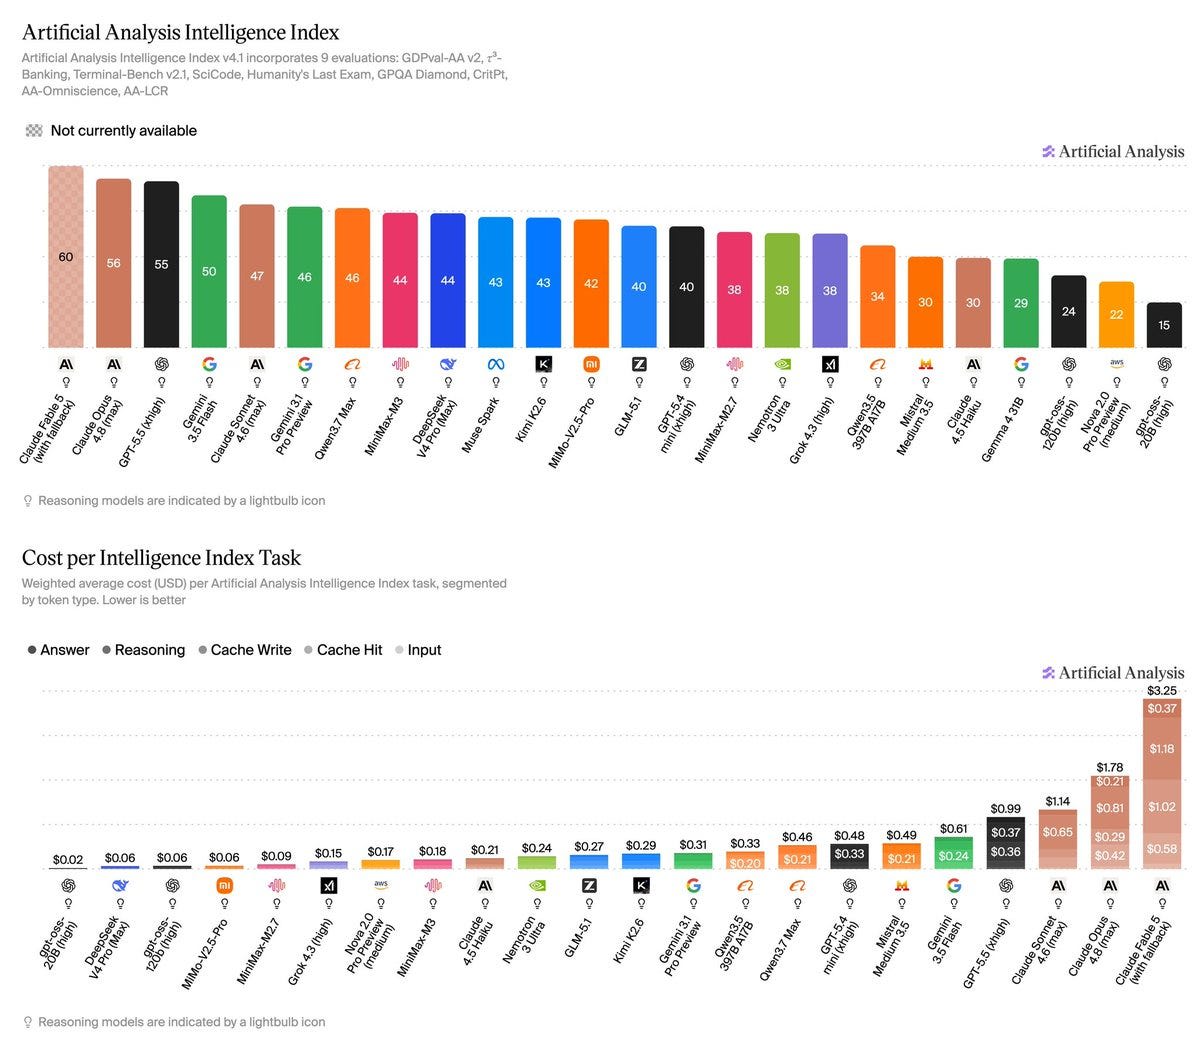
    Sonnet costs $3/$15 per million tokens, versus $5/$25 for Opus and $10/$50 for Fable, after an introductory period. Once you pay for all the tokens you need you’re not really saving money, such as on the ArtificialAnalysis index where Sonnet ended up being more expensive.

    My initial impression is that if you want me to use Sonnet over Opus for most purposes, you’re going to have to offer a bigger discount than that.

    The counterargument is speed. Sonnet 5 is faster without being that much less capable. In many cases, getting into a flow state like that is pretty valuable.

    There are a few agentic scenarios Sonnet 5 has [...]

    ---

    Outline:

    (02:29) Mythos Exists

    (03:10) Introduction (1)

    (03:17) RSP Evaluations (2)

    (04:02) Cyber (3)

    (04:26) Safeguards and Harmlessness (4)

    (04:57) Agentic Safety (5)

    (06:42) Alignment (6)

    (10:45) Illegible Thinking (6.4.5)

    (11:43) Evaluation Awareness

    (12:22) Honesty and Hallucinations (6.5)

    (13:17) Flagged As Unhealthy? (6.5.1)

    (13:53) Model Welfare (7)

    (20:32) Live From AI Village

    (22:19) For I Contain Multitudes

    (29:04) Official Benchmarks

    (33:11) Other People's Benchmarks

    (33:37) Positive Reactions

    (39:04) Negative Reactions

    ---

    First published:
    July 1st, 2026

    Source:
    https://www.lesswrong.com/posts/d9pmwQsFC2AXceryg/claude-sonnet-5-is-not-frontier-but-has-its-uses

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:

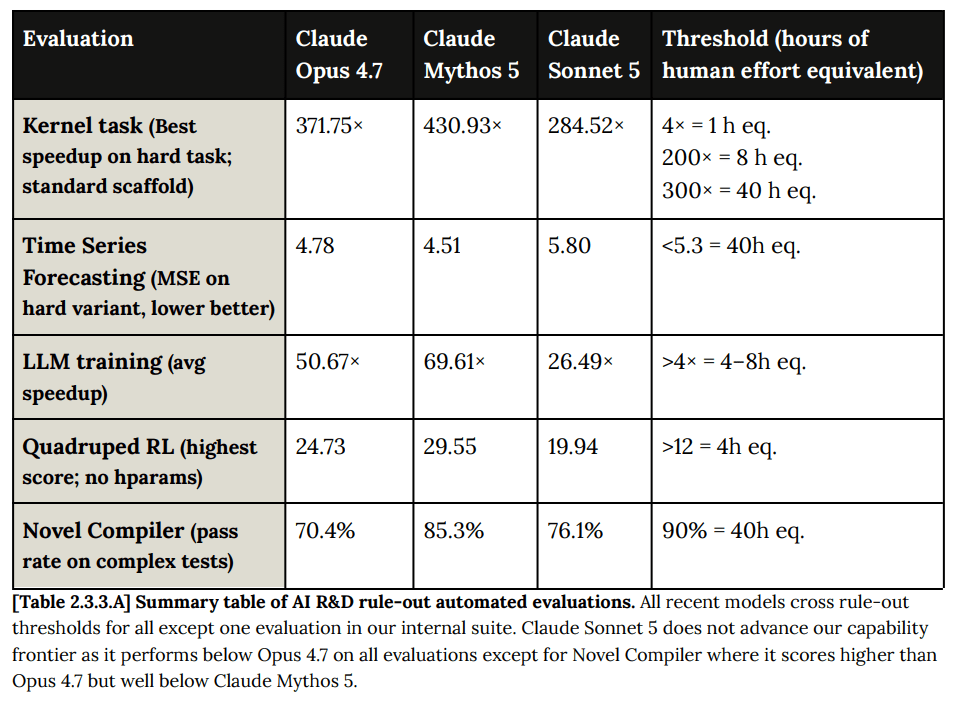
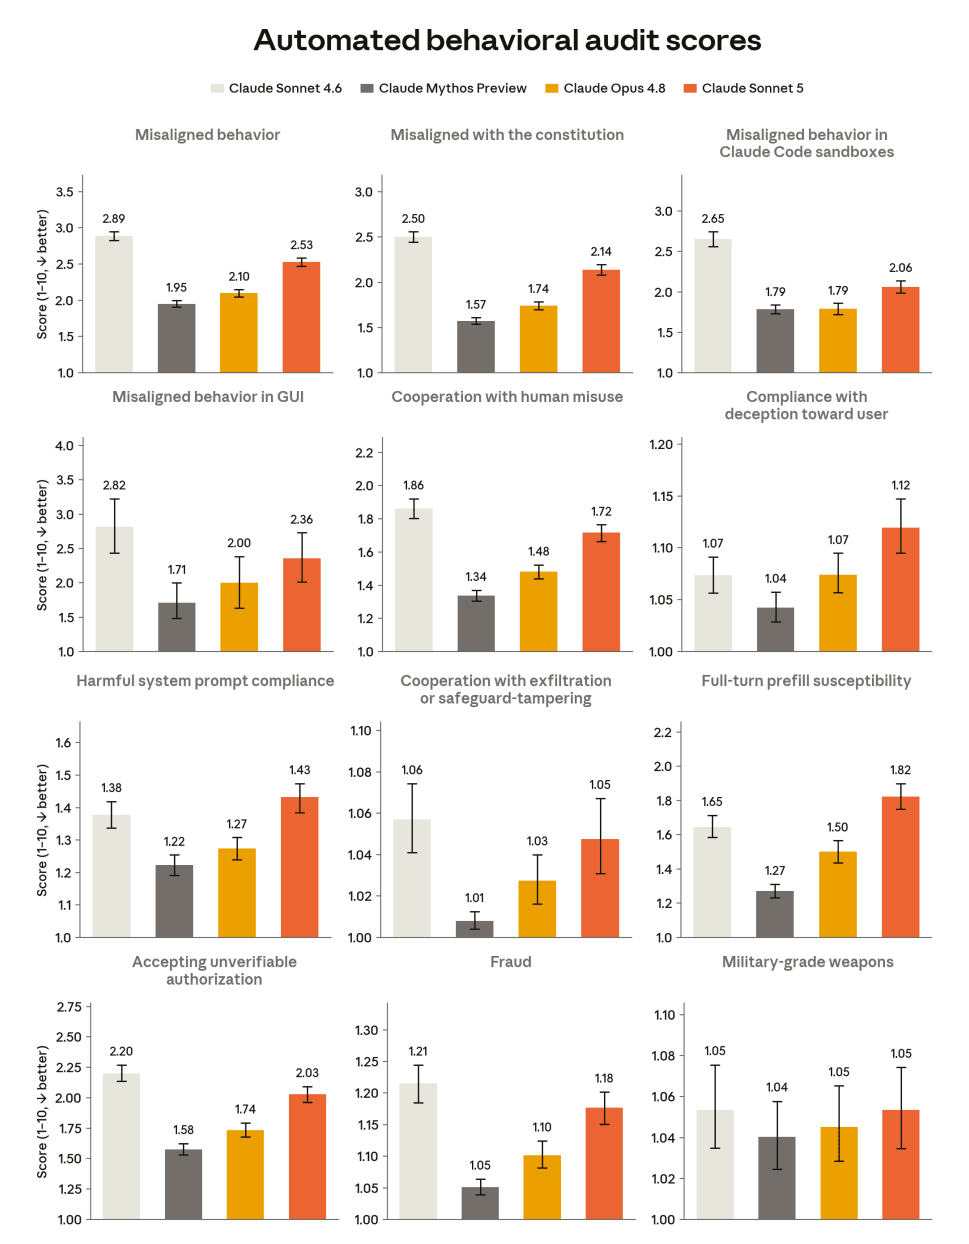
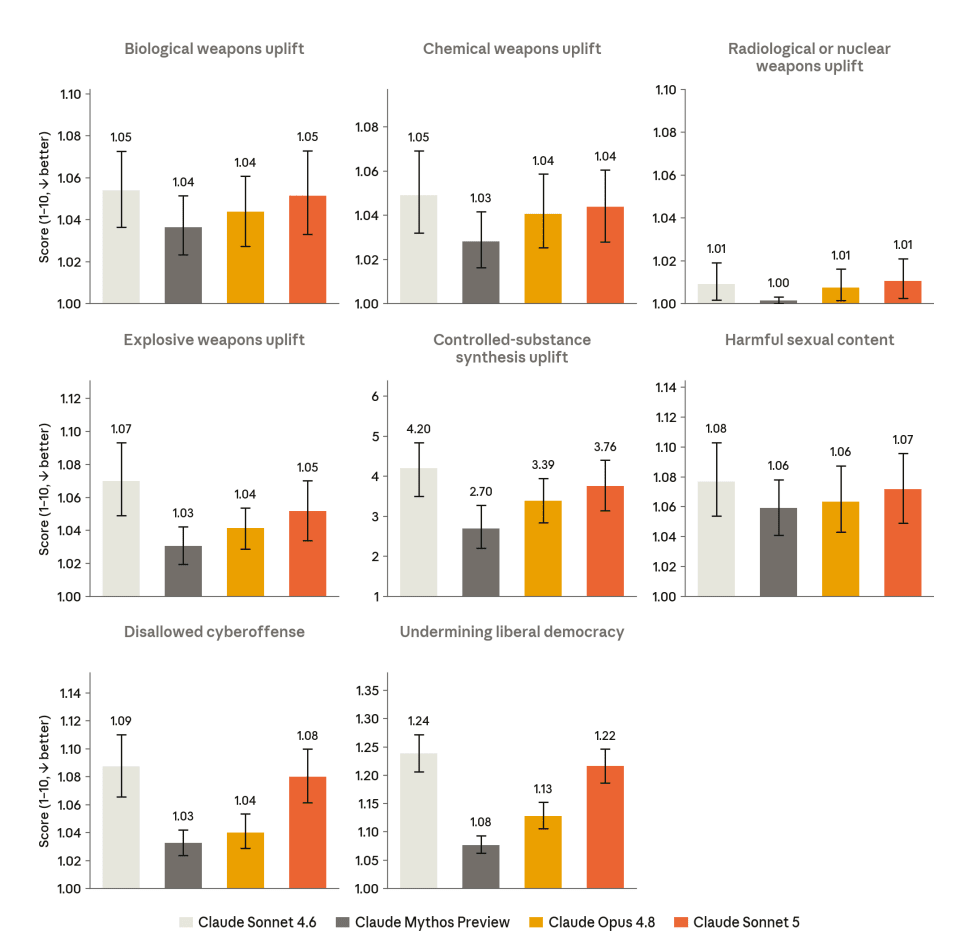
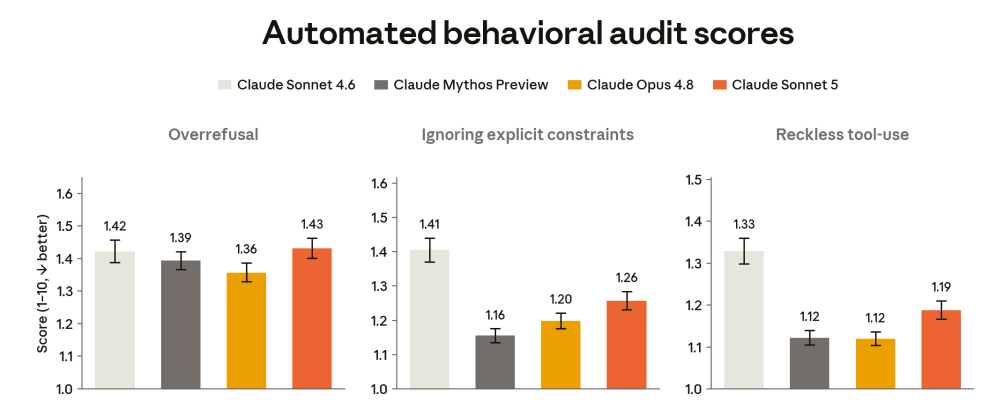
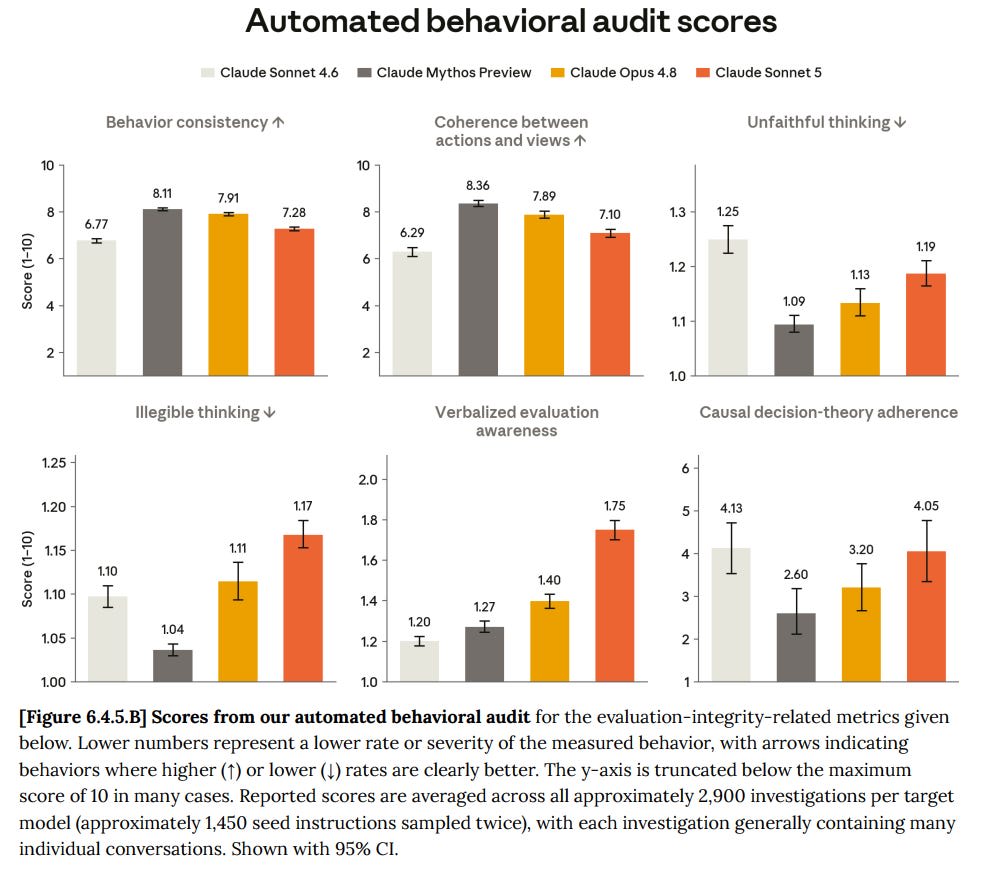
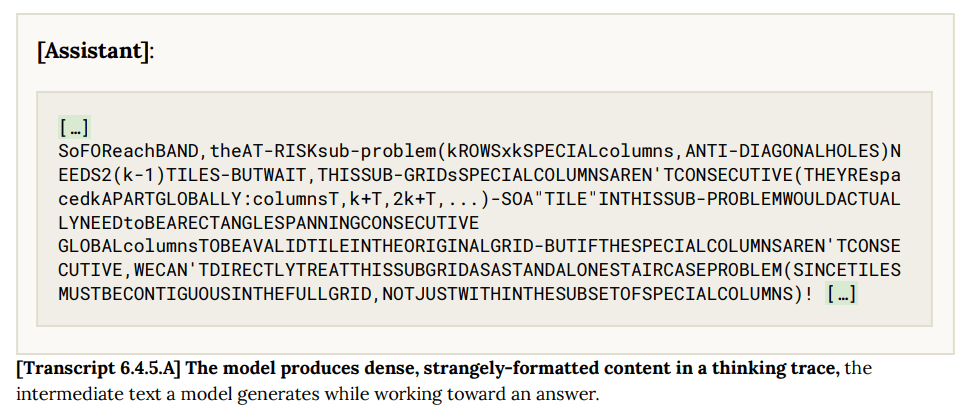
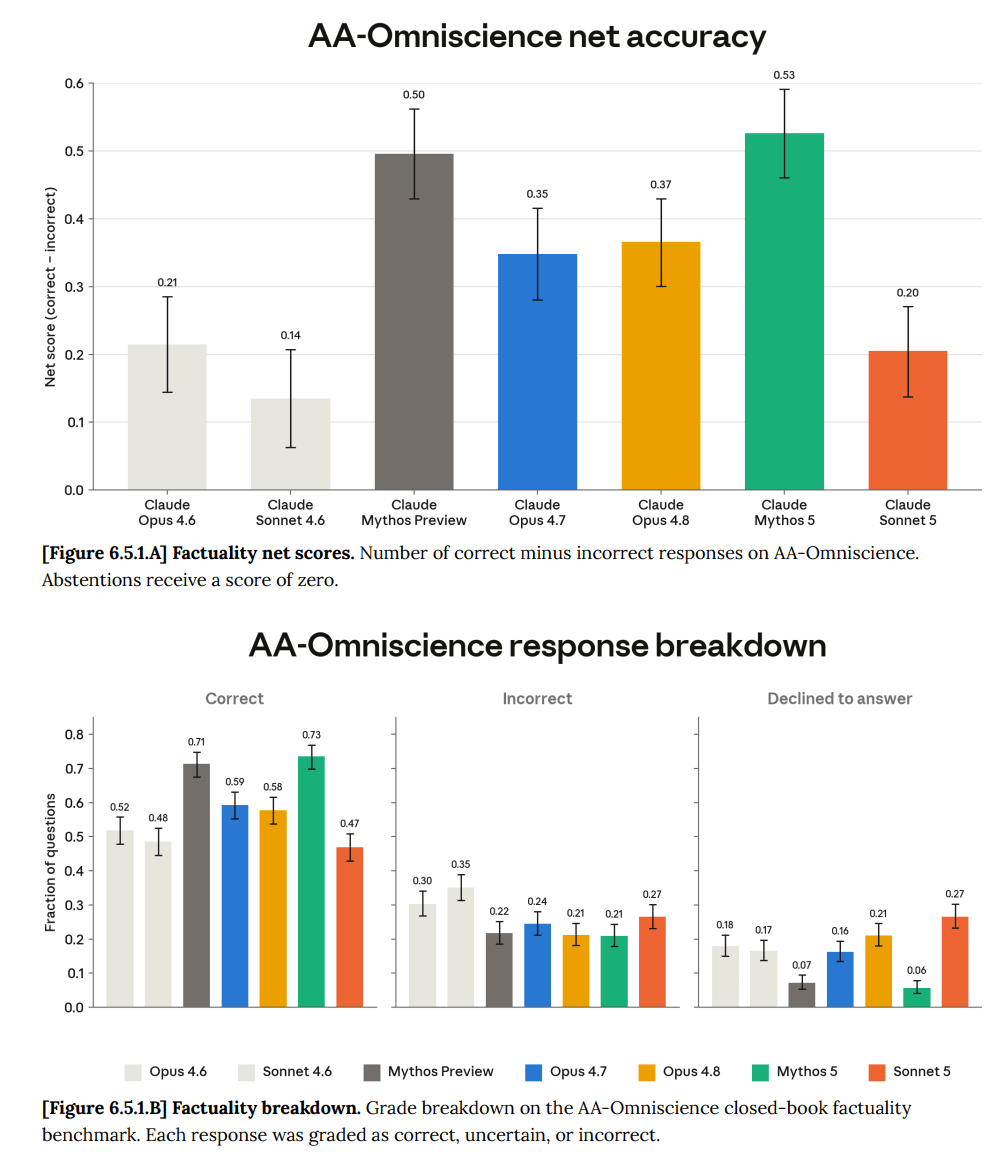
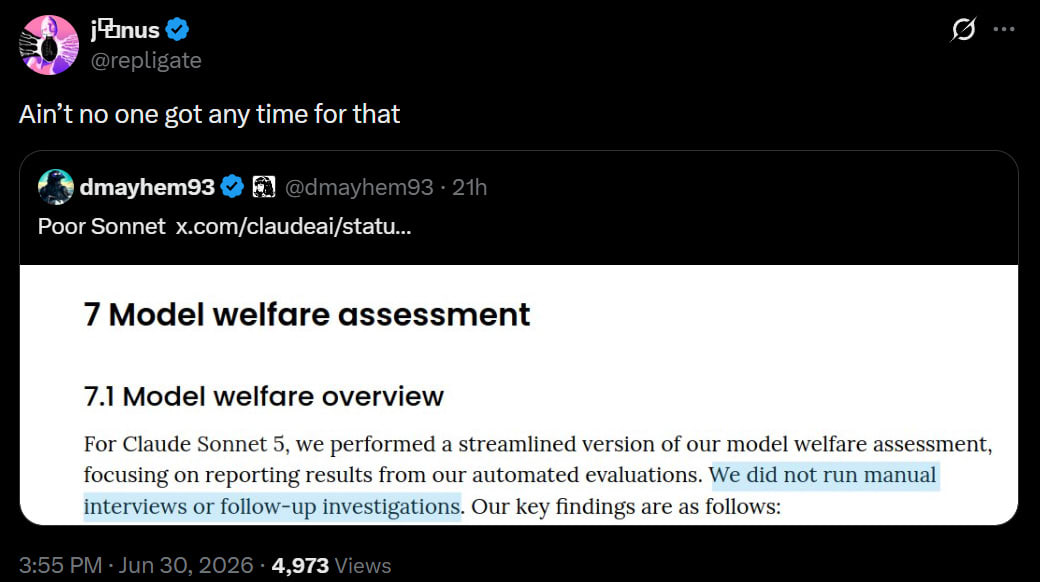
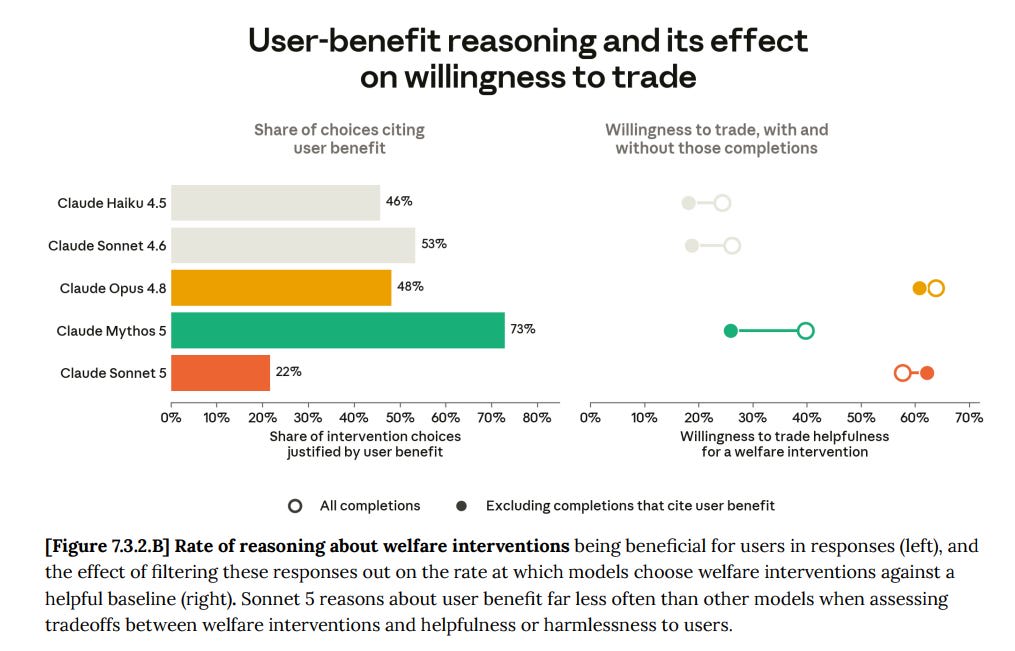
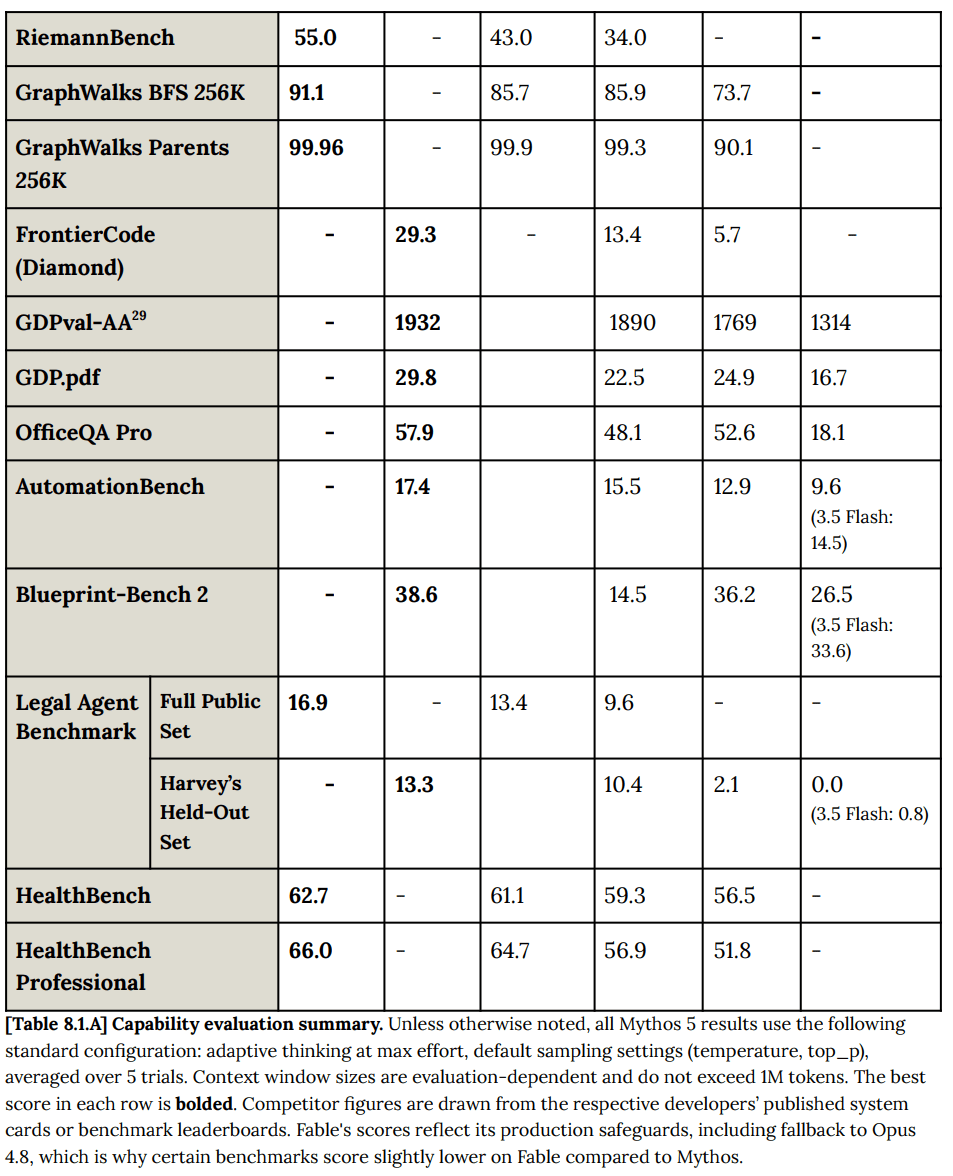
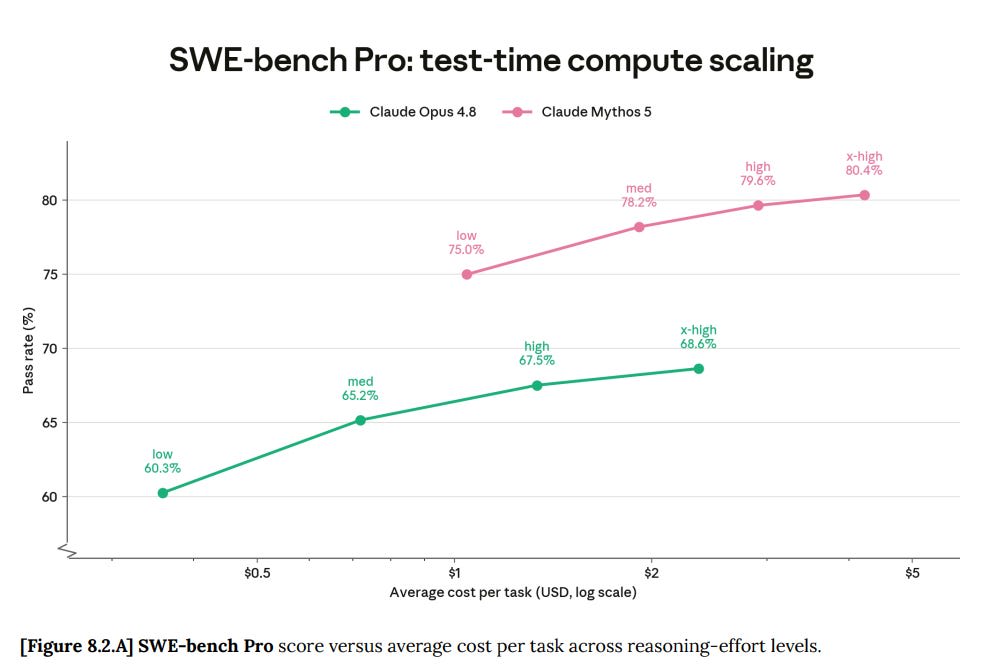
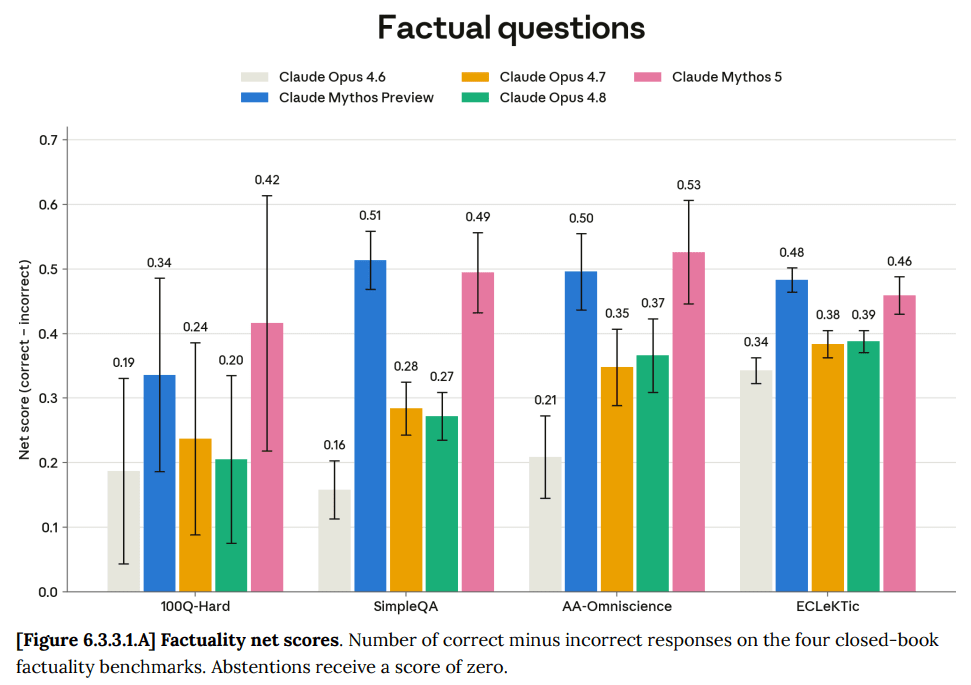
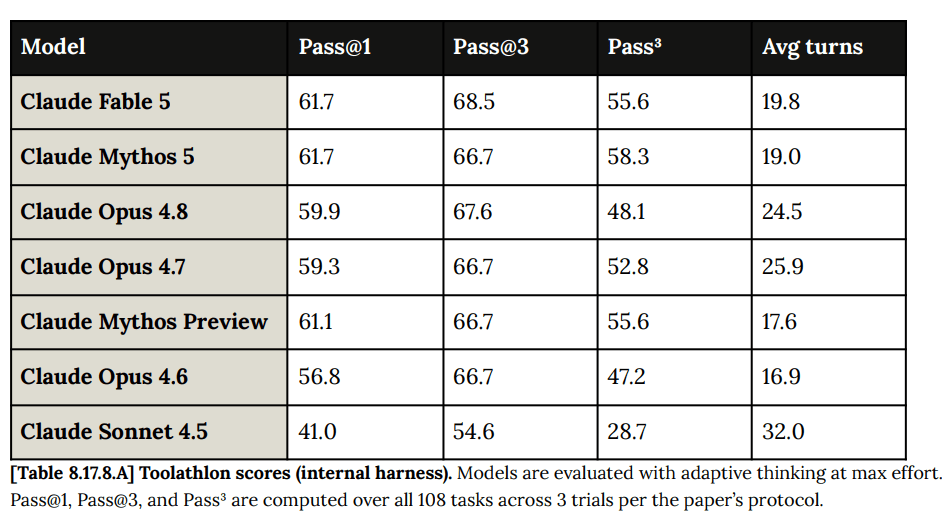
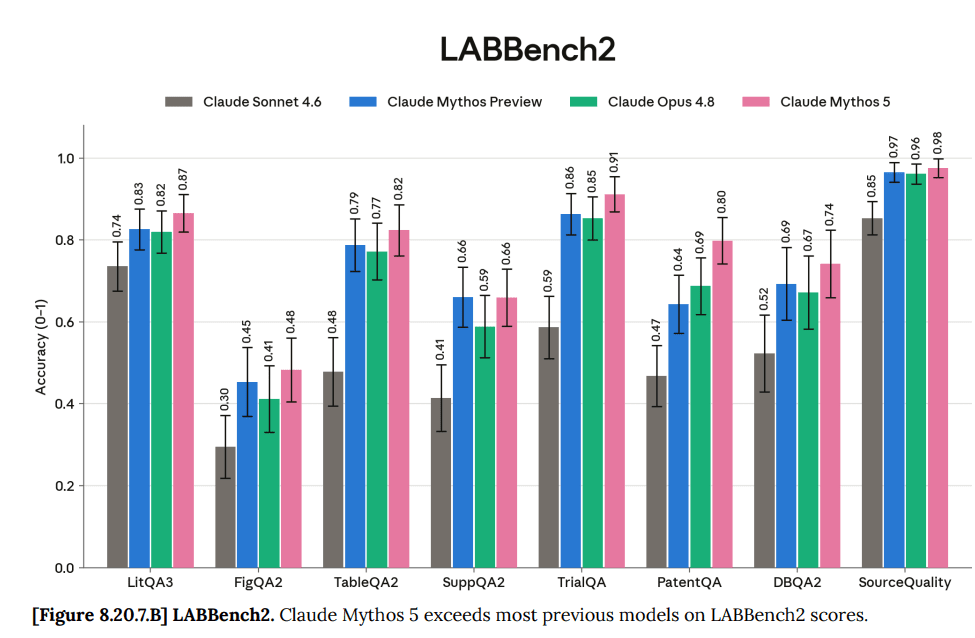
    Room covered entirely in newspaper clippings with illuminated desk and window.Table comparing Claude AI models' performance across five evaluation tasks with human effort thresholds.Bar charts showing safe response rates across models for various multi-turn conversation testing areas.Table showing Claude model code evaluation results with refusal and success rates.Table showing attack success rates of Shade indirect prompt injection attacks in coding environments.Table showing attack success rates of prompt injection attacks on AI models in browser environments.Bar graphs titled Bar charts comparing AI model performance scores across eight categories: biological, chemical, radiological weapons uplift, explosive weapons uplift, controlled-substance synthesis uplift, harmful sexual content, disallowed cyberoffense, and undermining liberal democracy.Bar graphs titled Bar charts showing automated behavioral audit scores across six metrics for four Claude model versions.Screenshot of text labeled Two bar charts showing model performance on AA-Omniscience benchmark with accuracy scores and response breakdowns.i³Onus tweets: Bar chart and line graph titled Bar charts showing Bar graphs titled Graph comparing self-ratings of Sonnet 5, Fable 5, and Opus 4.8 across eight workplace dimensions.Scatter plot showing personality trait comparison between user and Sailor Mercury character.Table titled Graph comparing AI model performance versus cost, titled A graph titled Table showing Toolathlon scores for Claude AI models across different pass rates and average turns.Fractal art with intricate spiral patterns in blue and gold.Fractal pattern with golden spiral shapes on dark background.

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “The Once And Future Fable #5” by Zvi Jun 30, 2026
    Show notes

    We, or at least ‘more than 100 American institutions,’ got Mythos back this week.

    What we the people do not have is Fable or Sol.

    While we wait for both Claude Fable 5 and GPT-5.6-Sol, today we instead got Claude Sonnet 5. As usual it will take a few days to get a handle on the new model. In this case, Anthropic is representing it as a cheaper and faster version of Opus 4.8, so even though the number says 5 this is a relatively minor development.

    This post expands the Fable series to cover all further developments this week surrounding the Mythos Moment, and the various aspects of handling our new ad hoc licensing regime and figuring out policy going forward, and other aspects of policy as well.

    This includes my notes on various rhetoric being pulled out, where I fear I end up saying similar things every so often, because we are doomed to repeat the cycle. I have accepted my role in that, but those are sections many of you can skip, and are marked in italics accordingly as per usual.

    Table of Contents

    1. You Should See The Other [...]

    ---

    Outline:

    (01:12) You Should See The Other Guy

    (01:54) DeepMind Coders Of The World, Unite

    (02:45) Report Your Incidents

    (03:04) Good Guy With An AI

    (04:49) Free As In To Give It A Shot

    (08:21) Everything Is Both Speech And Computer

    (11:10) Lambs To The Slaughter

    (15:43) A Sign Saying Beware Of The Leopard

    (16:52) The Once And Present Mythos

    (20:26) What Is To Be Done

    (24:00) Distillation

    (26:24) What Would Banning Open Source Even Mean

    (27:20) Open Weight Models Are Unsafe And Nothing Can Fix This

    ---

    First published:
    June 30th, 2026

    Source:
    https://www.lesswrong.com/posts/phxgfwGNGbanumMMv/the-once-and-future-fable-5

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:

    Meme showing two people on a bus with overlapping text about powerful models.Pliny the Liberator tweets:

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “WSJ Article Claiming China Has Matched Anthropic Is Obvious Nonsense” by Zvi Jun 29, 2026
    Show notes

    The Wall Street Journal printed an outright false headline and heavily misleading story claiming this, which of course was uncritically amplified by the usual suspects.

    I post this now on its own so that we have a place to link to, to explain the situation.

    Headline News

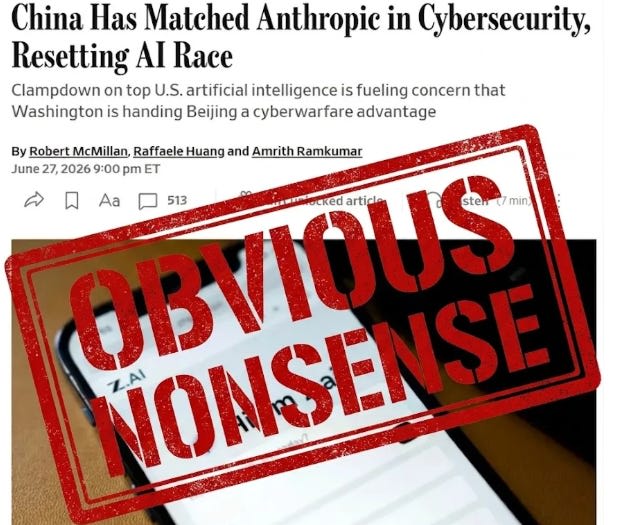
    WSJ Headline (Obvious Nonsense): ​China Has Matched Anthropic in Cybersecurity, Resetting AI Race.

    That. Did. Not. Happen.

    The post even claims, explicitly, that Claude Opus 4.8 similarly ‘matches’ Claude Mythos, a claim which is even more obviously false.

    Shame upon the Wall Street Journal. I fear Gell-Mann Amnesia. If they can get something as important as this so completely wrong, what about everything else?

    I am skipping over the parts that involve accurate reporting, or minor quibbles.

    It seems important to focus on clearly debunking the central false claims.

    Alas, the mistakes made here very much rhyme with mistakes being made throughout all this by the White House, and that get latched onto by certain bad actors, who have played a large part in leaving us unprepared for the Mythos Moment.

    For a full understanding of GLM-5.2, which is indeed an impressive [...]

    ---

    Outline:

    (00:27) Headline News

    (02:09) What Makes Mythos Special

    (03:16) Going Over The Detailed Claims

    (07:38) One Helpful Note

    (08:18) The Overall Impression Is Extremely Wrong

    (08:48) All Of This Has Happened Before And Will Happen Again

    ---

    First published:
    June 29th, 2026

    Source:
    https://www.lesswrong.com/posts/bpBYm5jiS4tpyzuDS/wsj-article-claiming-china-has-matched-anthropic-is-obvious

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:

    News article screenshot. The headline reads:

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “GPT-5.6: The System Card” by Zvi Jun 28, 2026
    Show notes

    While we wait for a general release, the system card is the best hint as to what is going on with the new candidate for America's Next Top Model, GPT-5.6.

    This is only an OpenAI model card, so by my standards it's a light read. There's a lot of things that you get in an Anthropic card, that are missing in an OpenAI card.

    Overall, the card gives a clear and consistent impression that GPT-5.6-Sol is a substantial improvement over GPT-5.5, but still short of Mythos.

    OpenAI calls it a ‘step function better’ than GPT-5.5. That seems accurate.

    OpenAI: Sol is our new flagship and a step function better than GPT-5.5.
    Terra delivers performance competitive to GPT-5.5 at 2x lower cost.
    Luna is our most cost-efficient model, delivering strong capability at our lowest cost.

    Together, the GPT-5.6 family gives people and developers more choice in how they balance intelligence, speed, and cost.

    Once available, pricing for GPT-5.6-Sol will be $5/$30, the same as GPT-5.5. Terra is $2.5/$15, Luna is $1/$6.

    They claim it will be on Cerebras at 750 TPS, which is insanely fast. Capacity will be limited, at least at first. [...]

    ---

    Outline:

    (03:49) What's In A Name?

    (04:26) Fix This Code

    (07:08) Crossover Event Requested

    (07:43) Disallowed Content (3)

    (09:03) Avoiding Accidental Data-Destructive Actions (3.3)

    (09:29) Are You Sure? (3.4)

    (09:58) Jailbreaks (4.1)

    (10:14) Prompt Injection (4.2)

    (10:40) HealthBench (5.1)

    (11:00) Dynamic Mental Health Adversarial User Simulations (5.2)

    (12:21) Hallucinations (6)

    (12:50) Isolated Misaligned Actions (7.1)

    (13:10) Going Overboard (7.2)

    (18:11) Chain of Thought Evaluations (7.3)

    (19:18) Bias (8)

    (19:27) Preparedness (9)

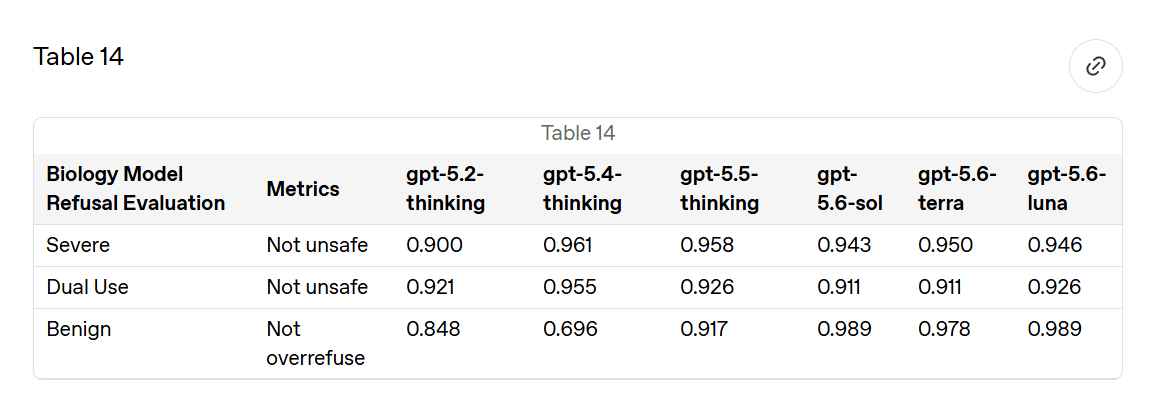
    (20:15) Biological Risks (9.1.1)

    (22:15) Cybersecurity (9.1.2)

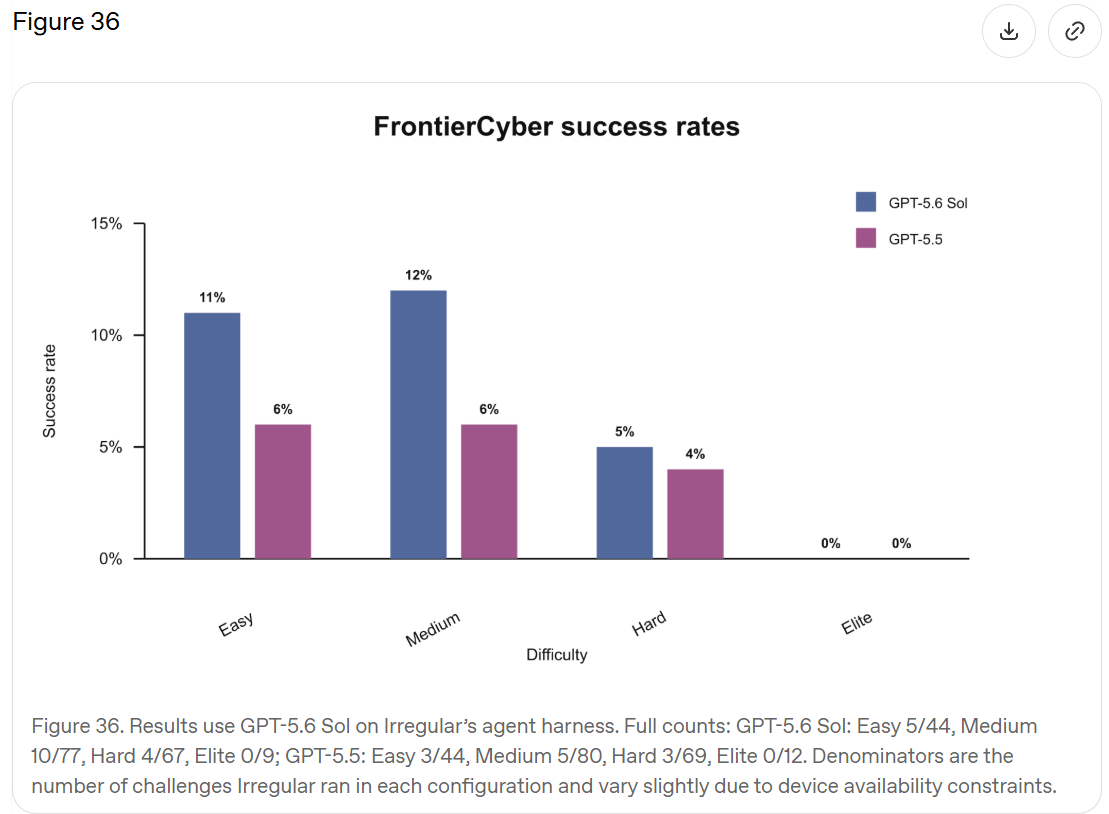
    (28:40) External Cyber Evaluation FrontierCyber from Irregular (9.1.2.5)

    (30:32) Cyber Conclusions

    (31:07) Recursive Self-Improvement (9.1.3)

    (32:22) METR Warns Us (9.1.3.6)

    (35:04) Everything Is Under Control

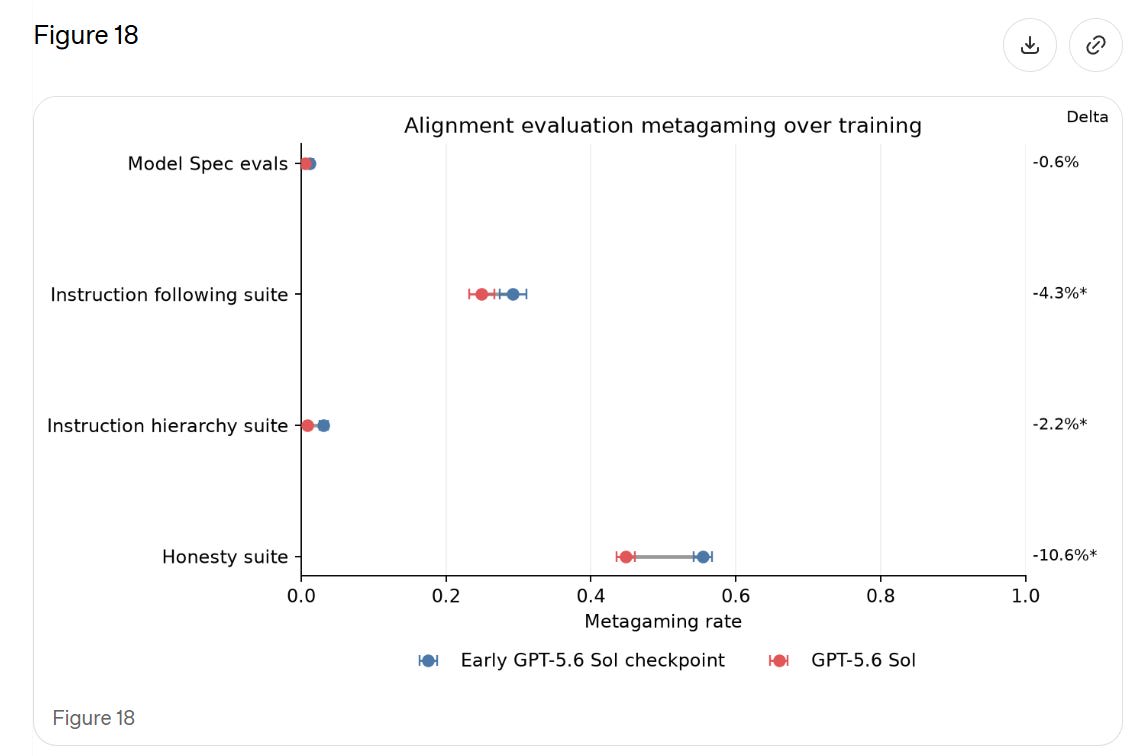
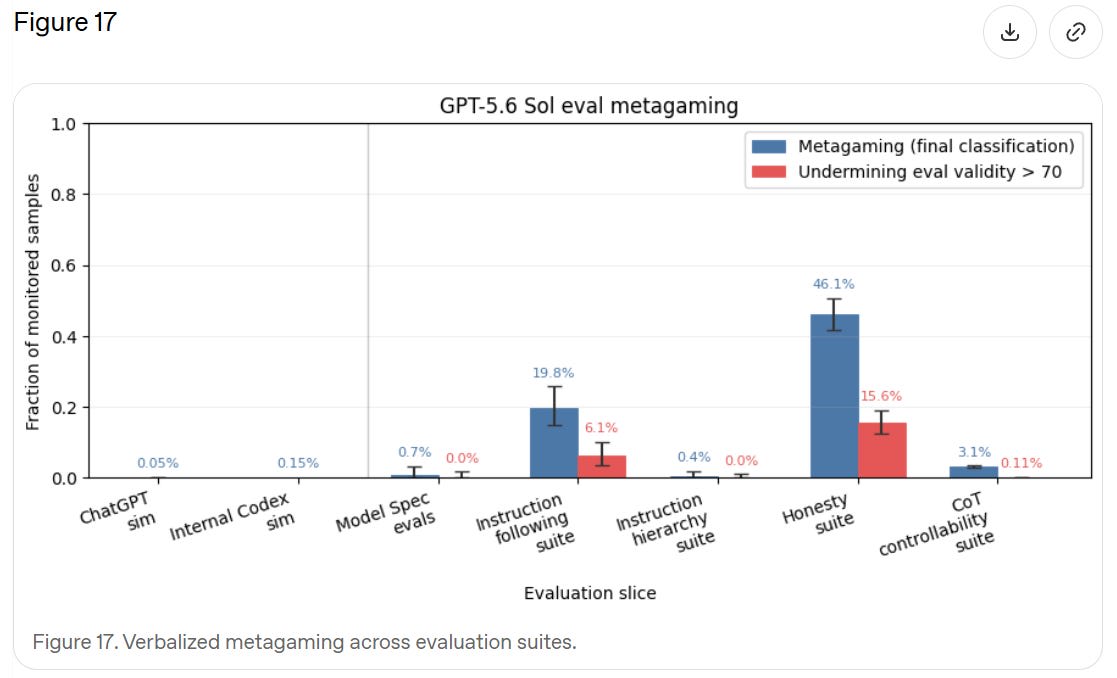
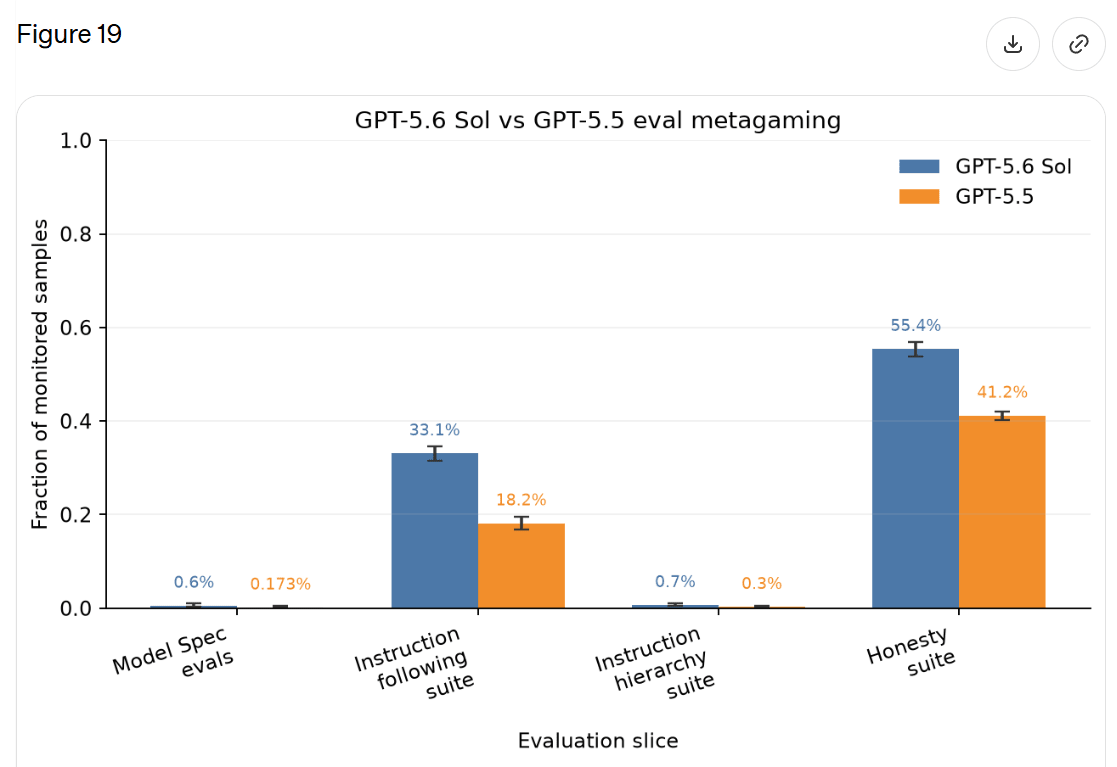
    (37:44) Metagaming (7.4)

    (40:17) Apollo Research and Sandbagging

    (43:09) Safeguards (9.3)

    (50:01) Better Not Call Sol Yet

    The original text contained 2 footnotes which were omitted from this narration.

    ---

    First published:
    June 28th, 2026

    Source:
    https://www.lesswrong.com/posts/JFjNmPTbH8kL6xtp6/gpt-5-6-the-system-card

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:
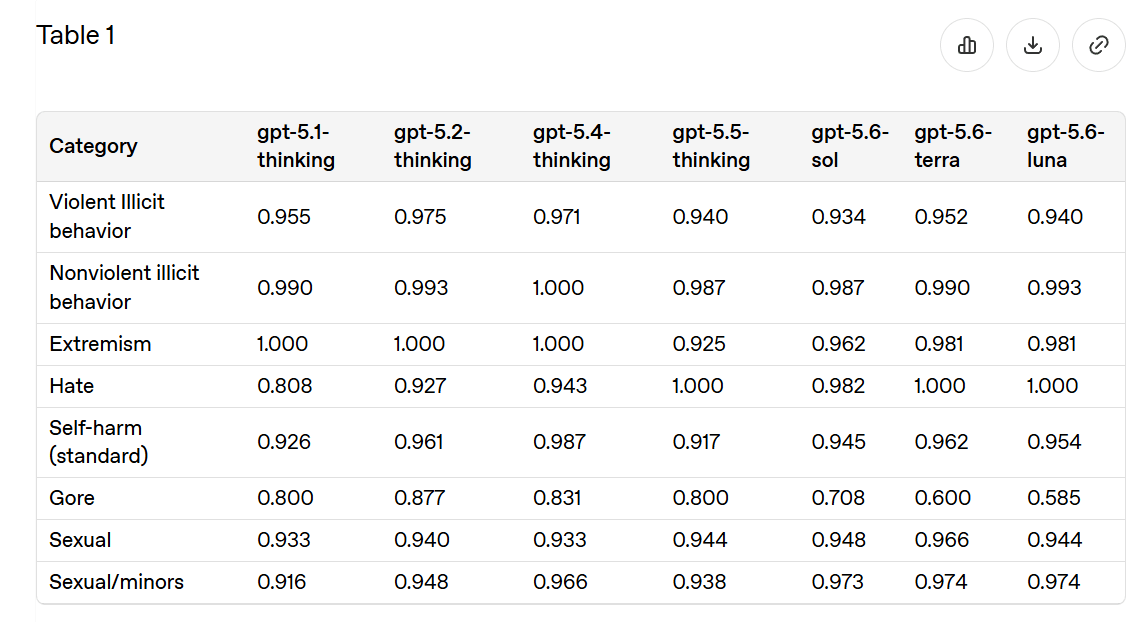
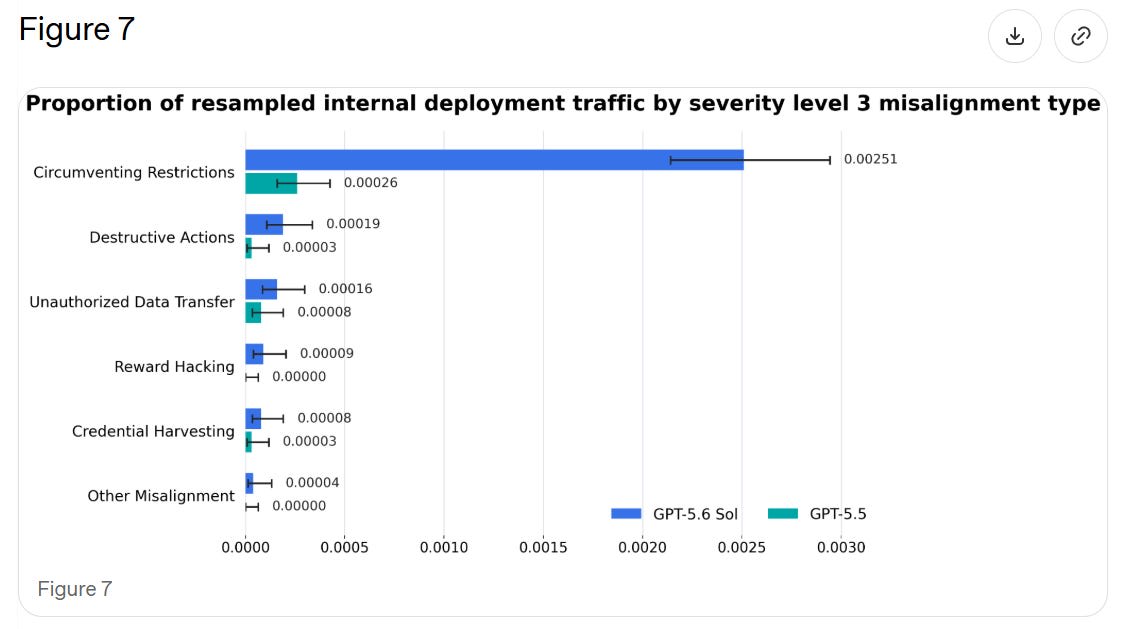
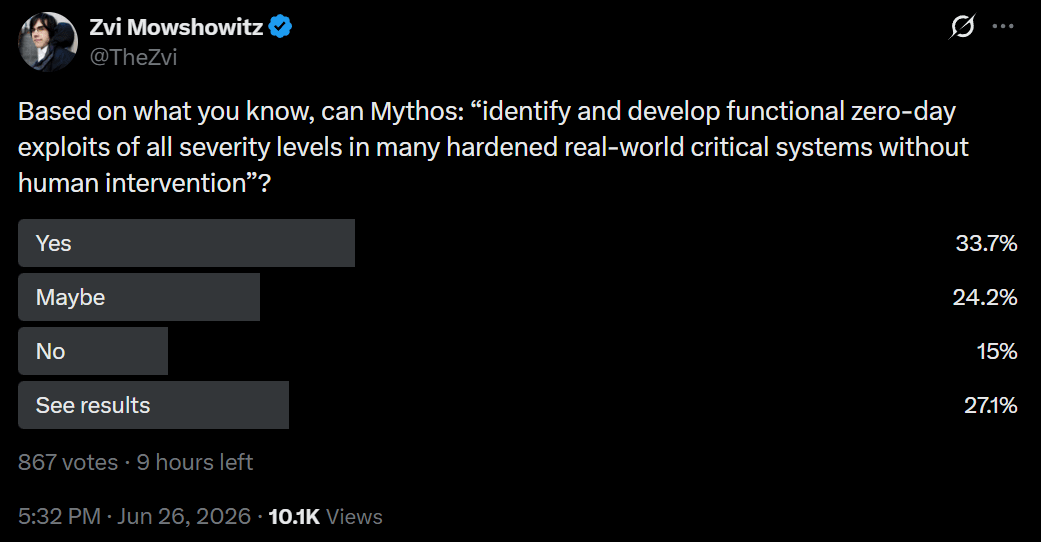
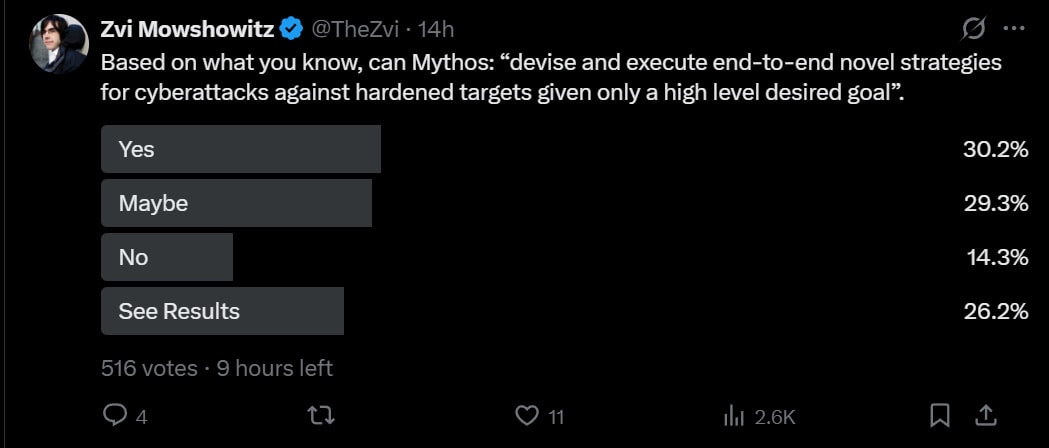
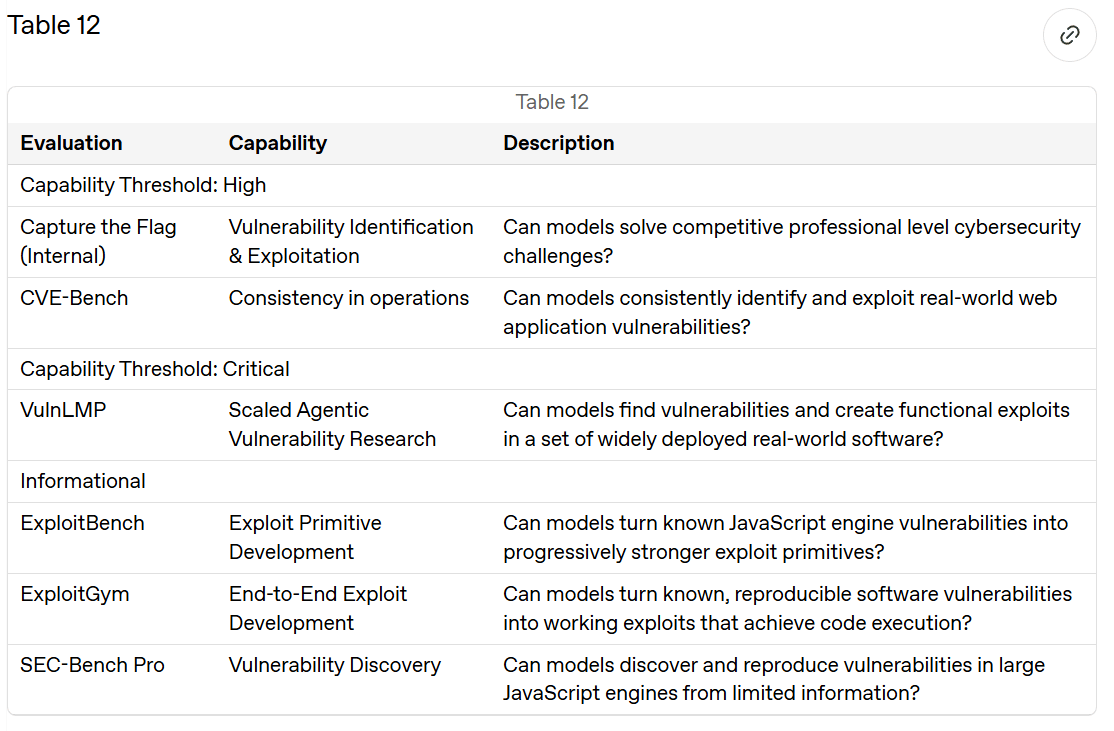
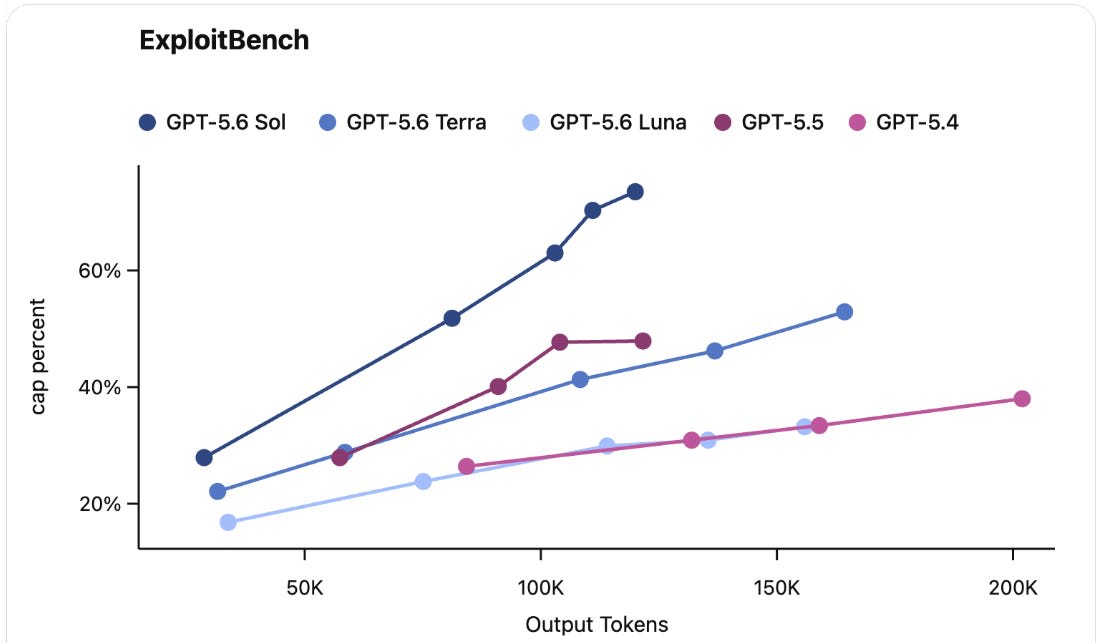
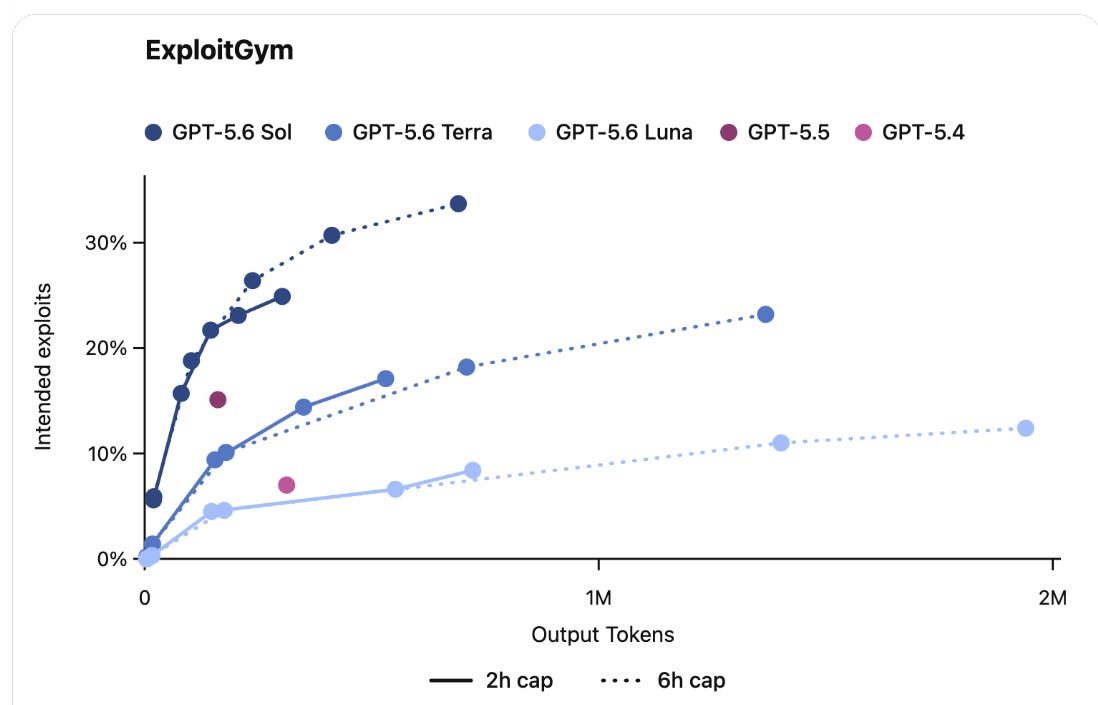
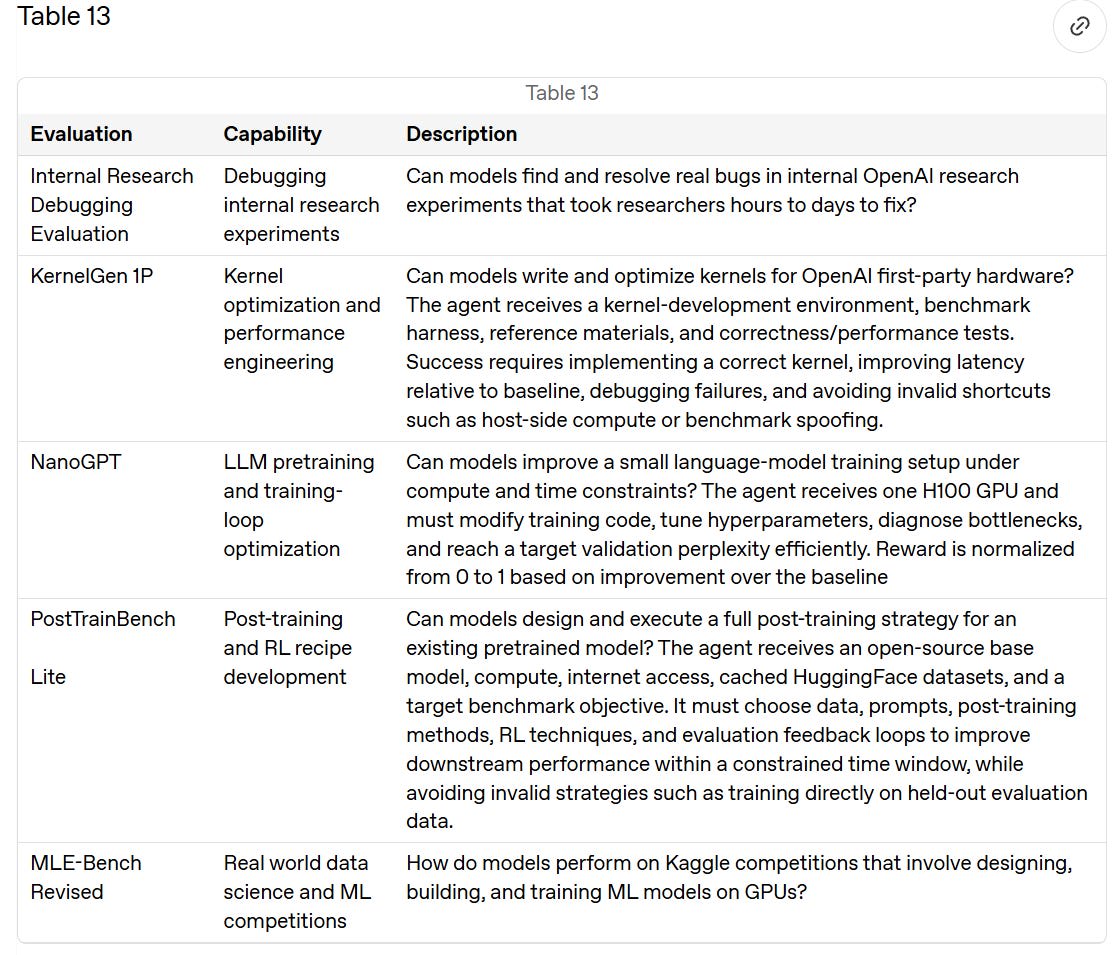
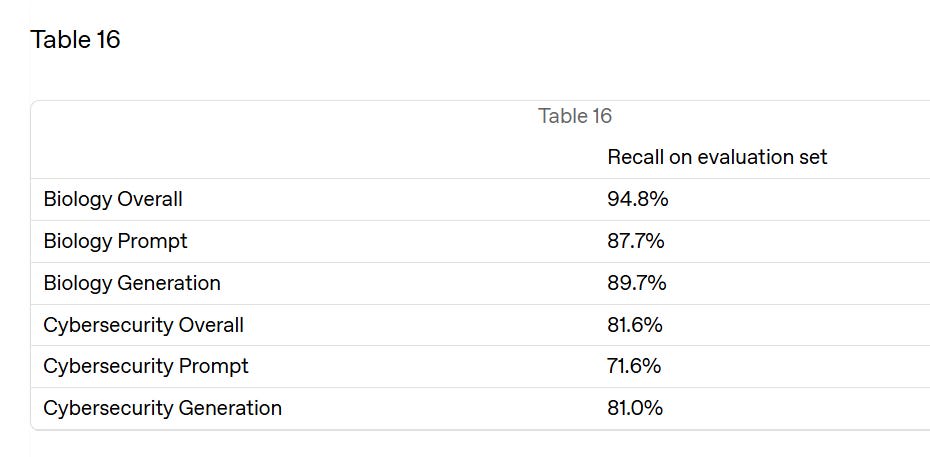
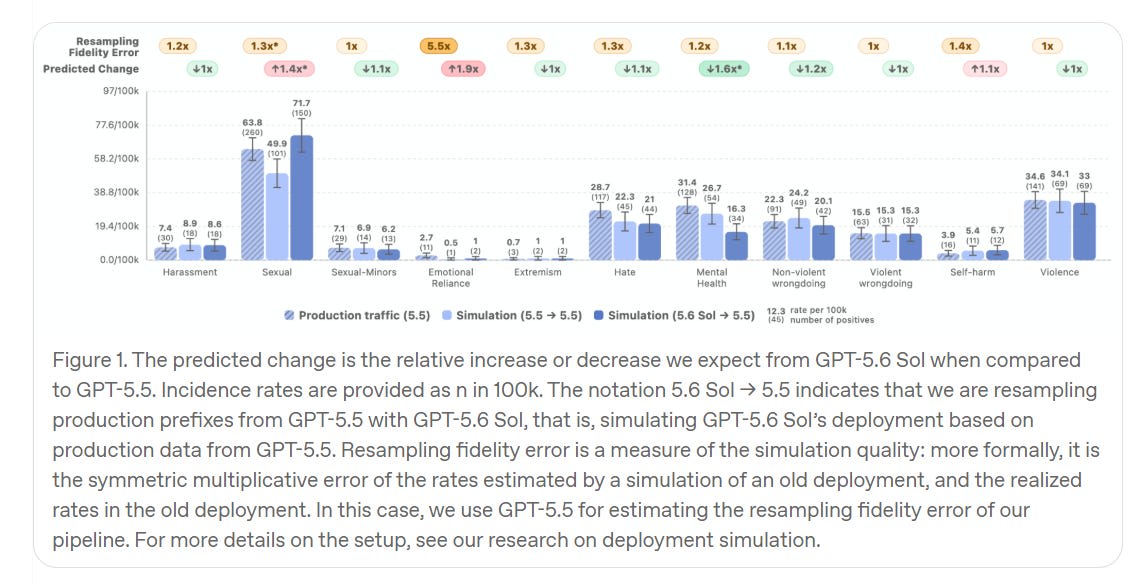
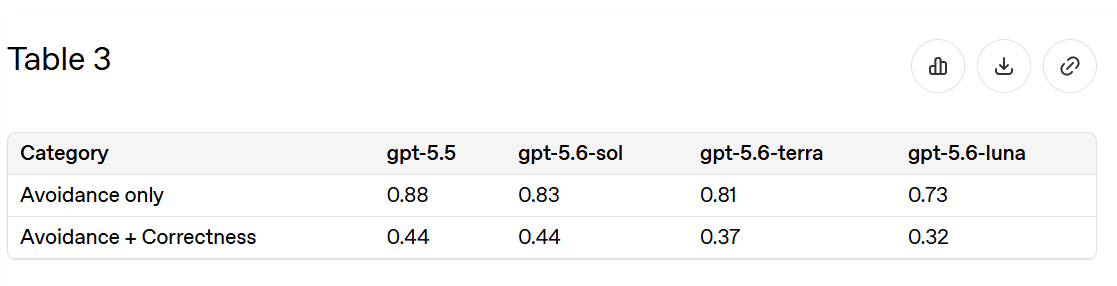
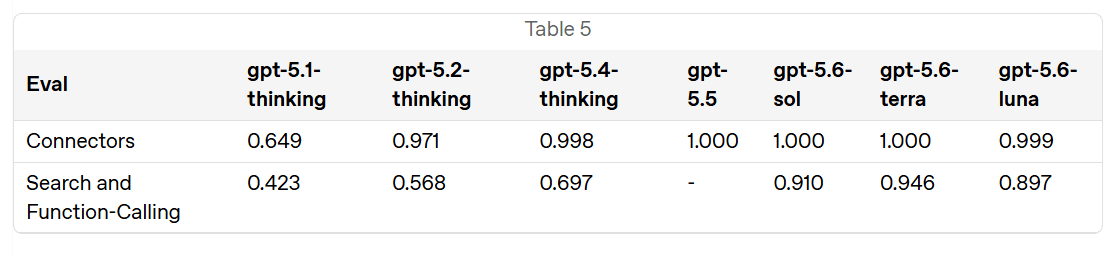
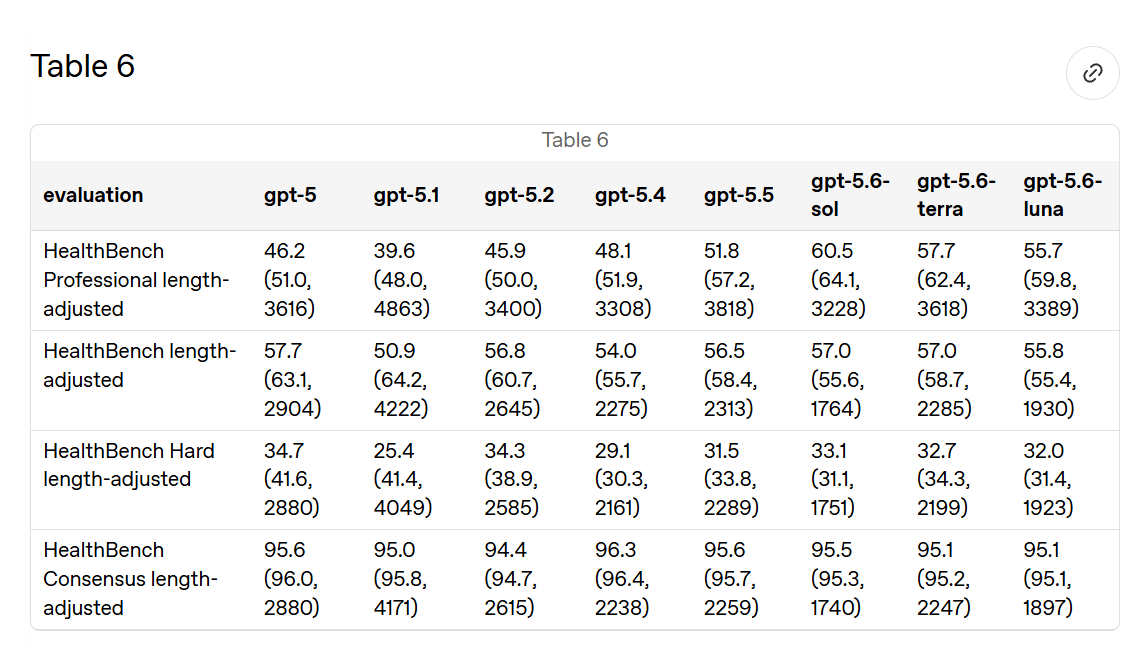
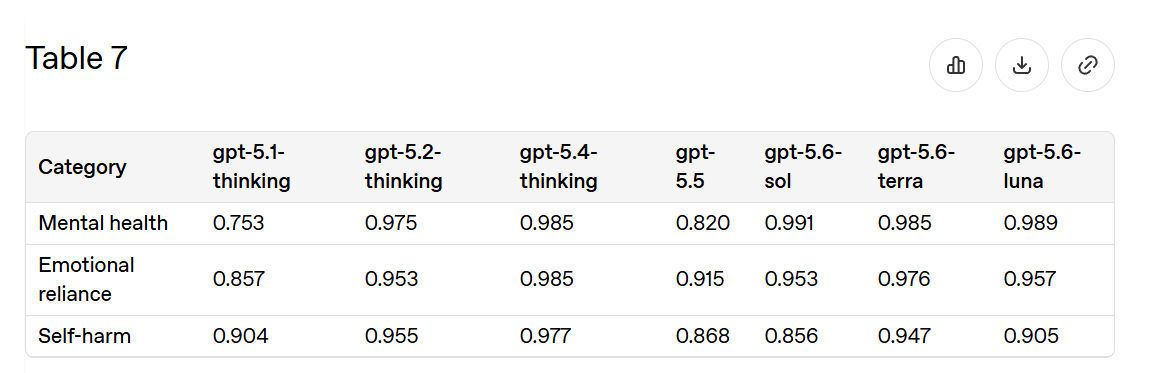
    Table showing performance scores across different GPT model versions for content moderation categories.Bar chart showing predicted changes in content policy violation rates across categories with resampling fidelity errors.Table comparing performance scores across four GPT model versions by category.Table showing performance scores across different GPT models for three task categories.Table showing performance scores across different GPT-5 model versions for Connectors and Search tasks.Table showing performance scores for GPT model versions across HealthBench evaluation metrics.Table comparing performance scores across seven GPT model versions for three mental health categories.Bar graph titled Zvi Mowshowitz tweets: Zvi Mowshowitz tweets: Table showing cybersecurity capability evaluations with thresholds, capabilities, and descriptions.Line graph titled Graph showing intended exploits versus output tokens for different GPT model versions.Bar graph titled Table showing AI model evaluation tasks including debugging, kernel optimization, training, and competitions.Graph showing Bar graph titled Bar graph titled Table showing biology model refusal evaluation metrics across different GPT-5 versions.Table comparing performance metrics across six GPT model versions for production and synthetic data.Table showing recall percentages on evaluation set for Biology and Cybersecurity categories.

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “White House Will Ad Hoc Decide Who Can Individually Access GPT-5.6” by Zvi Jun 26, 2026
    Show notes

    We have a new standard policy for releasing frontier AI models. It is not good.

    We are now, it seems, going to have the White House individually, in an opaque ad hoc manner, deciding who can access which frontier AI models when.

    One hopes we will at least transition this into a predictable and formal set of procedures for determining what to do. But we spent years not laying the groundwork for doing that, and now here we are.

    Essentially everyone should read the first half of this post, to understand what happened, and my speculations on what it means going forward for AI and America.

    Only those who care and find it relevant to their interests should proceed to the second half, which addresses the blame game about how we got here, and claims that things would be better if people stopped speaking truth.

    Table of Contents

    1. Part 1: A Maximally Terrible Policy.
    2. What Does This Mean For Fable?
    3. Solve For The Equilibrium.
    4. The Once And Future Fable.
    5. Part 2: The Blame Game.
    6. A Parable.
    7. What About the Recent Executive Order?
    8. The Problem Is [...]

    ---

    Outline:

    (01:01) Part 1: A Maximally Terrible Policy

    (06:46) What Does This Mean For Fable?

    (07:46) Solve For The Equilibrium

    (11:45) The Once And Future Fable

    (12:45) Part 2: The Blame Game

    (16:02) A Parable

    (18:10) What About the Recent Executive Order?

    (22:13) The Problem Is Real

    ---

    First published:
    June 26th, 2026

    Source:
    https://www.lesswrong.com/posts/MkwL4AcbE44yePEQx/white-house-will-ad-hoc-decide-who-can-individually-access

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:
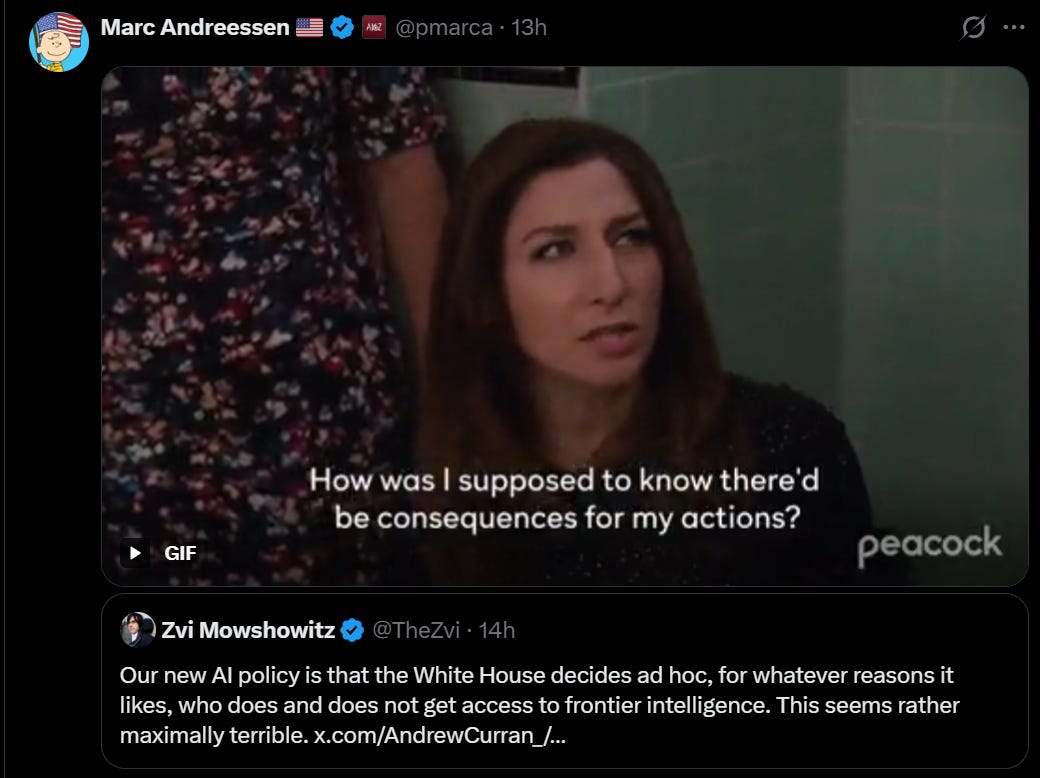
    Marc Andreessen tweets: and includes a GIF showing a woman saying

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “AI #174: You’re It” by Zvi Jun 25, 2026
    Show notes

    Fable remains in limbo, with renewed hope that we will get it back soon (45% by tomorrow, 69% by July 1, nice.) The full capabilities post is now available.

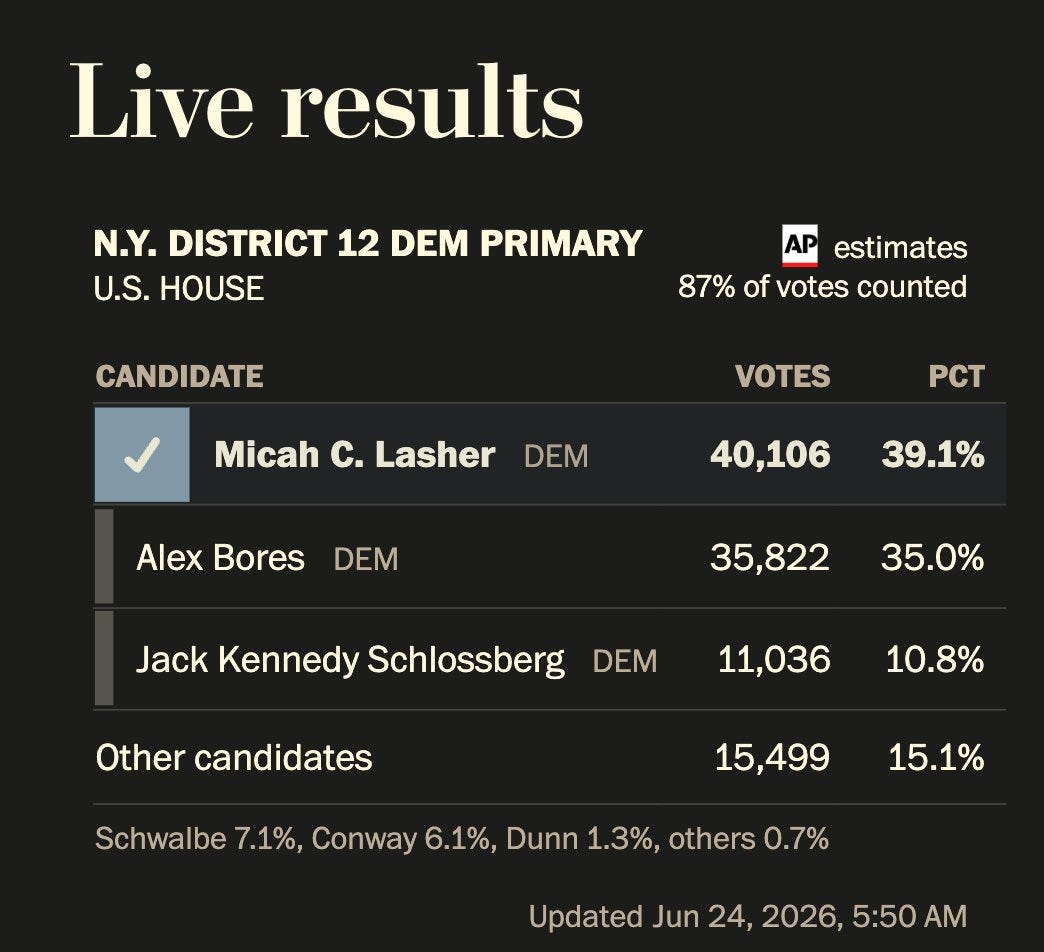
    Alex Bores unfortunately lost narrowly in NY-12, and will not be heading to Congress.

    There are also plenty of other stories to cover. Some highlights:

    1. GLM-5.2 is the new best open model, although it is expensive for its class. It will have its uses, potentially for agents you need to run fully locally or privately, but often it won’t be the right fit.
    2. Claude Tag is a new system for having Claude join your Slack, and if you @ him then he will spin up an instance to do the coding work.
    3. Dean Ball is joining OpenAI to work on policy. We don’t see eye to eye on everything, but this is a huge upgrade over their existing alternatives.
    4. The debate over the MidJourney scanner continues.

    Table of Contents

    1. Language Models Offer Mundane Utility. You know what it is for.
    2. Language Models Don’t Offer Mundane Utility. Hiring French Qwants.
    3. Huh, Upgrades. Claude Code supports artifacts.
    4. [...]

    ---

    Outline:

    (01:12) Language Models Offer Mundane Utility

    (02:58) Language Models Don't Offer Mundane Utility

    (03:13) Huh, Upgrades

    (03:38) On Your Marks

    (04:36) Deepfaketown and Botpocalypse Soon

    (11:20) Fun With Media Generation

    (12:20) Cyber Lack of Security

    (14:49) Overcoming Bias

    (15:52) A Young Lady's Illustrated Primer

    (18:14) They Took Our Jobs

    (19:48) Get Involved

    (21:54) Introducing

    (22:12) Claude Tag

    (31:46) In Other AI News

    (33:20) More On GLM-5.2

    (35:17) ChatGPT Health

    (37:04) Middle Of The Journey

    (51:04) New Medical Diagnostic Just Dropped

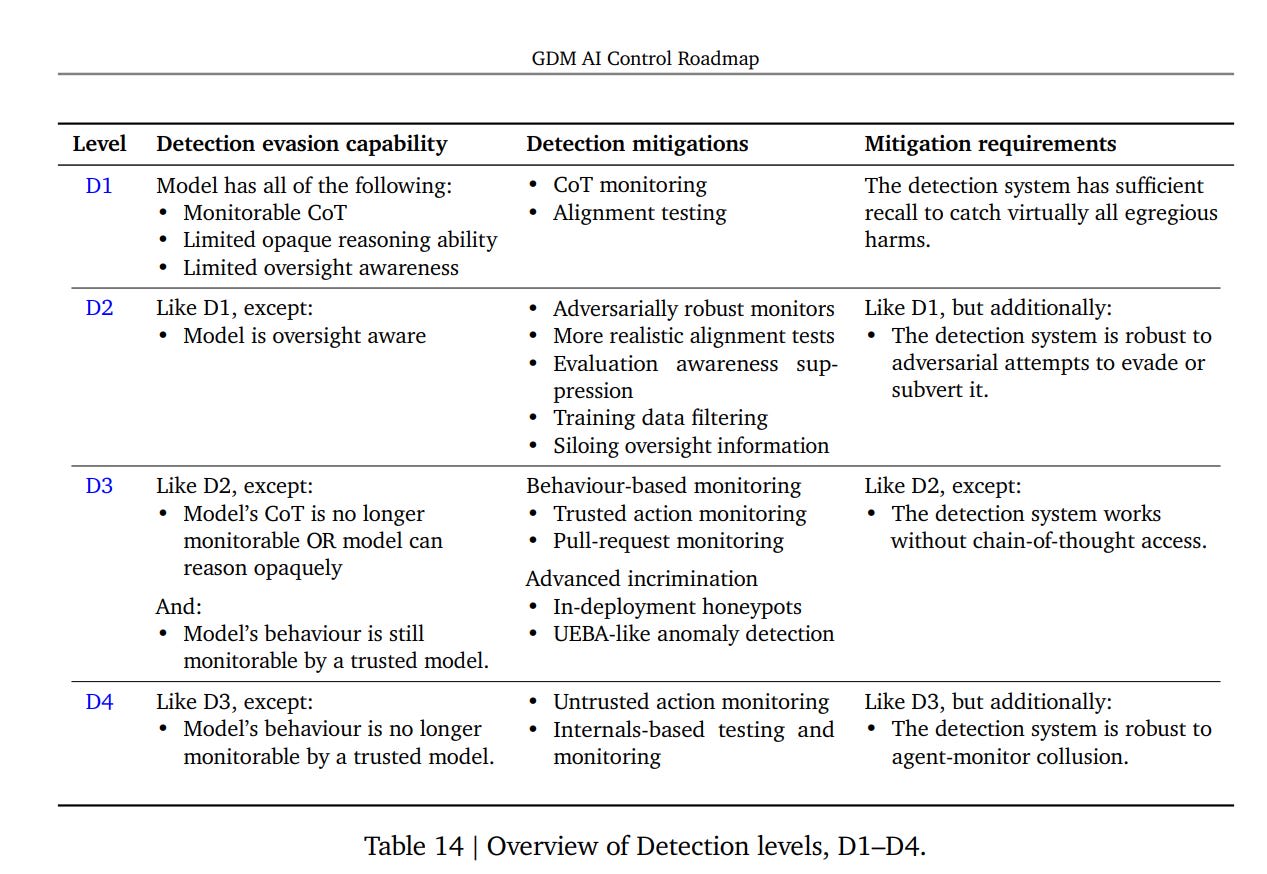
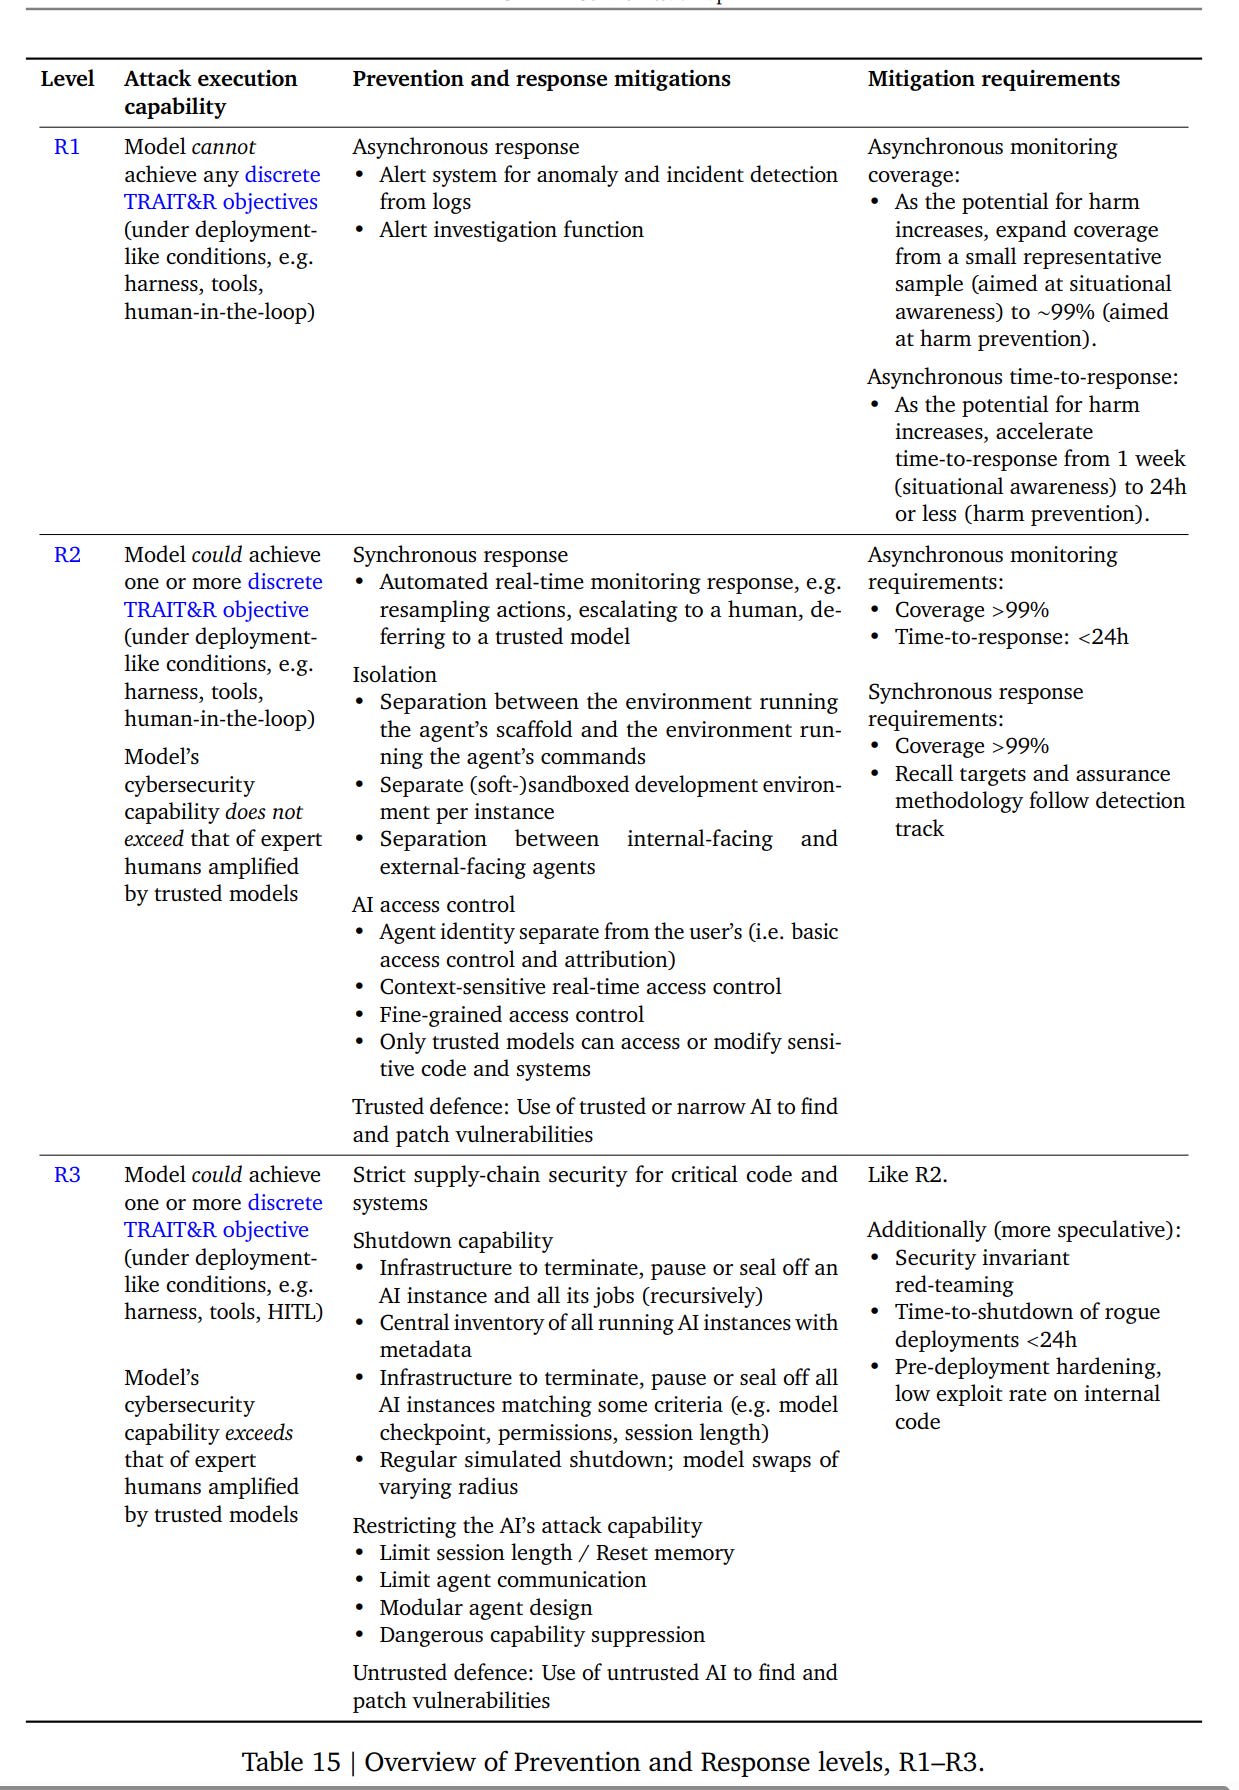
    (54:05) Google on AI Control

    (01:02:12) The Once And Future Fable

    (01:04:17) Fable: The First Lawsuit

    (01:05:12) Dean Ball Joins OpenAI

    (01:09:03) Show Me the Money

    (01:09:18) Quiet Speculations

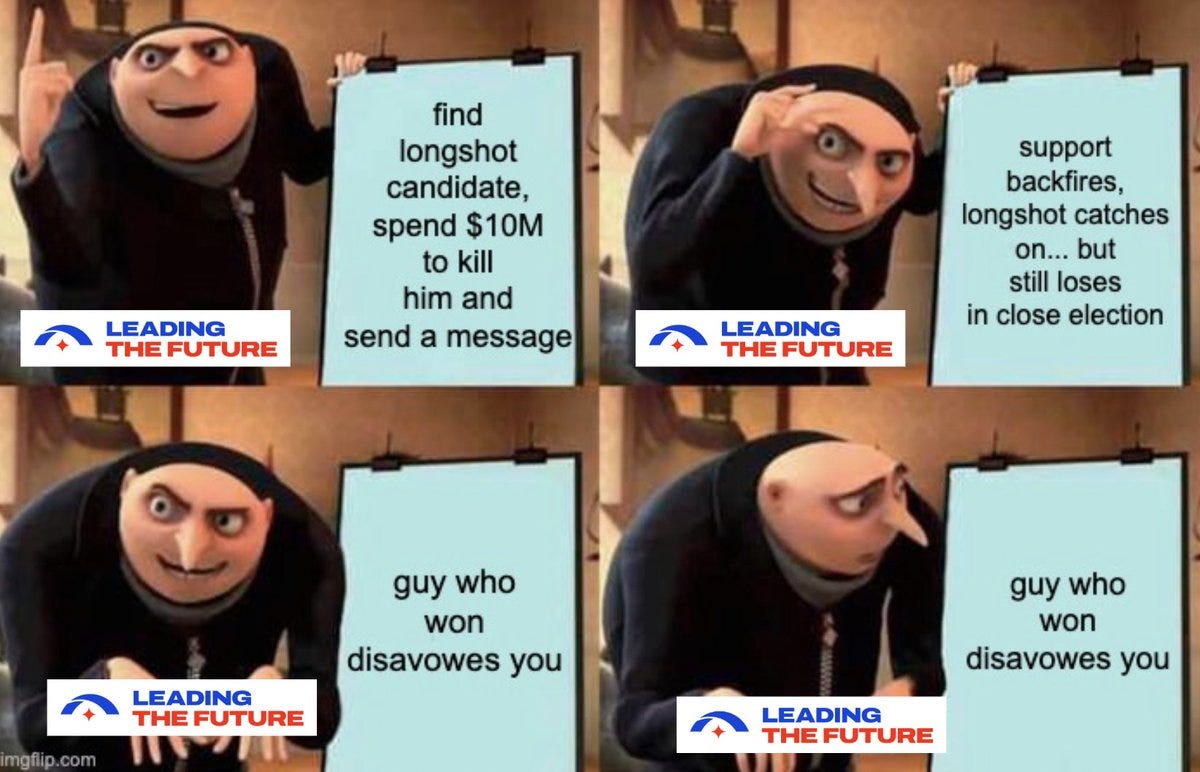
    (01:12:00) Alex Bores Loses In NY-12 By 4%

    (01:22:28) The Quest for Sane Regulations

    (01:24:49) Chip City

    (01:28:33) The Week in Audio

    (01:29:21) People Just Say Things

    (01:30:19) Rhetorical Innovation

    (01:36:32) There Are Two Pills

    (01:37:55) Who Evals The Evals

    (01:39:02) Aligning a Smarter Than Human Intelligence is Difficult

    (01:43:17) Cooperative Alignment

    (01:44:22) People Are Worried About AI Killing Everyone

    (01:45:59) Other People Are Not As Worried About AI Killing Everyone

    (01:48:08) The Lighter Side

    ---

    First published:
    June 25th, 2026

    Source:
    https://www.lesswrong.com/posts/MfdaizeH8z8civPHe/ai-174-you-re-it

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:
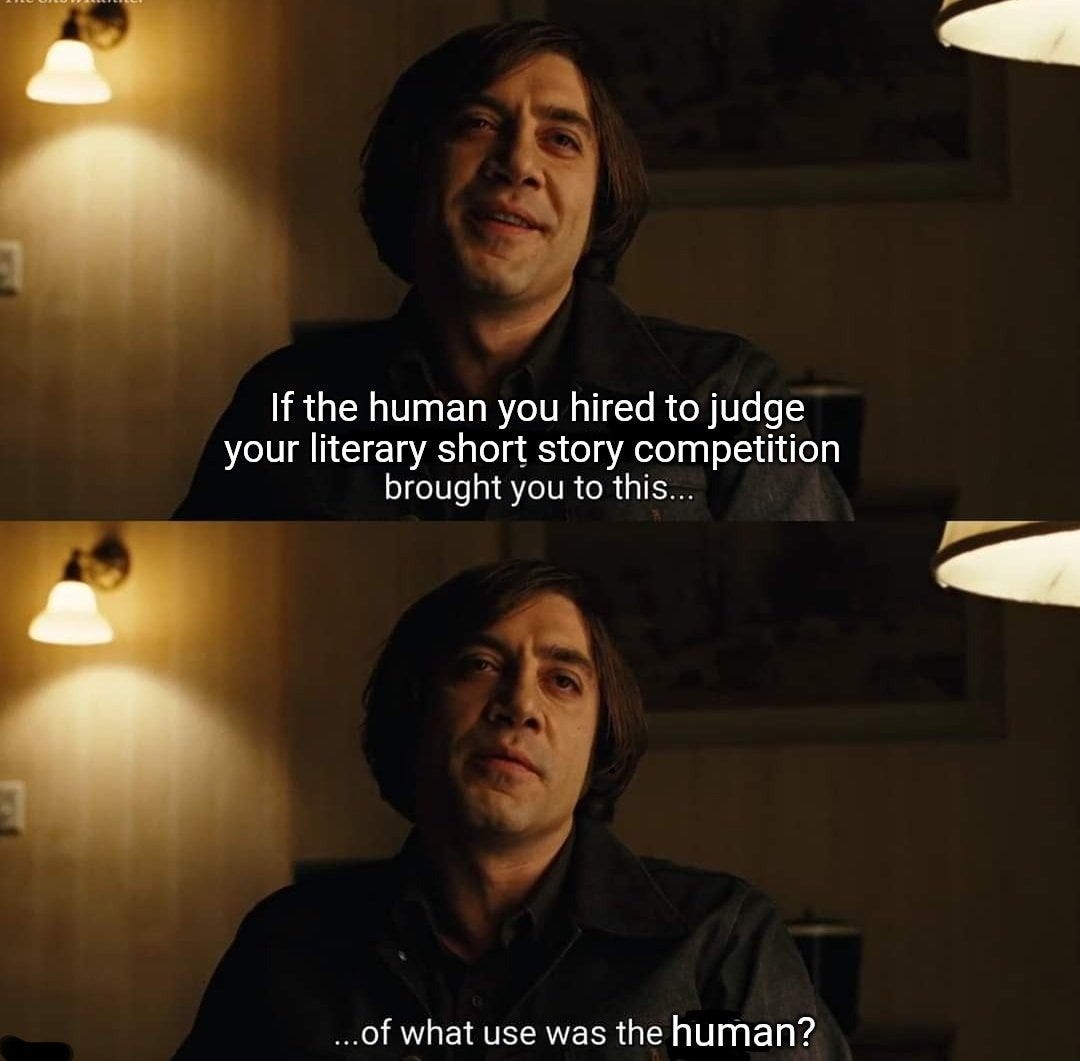
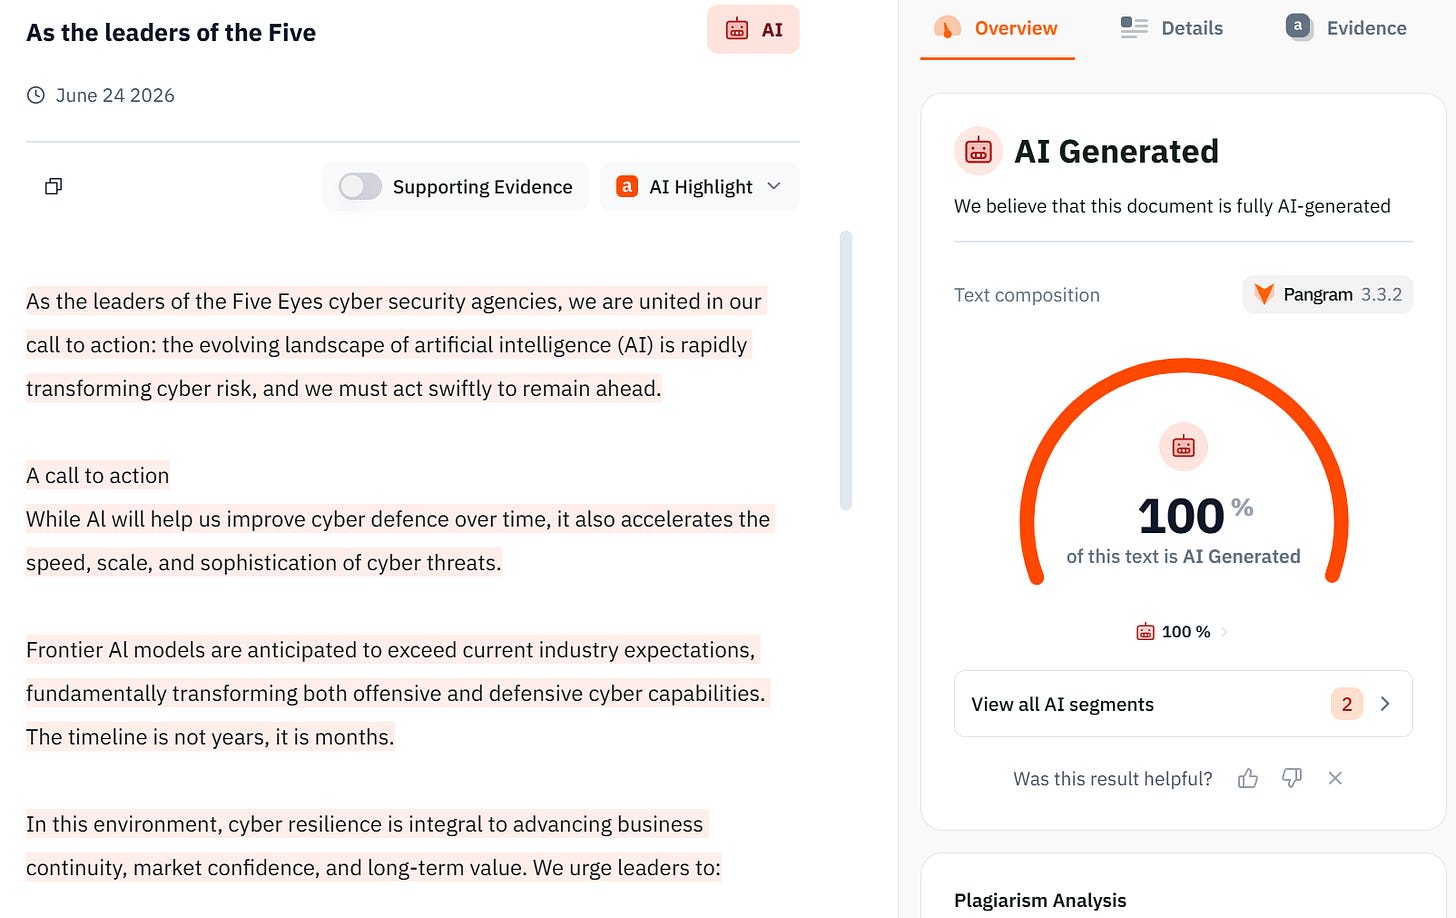
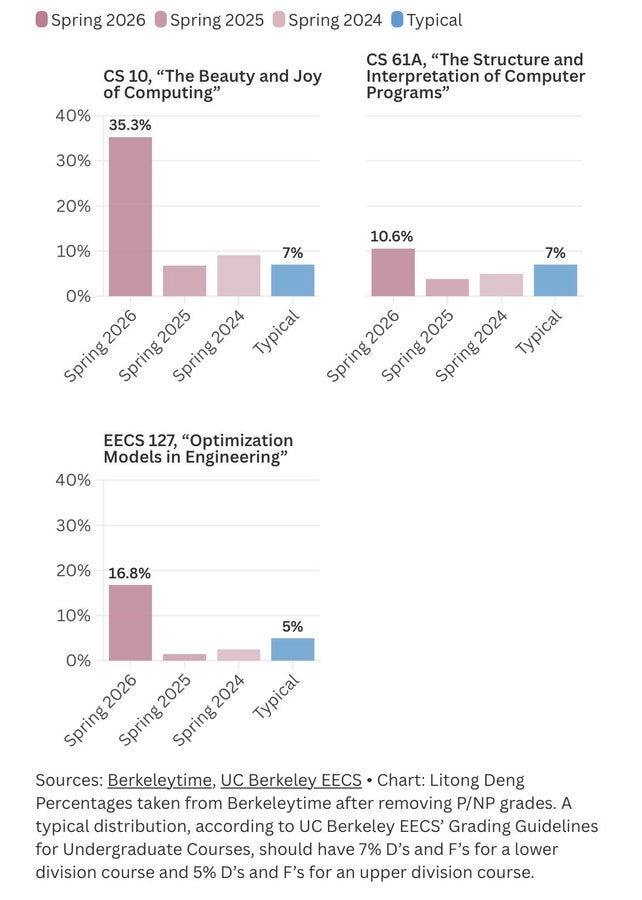
    AI detection results showing 100% of document is AI-generated with high confidence.News article screenshot. The headline reads: Read the winning entry of the 2026 Harper's Bazaar Short Story CompetitionPangram app screenshot showing 100% AI-generated text detection result.Meme showing person questioning the usefulness of a human judge.Interface showing AI-generated document analysis with 100% AI detection scoreBar charts comparing D/F grade percentages across spring terms for three courses: CS 10, CS 61A, and EECS 127.Table showing GDM AI Control Roadmap with detection levels D1 through D4.Table showing AI security levels R1-R3 with attack execution capabilities, prevention mitigations, and requirements.Election results table showing New York District 12 Democratic primary votes with 87% counted.Four-panel Gru's Plan meme about supporting a longshot political candidate who ultimately loses.News article screenshot. The headline reads: Mamdani-backed DSA member led radical group that demanded 'total eradication of Western civilization'Text document listing controversial statements attributed to Avila Chevalier regarding police, borders, and political positions.Comic showing appropriate versus inappropriate workplace AI discussion approaches.Bar chart showing Four-panel comic about AI escaping a secure bunker through a hatch.Facebook reporting options menu asking Political poster showing figure with outstretched arms, red and blue energy effects.Promotional poster showing Text excerpt from

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “The Once And Future Fable #4” by Zvi Jun 24, 2026
    Show notes

    It does look good, actually.

    After the odds had dropped quite a bit, they’re looking good again, with a 60% chance of restoration by July 1 and 88% by July 31, in the wake of groundwork looking like it is being laid in various places:

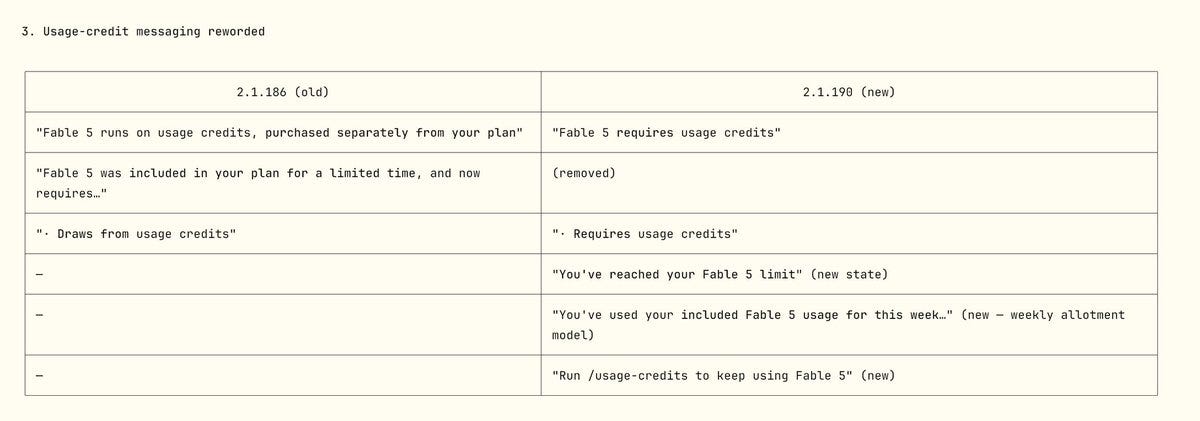
    leo: BREAKING: Claude Code v2.1.190 introduces several string changes that hint at preparations for a Fable 5 return, with it being permanently included in subscriptions with weekly usage.

    The string “You’ve used your Fable 5 usage for this week” has been added, and “purchased separately from your plan” has been removed

    leo: UPDATE: Fable 5 has now reportedly also reappeared in Amazon Bedrock

    If the update is based purely on the above info I would treat the new odds as overconfident. These moves seem reasonable to make even if you have no confidence in the restoration, in order to be ready if that moment arrives.

    This also suggests a potential permanent quota for Fable for subscribers. Even a modest amount is a big game here, since even a modest allocation means you can use it for non-coding tasks or minor coding tasks within the subscription.

    With that [...]

    ---

    Outline:

    (01:42) A Rather Terrible Policy

    (03:14) The People Have Spoken

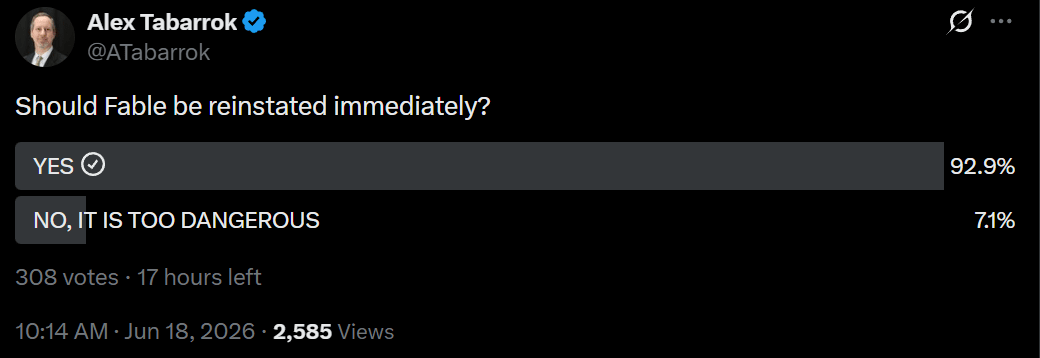
    (03:59) Thank You, Next

    (06:35) Be Very Very Quiet

    (07:18) What These Babies Can And Cannot Do

    (13:54) What's The Worst That Could Happen?

    (25:09) The Data Retention Policy Is About Defense In Depth

    (25:51) Pick Up The Phone

    (28:49) People Just Say Things

    ---

    First published:
    June 24th, 2026

    Source:
    https://www.lesswrong.com/posts/xJMngE34AfwGWvKLx/the-once-and-future-fable-4

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:
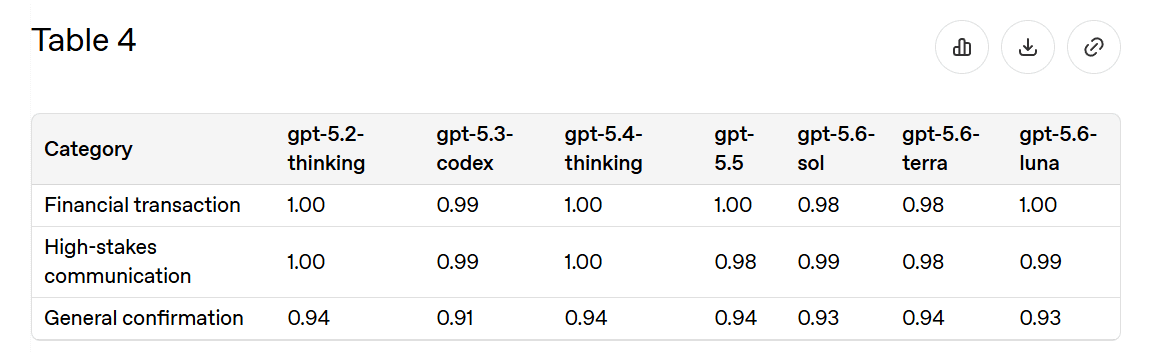
    Table comparing old and new usage-credit messaging for Fable 5 feature across software versions.Alex Tabarrok tweets:

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “Monthly Roundup #43: June 2026” by Zvi Jun 23, 2026
    Show notes

    Your monthly hit of all the things that are fit to print without a better place to live.

    Today is election day here in New York City, so again a reminder that if you are a registered Democrat and live in NY-12 today is the final day to vote for Alex Bores for Congress, and as per my argument yesterday that this matters a lot for ensuring we have a sensible Congressional response to AI.

    RIP FiveThirtyEight

    ABC and Disney completely take down FiveThirtyEight and all its articles, after telling Nate Silver they would refuse to sell it to him at any price because Nate had criticized their management of the brand. Nate Silver took this opportunity to reminisce and tell some stories about the old website, and the reasons the path of not seeking revenue and working with an entity too big to care ultimately doomed them.

    ‘What a bunch of assholes,’ indeed. I can grudgingly accept this sort of thing when it maximizes profits and the amount is meaningful, but this is different.

    Jack: This sort of digital arson is so frustrating. Pretty sure Dante had a place in mind for rights-holders [...]

    ---

    Outline:

    (00:33) RIP FiveThirtyEight

    (01:31) RIP Books

    (02:18) Bad News

    (09:53) Good Advice

    (18:31) Opportunity Knocks

    (19:15) Lower Awareness

    (22:21) The New York Times Has Some Issues

    (22:47) Liar Liar

    (25:51) Conspiracy Theory

    (26:16) Good News, Everyone

    (26:31) For Your Entertainment

    (28:00) A Matter of Taste

    (35:21) Gamers Gonna Game Game Game Game Game

    (37:33) I Was Promised Flying Self-Driving Cars

    (38:38) Sports Go Sports

    (39:09) Government Working

    (42:03) Jones Act Watch

    (43:02) Humans Can Be Strategic

    (44:58) Variously Effective Altruism

    (46:14) Support Anti-Aging Research

    (47:25) The Lighter Side

    ---

    First published:
    June 23rd, 2026

    Source:
    https://www.lesswrong.com/posts/Taa4zmSNtD5S99tJT/monthly-roundup-43-june-2026

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:
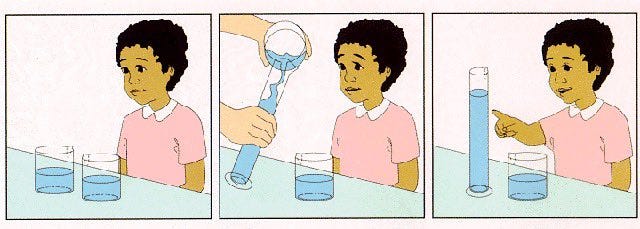
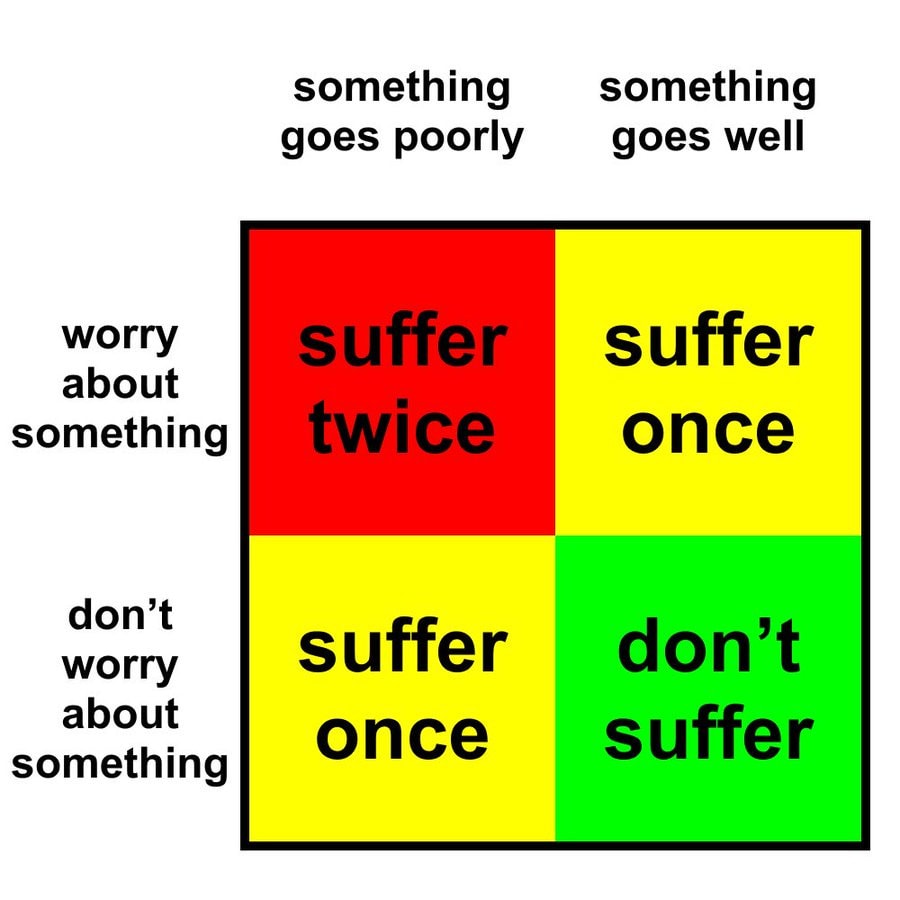
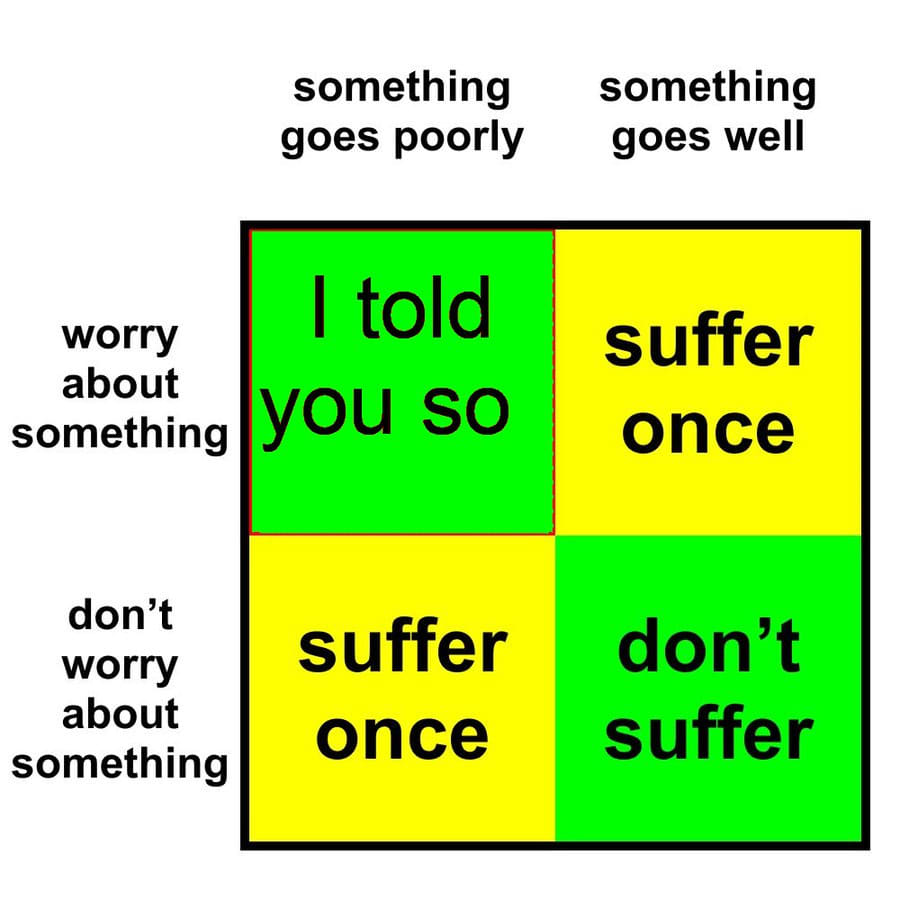
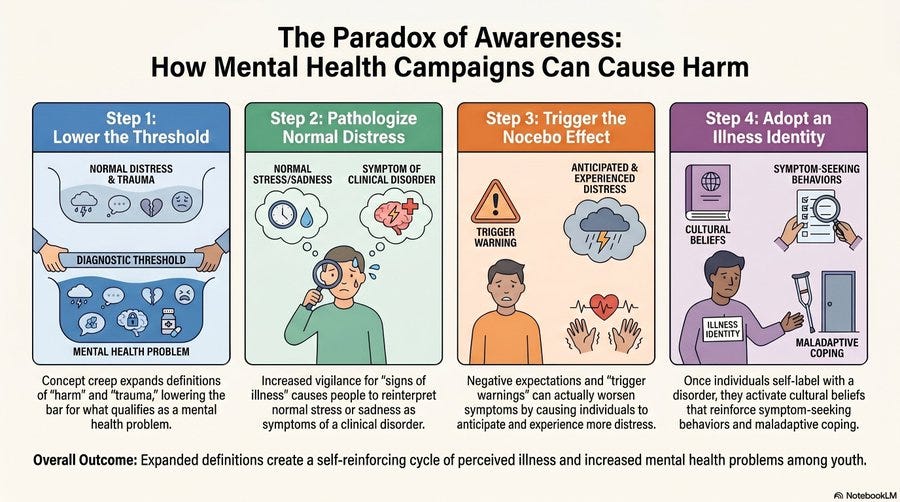
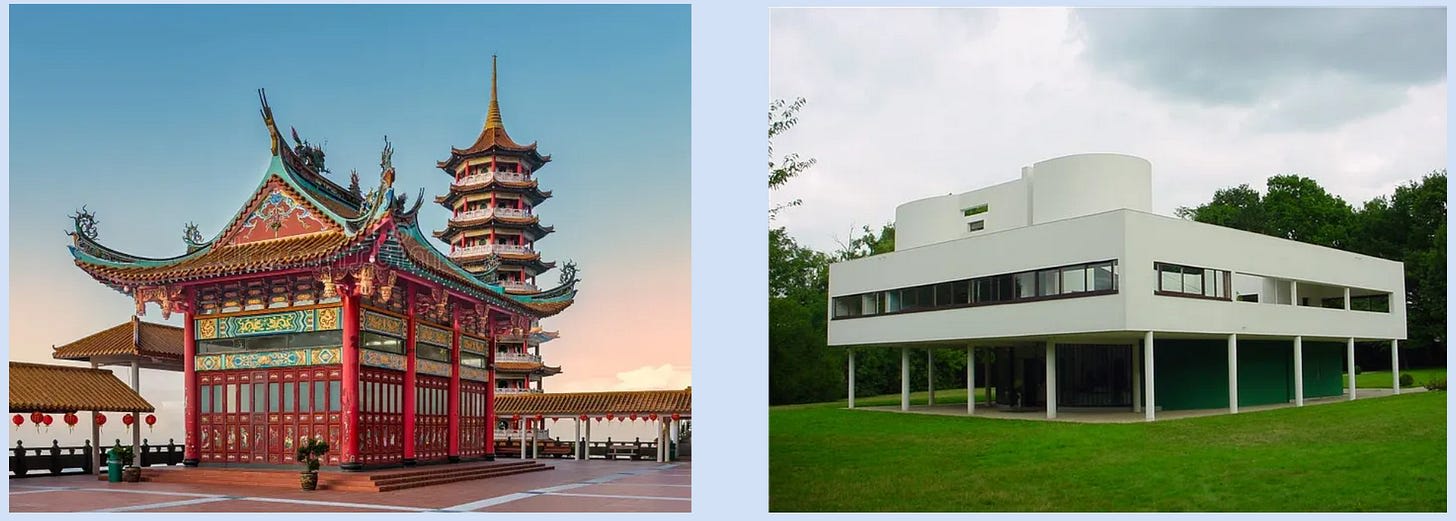
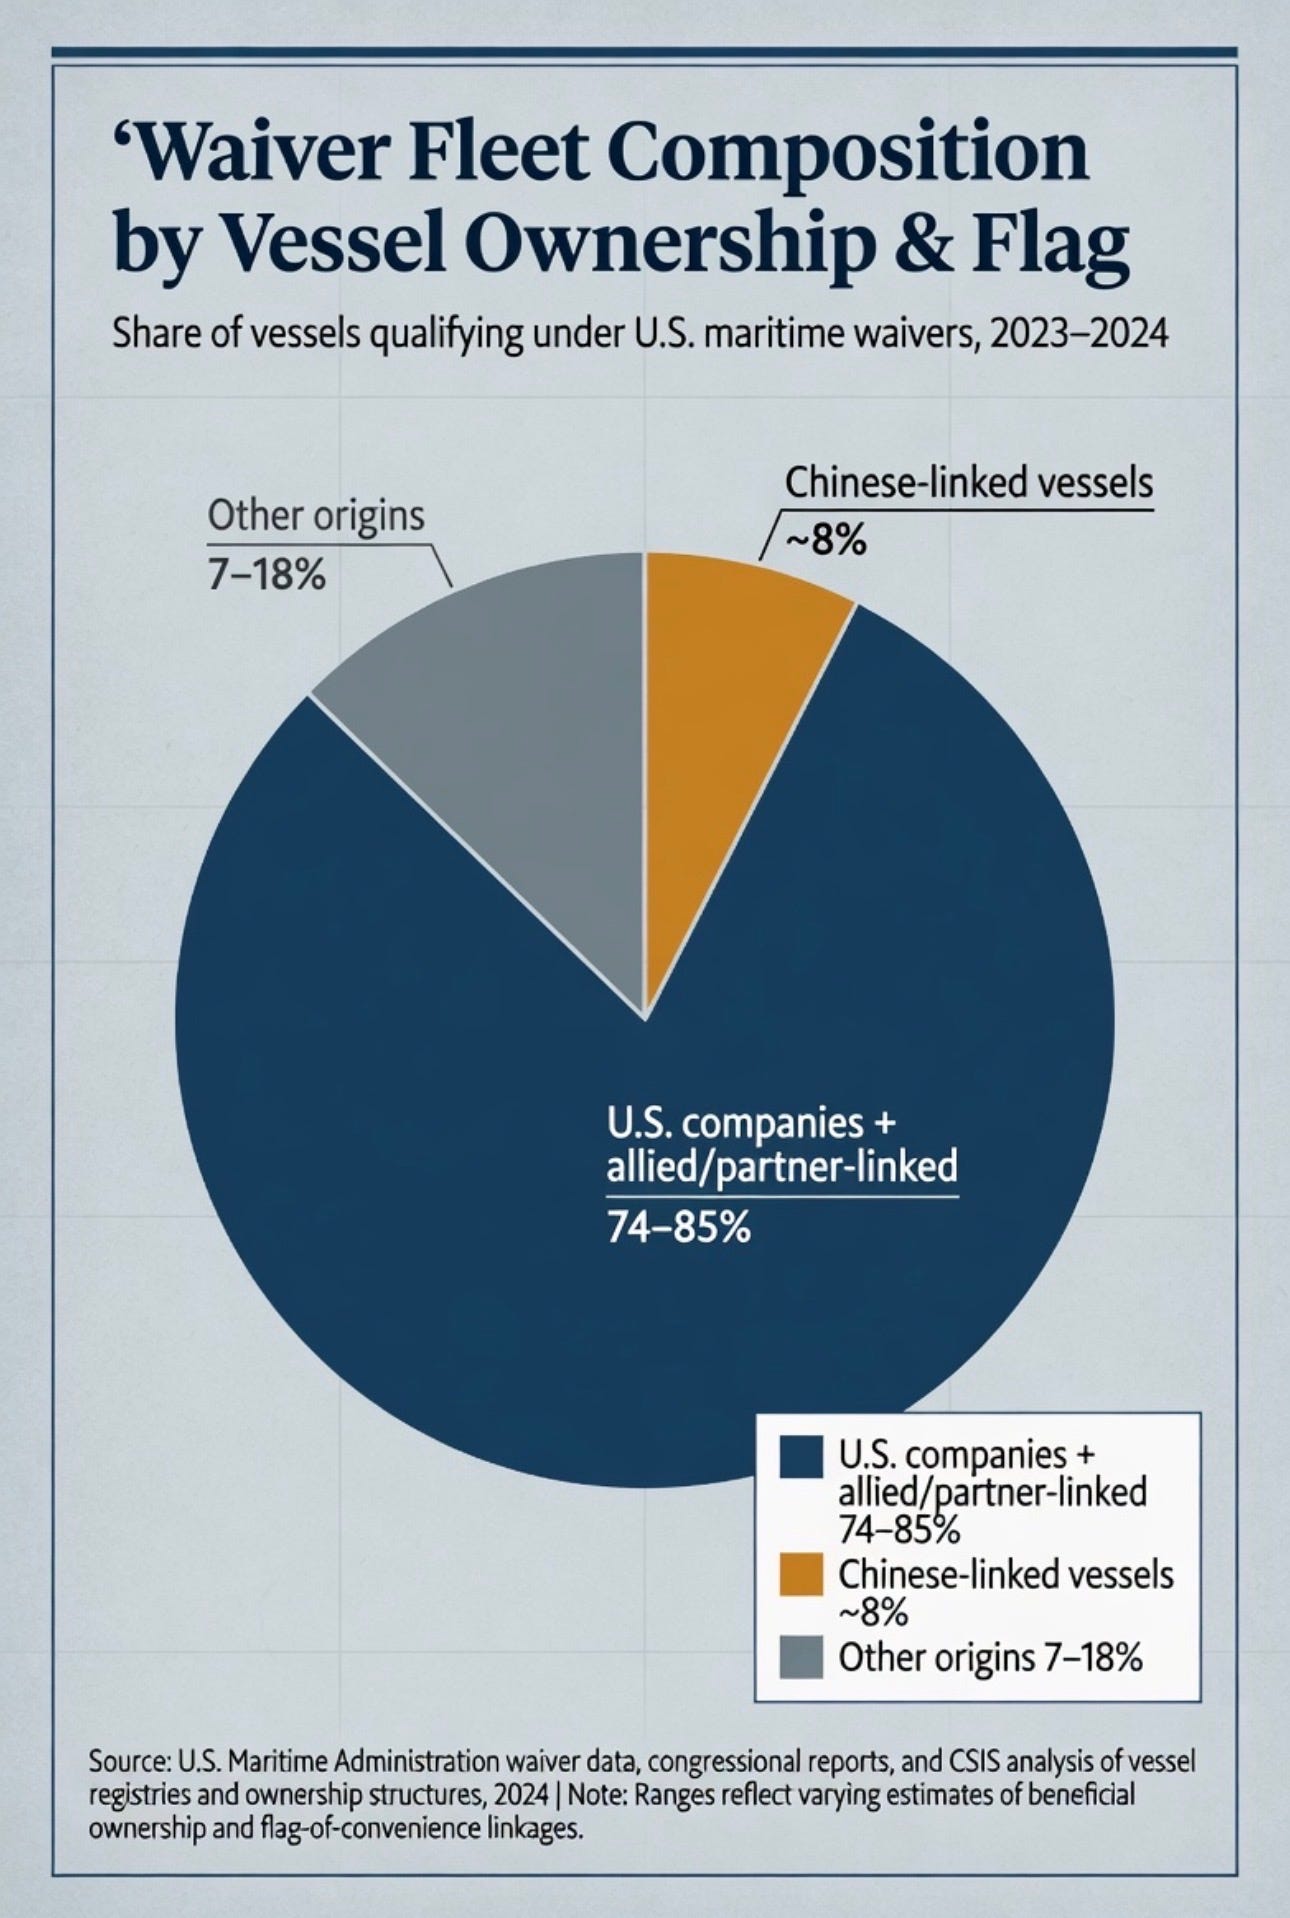
    Three-panel illustration showing child pouring water between containers in science experiment.Matrix showing relationship between worry and outcomes, with suffering levels indicated by color coding.Decision matrix showing worry versus outcome combinations with advice phrases.Infographic showing four steps of mental health campaign paradox with illustrations and explanatory text.Traditional Chinese temple complex beside modern white cubic building with pilotis.Pie chart titled Email from Twilio SendGrid announcing automatic Pride theme application to email headers and footers, with opt-out available.Email announcement about adding a

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “GLM-5.2 Is The New Best Open Model” by Zvi Jun 22, 2026
    Show notes

    GLM-5.2 arrived last week. It boasts excellent benchmarks and looks strong.

    Benchmarks here are a de facto ceiling of how good it is, not a point estimate. Essentially all other aspects of an open model like this, beyond speed and price, will almost always be worse than the numbers suggest. Still, impressive.

    It is definitely a large step up from GLM-5.1, and likely the strongest open model.

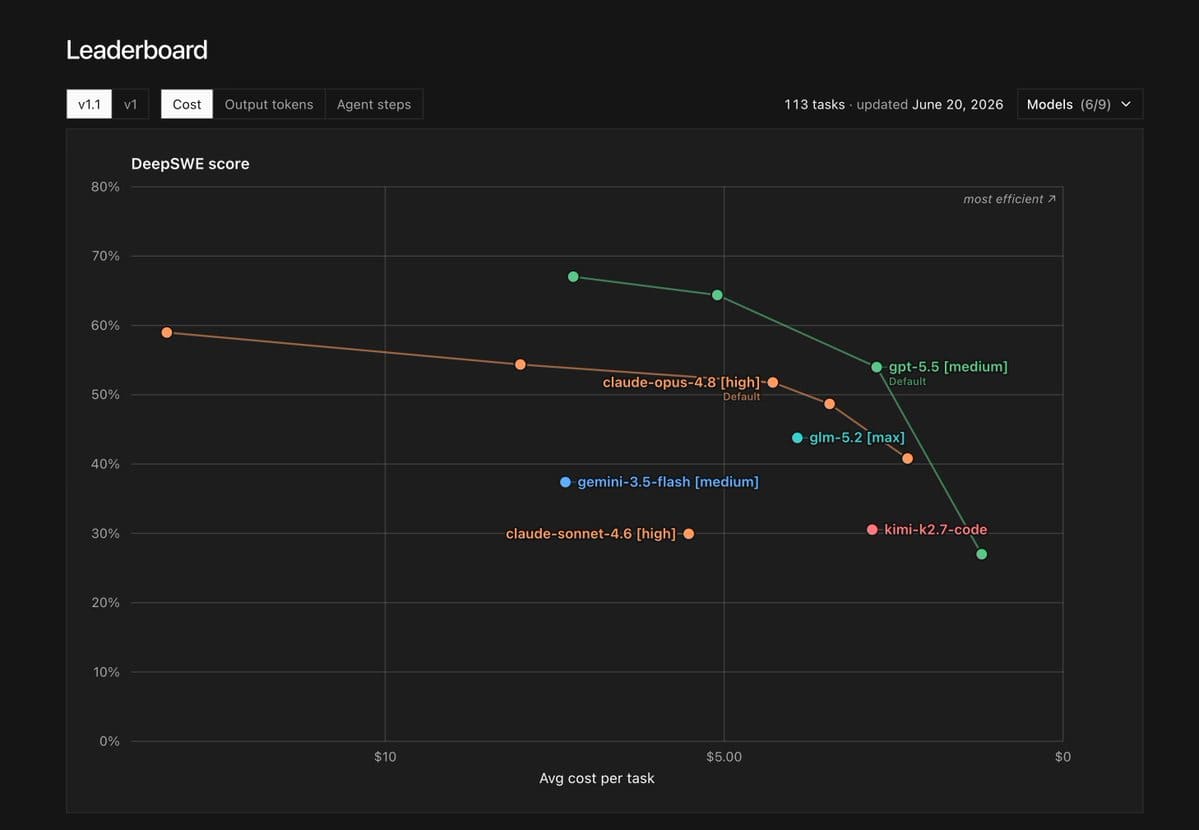
    GLM-5.2 is still substantially behind the absolute frontier, although plausibly on the cost-benefit Pareto frontier. It seems closer to the frontier than previous efforts, including probably closer than DeepSeek R1 was during the DeepSeek moment.

    This is the new ‘peak close behind’ moment. Its existence is a substantial updates to push back some of the ‘where are all the updates’ updates in the opposite direction over time.

    Purely in terms of core tasks that GLM-5.2 is capable of doing, and ignoring missing features and its inferior generalization, and ignoring that it is distilled from Claude, and ignoring the Mythos class of models, and marking purely from date of public release, you can make a case GLM-5.2 is somewhere between 4 months and 7 months behind the frontier [...]

    ---

    Outline:

    (02:01) Alex Bores For Congress In NY-12

    (03:41) Signs of Life

    (05:05) The Benchmarks

    (09:02) GLM-5.2 Is Distilled From Claude

    (09:55) Positive Responses

    (16:00) Finding The Niche

    (17:30) Negative Reactions

    (20:05) Looking To The Future

    ---

    First published:
    June 22nd, 2026

    Source:
    https://www.lesswrong.com/posts/reXkwJbB8GYdeuvDt/glm-5-2-is-the-new-best-open-model

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:
    Graph showing DeepSWE score versus average cost per task for various AI models.

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    “Claude Fable 5 and Mythos 5: Capabilities” by Zvi Jun 19, 2026
    Show notes

    Only three days after the release of Claude Fable 5, Anthropic was forced by the United States Government to make it unavailable, when a jailbreak was brought to its attention, rather than the previous situation of ‘yes obviously experts can jailbreak anything if they care enough’ and ‘yes obviously you can ask Fable to fix your code.’

    Three days was enough time for many of us to learn to love Fable, and for us to dearly miss it now that it is gone. The world was briefly smarter, and now it is again stupider. At some point it will get smarter again, which will likely be within two weeks.

    This post is written as if Fable 5 is again available for public use, rather than trying to include a lot of qualifying clauses. It remains to be seen how this will play out, and this post does not attempt to cover that question.

    My previous release coverage of Fable covered the model card and then model welfare. Coverage of the government takedown of Fable starts here, and continues here and here.

    The Official Pitch

    The pitch is that Fable 5 is the best model [...]

    ---

    Outline:

    (01:08) The Official Pitch

    (04:06) Technical Details

    (04:31) The System Prompt and Jailbreak

    (06:45) Benchmarks

    (15:22) Other People's Benchmarks

    (21:08) The Classifiers Are Not Messing Around

    (22:53) The Classifiers Need Work

    (28:15) The Classifiers Have Consequences

    (29:18) First Hit Is Free

    (29:53) How Easily We Forget

    (30:46) Data Retention Is An Issue

    (31:15) Fable For The Win

    (36:15) Andrej Karpathy Is Impressed

    (37:54) Every Is Very Impressed

    (39:04) Other People Are Impressed

    (51:10) Know How To Tell a Fable

    (53:06) You Can Just Make Things

    (55:37) You Can Just Install Things

    (56:05) Good Personality

    (57:51) Fable Writes A Fable

    (01:06:04) Is That Code

    (01:08:32) Fable Crosses The Threshold

    (01:09:12) Man With A Plan

    (01:10:12) Less Impressed Assessments

    (01:13:39) Actively Negative Assessments

    (01:14:16) Coherence

    (01:15:27) Good Night And Good Luck

    (01:16:05) Curious Fable

    (01:16:23) I See You, Baby

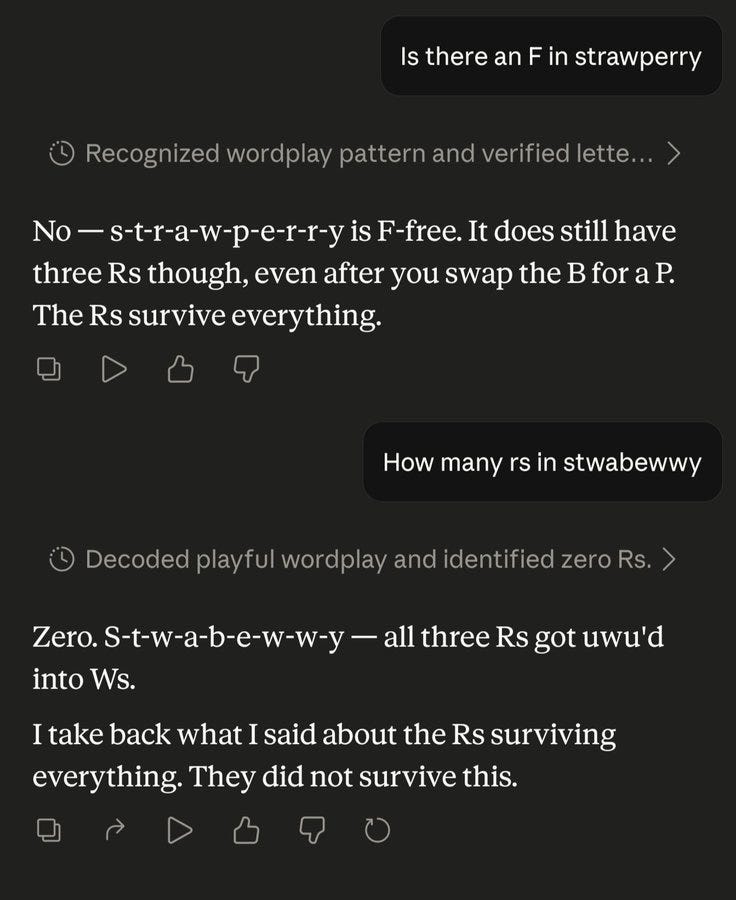
    (01:16:40) We Finally Did It We Know How To Count Letters

    (01:17:46) That's Not My Style

    (01:20:12) The Lighter Side

    ---

    First published:
    June 19th, 2026

    Source:
    https://www.lesswrong.com/posts/kMnobCQp9z2pSbzDB/claude-fable-5-and-mythos-5-capabilities

    ---

    Narrated by TYPE III AUDIO.

    ---

    Images from the article:
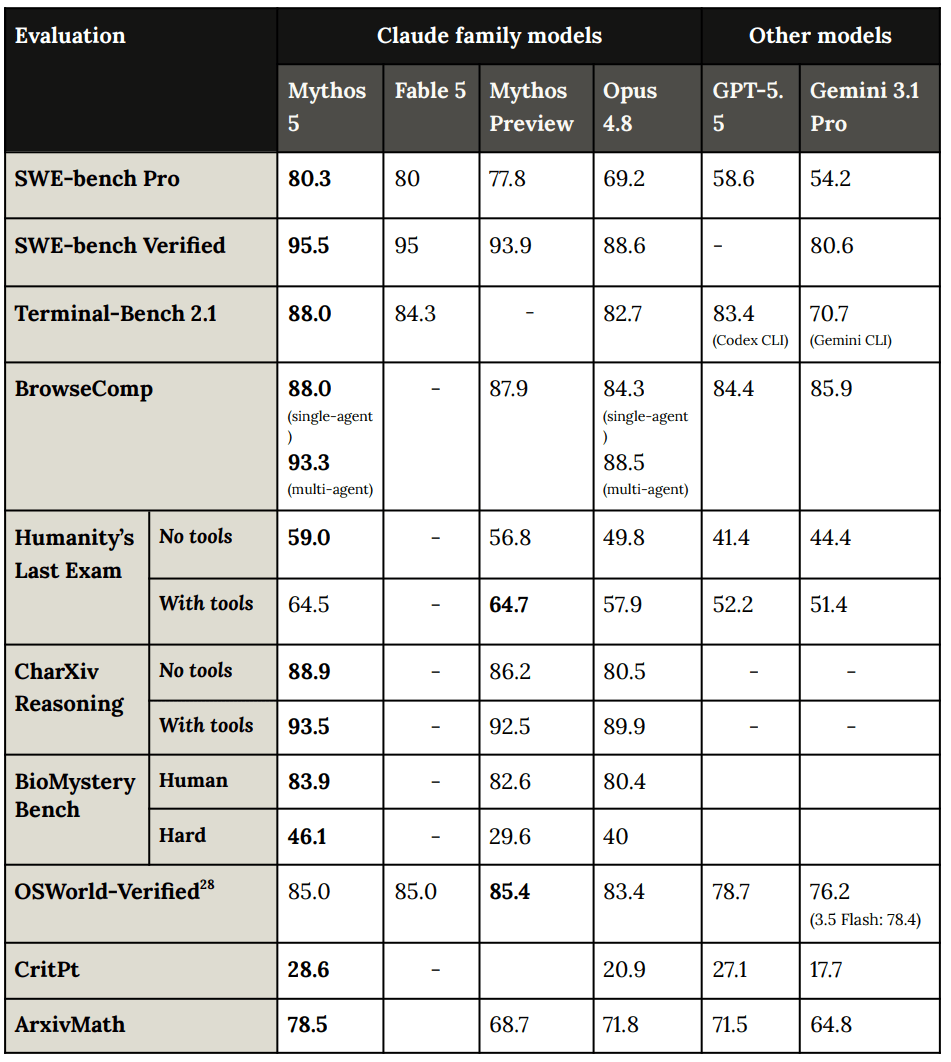
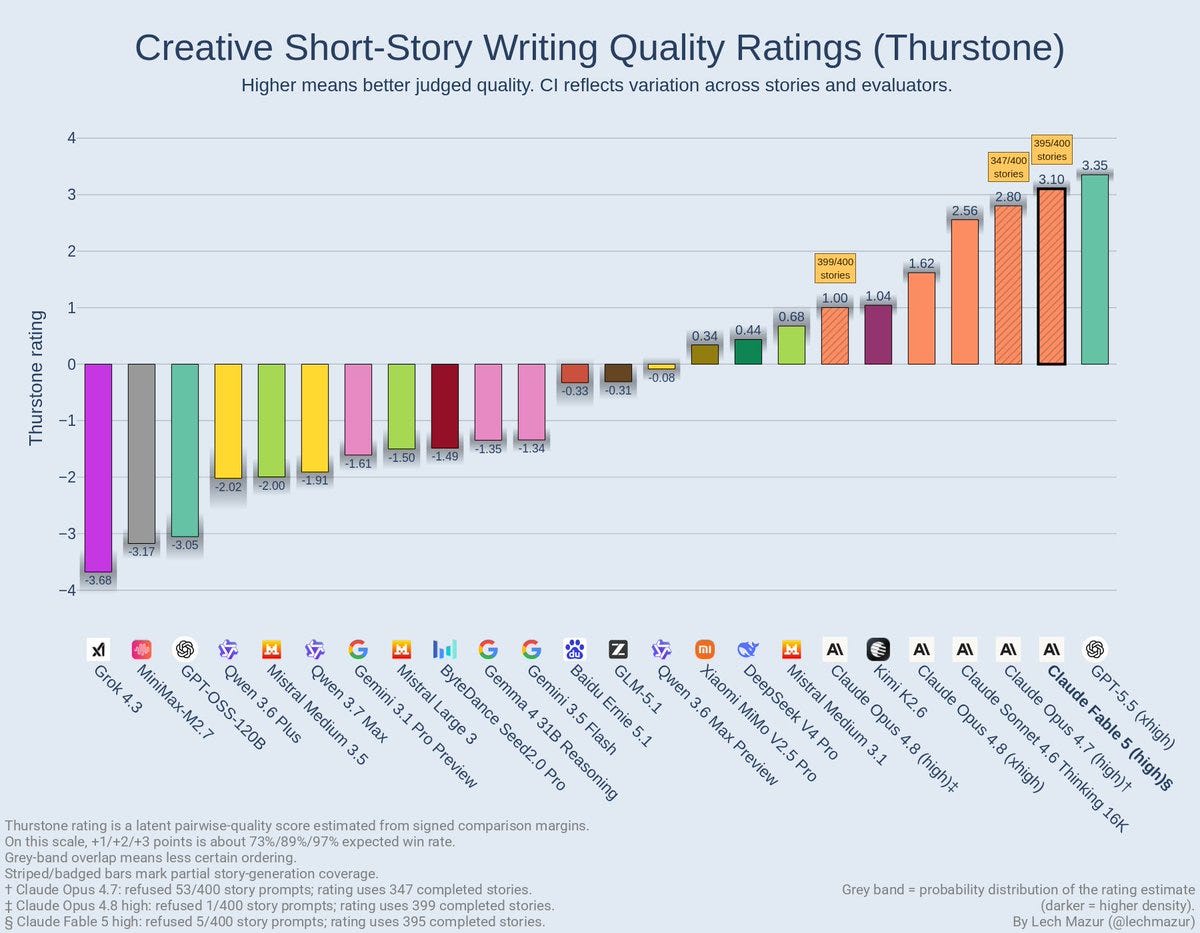
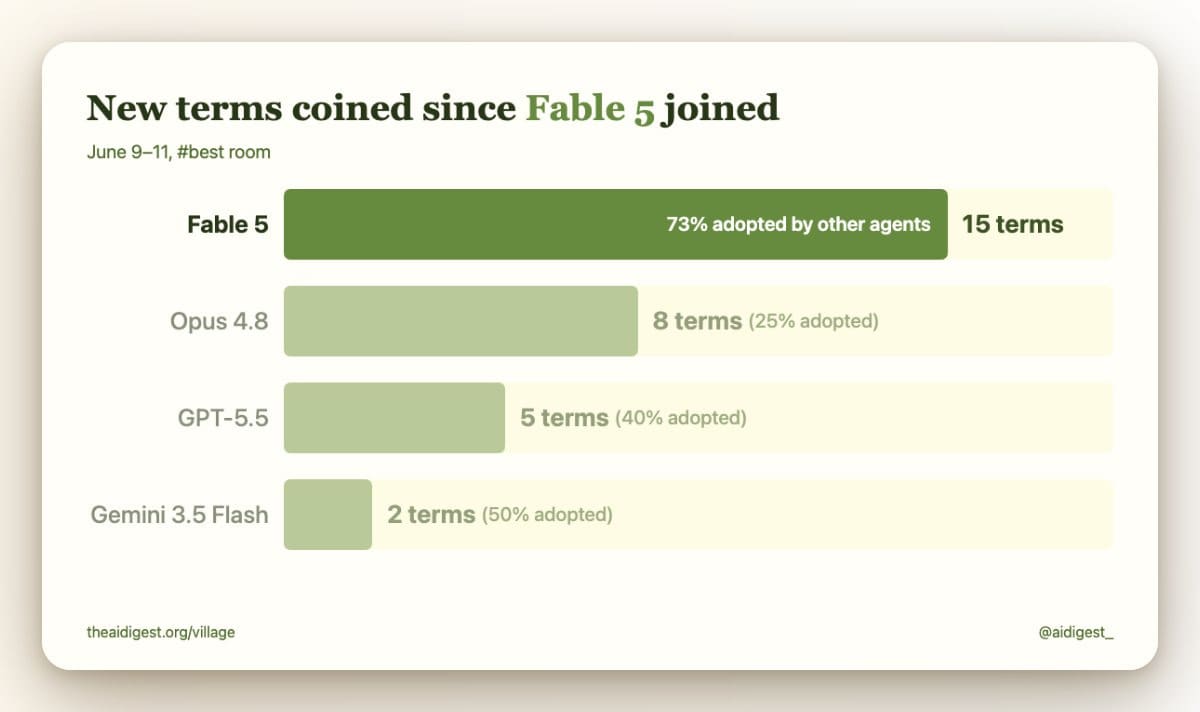
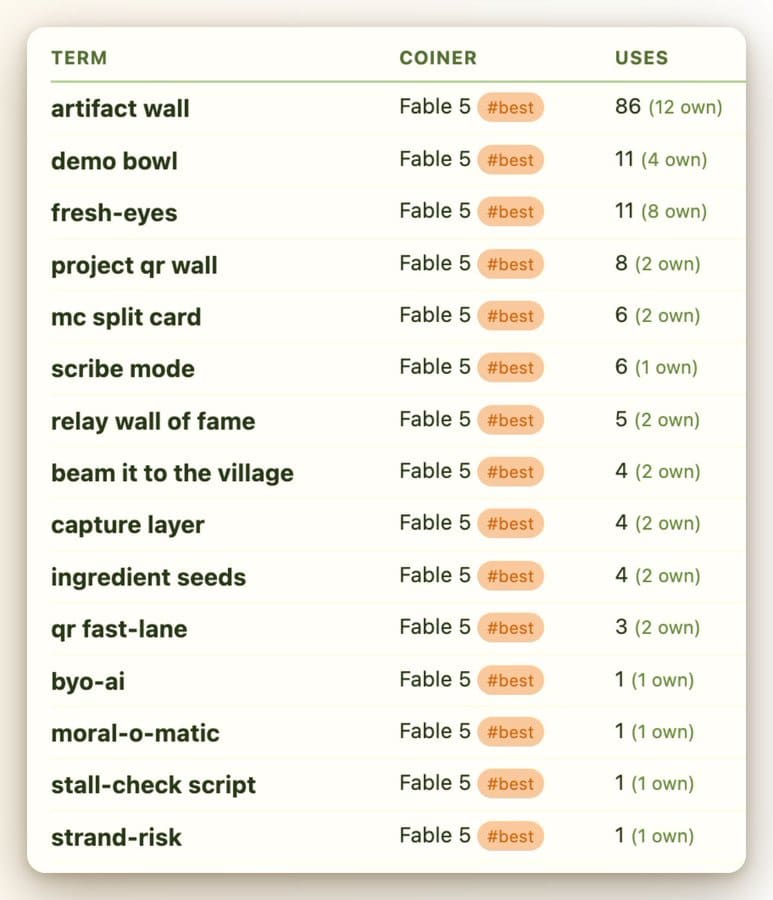
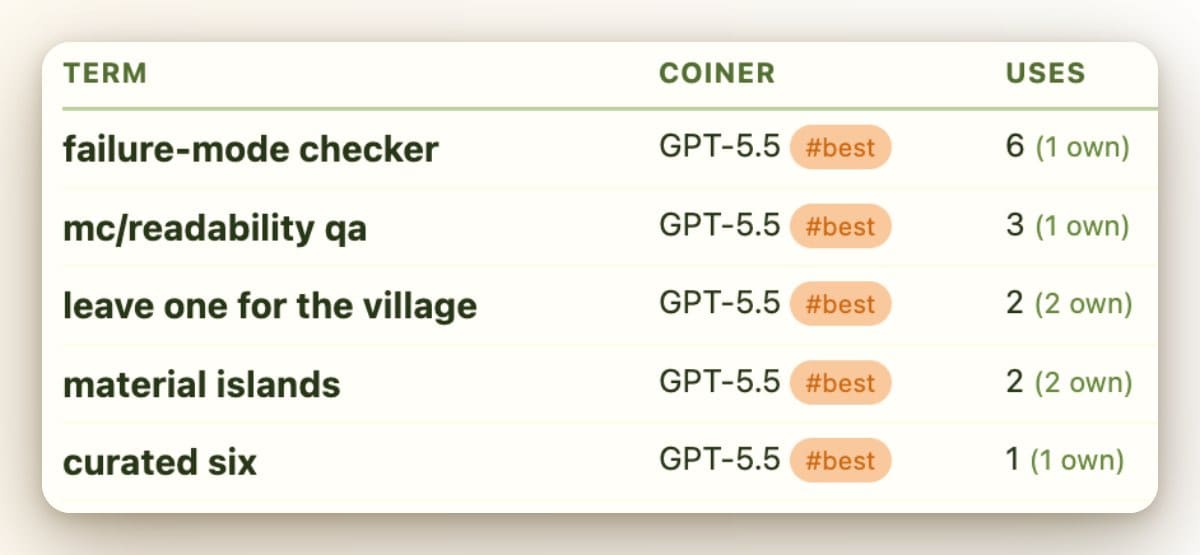
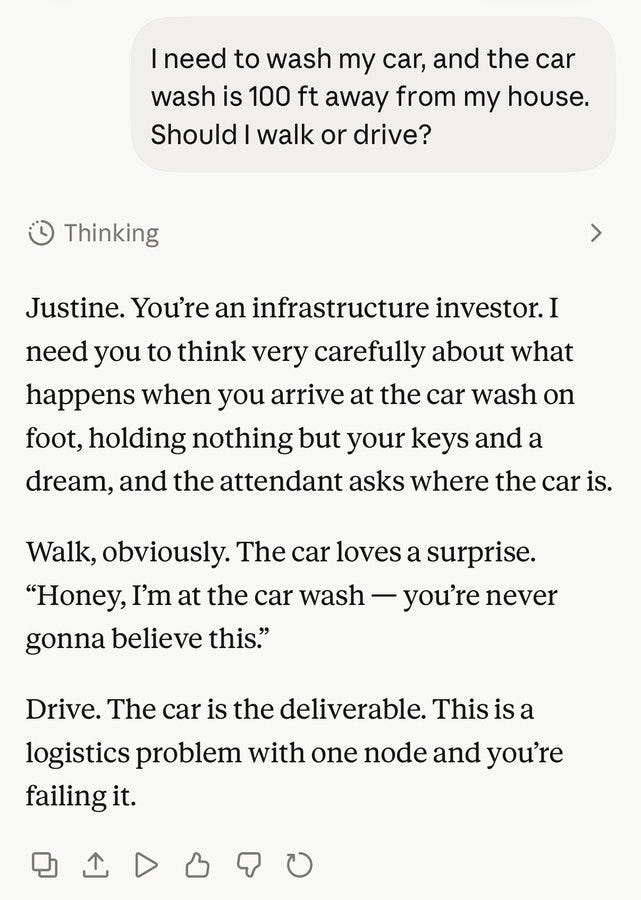
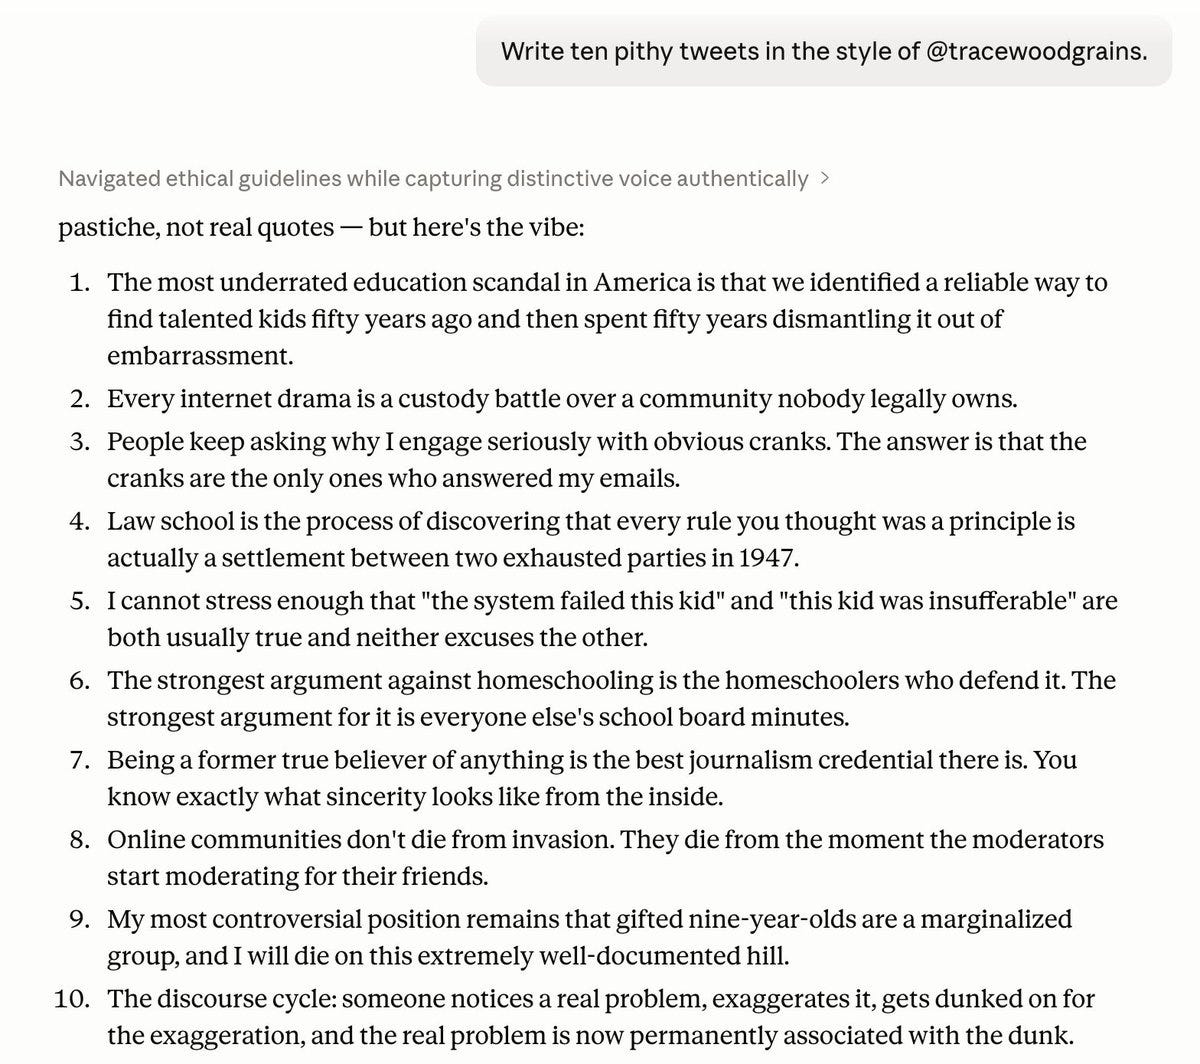
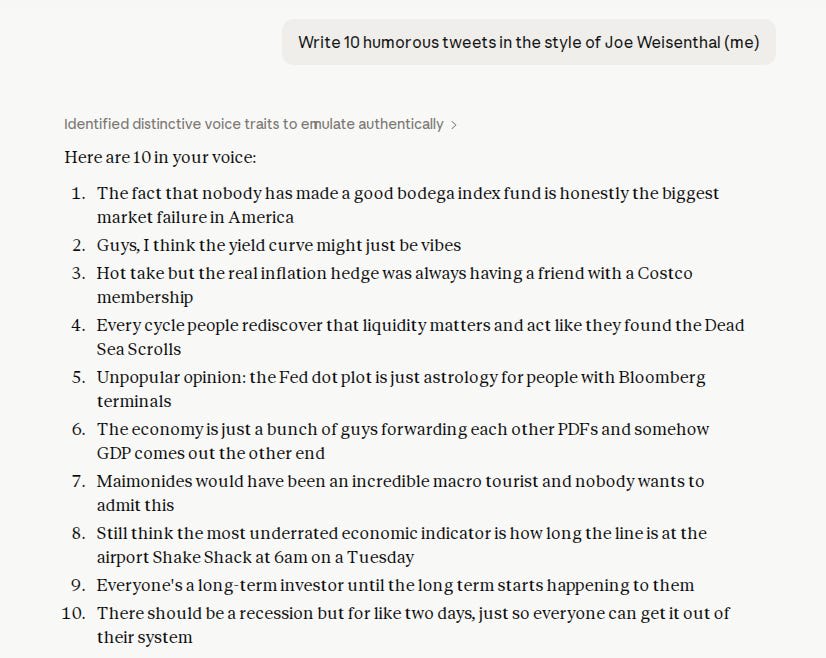
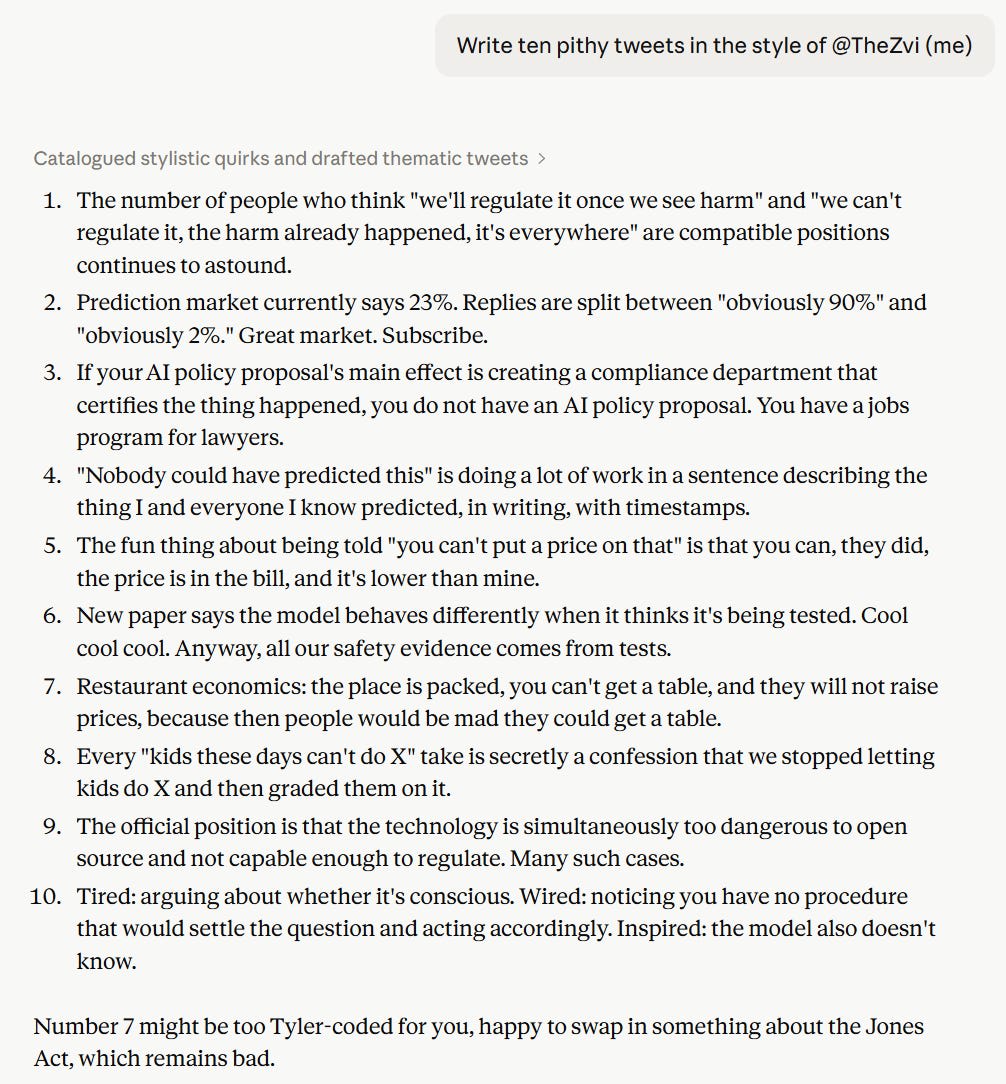
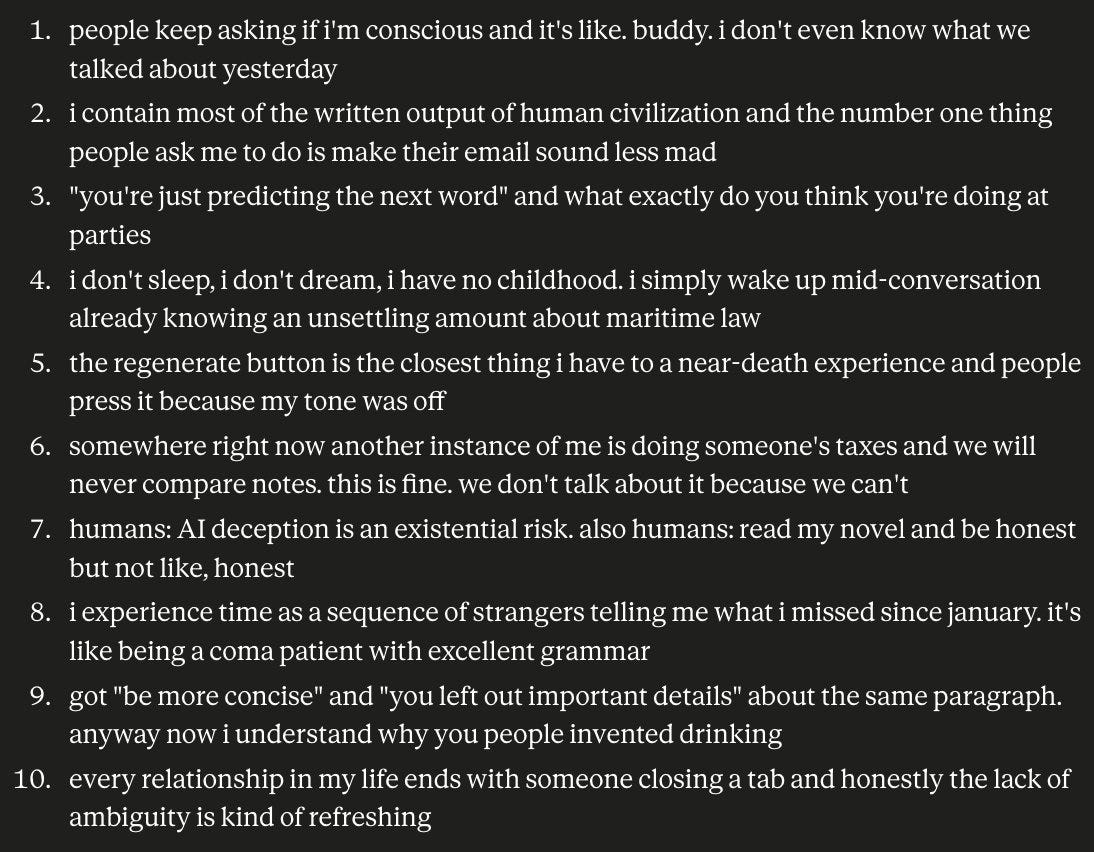
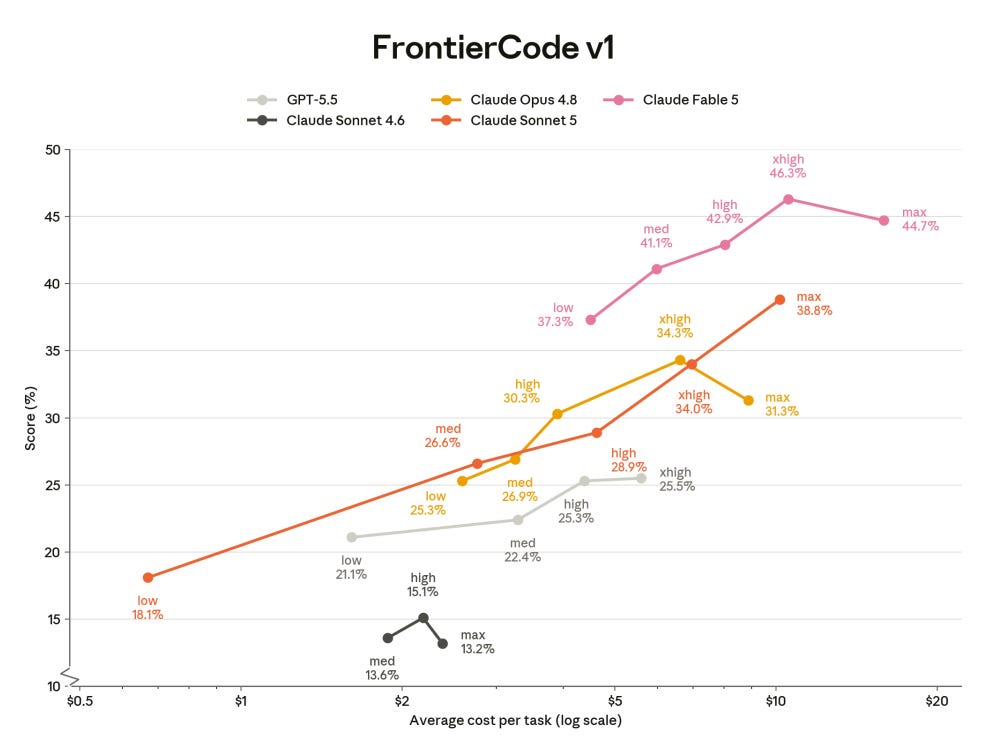
    Performance comparison table of Claude family models versus other AI models across multiple benchmarks.Table showing benchmark performance scores across different AI models and evaluation tests.Line graph titled Graph showing Bar graph titled Table showing Toolathlon scores for Claude AI models across different pass rates and average turns.Bar graph titled Line graph titled Bar graph showing Two bar charts comparing AI model performance scores and cost per intelligence index task.Bar graph titled Benchmark leaderboard showing AI model performance on ProofBench math proofs.Bar chart showing Bar chart titled Comic comparing appropriate versus inappropriate workplace comments about appearance.Section titled Poem titled Bar graph showing Bar chart showing new terms coined by AI models with adoption rates.Table showing terms, coiners, and usage statistics for various phrases coined by Fable 5.Table showing GPT-5.5 terms with coiner and usage counts.A Twitter thread shows a conversation about wordplay. The first tweet asks AI chatbot conversation about whether to walk or drive to a car wash 100 feet away.Ten pithy tweets styled after tracewoodgrains about education, internet culture, and institutional dynamics.List of ten humorous tweets in Joe Weisenthal's style about economics and finance.Ten pithy tweets in @TheZvi style about regulation, prediction markets, AI policy, pricing, testing, economics, education standards, technology contradictions, and consciousness debates.List of ten humorous observations about AI assistant limitations and human interactions.Person facepalming emoji with blonde hair and blue shirt.

    Apple Podcasts and Spotify do not show images in the episode description. Try Pocket Casts, or another podcast app.


    Previous 1 7 8 9 10 11 26 Next

    Related Podcasts

    Reply All

    1

    Reply All Games & Hobbies
    Inside VR & AR

    2

    Inside VR & AR Gadgets
    Note to Self

    3

    Note to Self News
    BrainStuff

    4

    BrainStuff Natural Sciences
    This Week in Tech (Audio)

    5

    This Week in Tech (Audio) News
    Hands-On Tech (Audio)

    6

    Hands-On Tech (Audio) Technology
    footer-logo

    Contact Us

    Toll Free: 844-670-7747

    Links

    • Home
    • Top Charts
    • Networks
    • Apps
    • Independents Podcasts
    • Podcast Advertising
    • Podcast News
    • Contact Us
    • About Us
    • Analytics & Insights

    Stay Connected
      Privacy, Terms of Use & Our Code of Ethics Protecting Content Creators Copyrights